Building a BLIP-2 Application: Vision Transformer and Language Model Integration
Master building a multimodal AI system that combines Vision Transformers and language models to analyze images and generate contextual responses through practical implementation of BLIP-2 architecture.
PyTorch Vision Transformer - Guide to Fine-Tuning for Object Identification
Master fine-tuning Vision Transformers (ViT) in PyTorch through hands-on coding, focusing on object identification implementation with practical examples and real-time coding demonstrations in Google Colab.
PyTorch Vision Transformer: Applying Pre-trained and Fine-tuned ViT Models for Image Classification
Master Vision Transformer implementation in PyTorch using pre-trained and fine-tuned ViT models for image classification, with hands-on practice in Google Colab and Huggingface integration.
Vision Transformer-Based Transfer Learning for Medical Image Classification 2023
Explore cutting-edge Vision Transformer technology for medical image classification, focusing on mammogram analysis and early breast cancer detection through advanced deep learning approaches.
Convergence of Vision and Language in AI - Recent Developments and Projects
Explore the convergence of vision and language in AI with Lucas Beyer from Google DeepMind, covering topics like ViT, PaLI, and the future of multimodal AI architectures.
ConvNeXt- A ConvNet for the 2020s - Paper Explained
Explore ConvNeXt, a modern ConvNet outperforming vision transformers in computer vision tasks. Learn about its design, training, and performance across various applications.
Do Vision Transformers See Like Convolutional Neural Networks - Paper Explained
Explore the differences between Vision Transformers and CNNs, examining feature learning, receptive fields, data impact, and architectural elements for a deeper understanding of these AI models.

Vision Transformers Explained + Fine-Tuning in Python
Explore Vision Transformers (ViT) for image classification, from theory to implementation. Learn about attention mechanisms, patch embeddings, and fine-tuning using Hugging Face in Python.
Stable Diffusion and Friends - High-Resolution Image Synthesis via Two-Stage Generative Models
Explore the evolution of generative image models with Stable Diffusion co-creator Robin Rombach, covering GANs, Transformers, and latent Diffusion models for high-resolution image synthesis and creative applications.
Image Captioning Python App with ViT and GPT2 Using Hugging Face Models - Applied Deep Learning
Learn to create an image captioning app using ViT and GPT2 models from Hugging Face. Build a Gradio interface and deploy it on the Model Hub for easy access and sharing.
Fine-Tuning ViT Classifier with Retina Images and Converting to ONNX - Video 3
Fine-tune a Vision Transformer for diabetic retinopathy detection using EyeQ dataset and convert the model to ONNX format for efficient deployment.
LLMOps: Inference of Fine-Tuned ViT Classifier on CPU with C#
Perform CPU inference on a fine-tuned Vision Transformer using C# and ONNX format for efficient image classification in machine learning projects.
Intro to Dense Vectors for NLP and Vision
Explore dense vector representations in NLP and computer vision, from word2vec to modern transformer models, with practical Python implementations and applications.
Training Vision Transformers for Real-Time Image Classification
Master Vision Transformer implementation for real-time emotion classification in video, including hands-on training techniques and comparison with CLIP for zero-shot classification tasks.
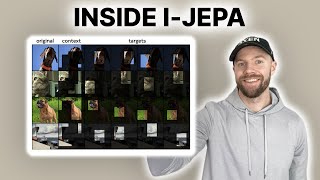
Understanding I-JEPA: A Non-Generative Approach to Self-Supervised Learning from Images
Dive into Meta AI's I-JEPA framework for self-supervised image learning, exploring its architecture, methodology, and advantages over traditional approaches in computer vision and neural networks.
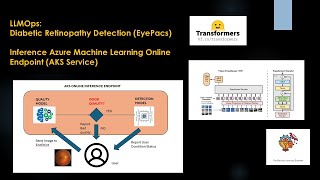
Fine-Tuning Vision Transformer for Retina Image Classification - Inference on Azure ML AKS
Fine-tune a Vision Transformer for diabetic retinopathy detection using EyeQ dataset and deploy on Azure ML with AKS for managed inference.
Deep Learning for Global Climate Monitoring and Predictions
Explore advanced deep learning techniques for climate prediction, including few-shot learning and data assimilation, to enhance accuracy in global climate monitoring and forecasting.
Fine-Tuning Vision Transformer Classifier for EyePacs Dataset Quality Model - Part 1
Fine-tune a Vision Transformer for image quality assessment using the EyeQ dataset, a subset of EyePacs, to enhance diabetic retinopathy detection capabilities.
Fine-Tuning Vision Transformer for Diabetic Retinopathy Detection - Part 2
Fine-tune a Vision Transformer for diabetic retinopathy detection using EyeQ dataset. Learn to adapt pretrained models for specialized medical image classification tasks.
Fine-Tuning ViT Classifier for EyePacs Dataset Quality Model - Tutorial en Español
Personaliza un Vision Transformer con tu propio dataset para analizar la calidad de imágenes oculares utilizando el conjunto de datos EyeQ, un subconjunto de EyePacs.
Fine-Tuning ViT Classifier with Custom Data and Docker Inference - Part 4
Fine-tune a ViT classifier with custom data and deploy using Docker and FastAPI for efficient image classification in production environments.