Data Preparation and Transformer Models - Introduction to Text and Image Processing
Master data preparation techniques for transformers, including text and image processing, and understand the fundamentals of transformer architecture and pretraining methods.
Pre-Training BERT from Scratch - Building, Fine-Tuning, and Running Inference with KERAS NLP
Master BERT model pre-training, fine-tuning, and inference using TF2 and KERAS NLP through hands-on implementation of transformers for domain-specific tasks.

Pre-Training BERT from Scratch for Domain-Specific Knowledge Using PyTorch - Part 51
Master BERT model pre-training from scratch using PyTorch, focusing on domain-specific data. Build custom tokenizers, design architecture, and implement masked language modeling for specialized neural information retrieval systems.
Deep Learning: Transformers and Encoder-Decoder Architecture - Lecture 10
Dive into transformer architectures, exploring encoder-decoder mechanisms and positional embeddings for advanced deep learning applications.
Deep Learning: BERT and GPT Models - Lecture 11
Dive into the evolution and architecture of transformer models, exploring BERT, GPT series, and T5 to understand their impact on modern natural language processing.
Attention Mechanism and Self-Attention in Deep Learning - Lecture 9
Dive into attention mechanisms and self-attention concepts in deep learning, exploring their revolutionary impact on NLP and discovering practical applications in sequence models.
Variational Autoencoders and Performers in Deep Learning - Lecture 15
Delve into advanced deep learning concepts including Variational Autoencoders (VAE), variational inference, ELBO computation, and Performer-based Transformer architectures.
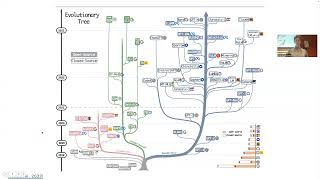
Transformer Types and Practical Considerations
Explore different transformer architectures and key implementation factors for building effective natural language processing models and applications.
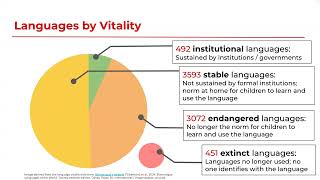
Multilingual Large Language Models - Advances in Generative AI
Explore the latest developments in multilingual large language models, their capabilities, challenges, and future potential in the evolving landscape of generative AI.
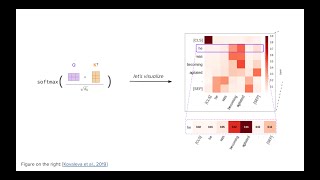
Attention and Transformer Encoder Architecture
Master the inner workings of Transformer encoders and attention mechanisms in deep learning, exploring their architecture, self-attention calculations, and practical applications in modern AI.
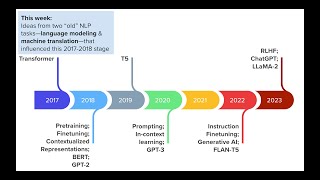
Introduction to Language Modeling: From N-grams to Neural Networks
Explore the evolution of language modeling, from n-grams to neural architectures, covering key concepts like embeddings, transformers, and RLHF implementations.
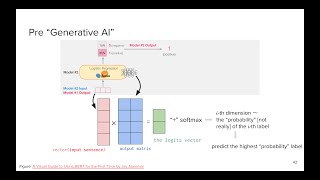
Transformer Decoder - Pretraining and Finetuning
Master transformer decoder architecture fundamentals, exploring pretraining methods and effective finetuning techniques for advanced natural language processing applications.
The Inner Workings of Large Language Models - Visualizing Self-Attention Mechanisms
Dive into the mechanics of Large Language Models, exploring self-attention mechanisms, architectural designs, and performance optimization through clear visualizations and practical examples.
AI in Political Science and Social Psychology - Predicting Public Opinion with Language Models
Explore how AI language models predict public opinion, analyze media effects on society, and revolutionize political science research through cutting-edge BERT systems and transformer architectures.
Fine-Tuning Code Language Models - A Practical Guide
Master the process of fine-tuning Code LLMs using instruction datasets, from environment setup to implementation, with hands-on demonstrations using StarCoder and practical GPU requirements guidance.
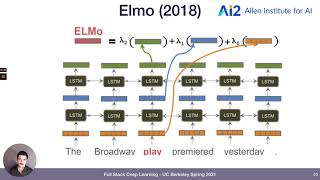
Transfer Learning and Transformers - Full Stack Deep Learning - Spring 2021
Explore transfer learning's evolution from computer vision to NLP, diving into embeddings, language models, and the revolutionary Transformer architecture. Gain insights into various models and their applications.
Transformers Explained - Part 1: Generative Music AI
Comprehensive exploration of transformer architectures in AI, covering intuition, theory, and mathematical formalization, with focus on their application in music and audio processing.

Mamba: Linear-Time Sequence Modeling with Selective State Spaces
Explore Mamba, a novel linear-time sequence modeling architecture using selective state spaces. Learn about its advantages over Transformers and its applications in language, audio, and genomics.
Transformers for Generative Music AI - Part 2: Decoder and Music Generation
Explore transformer architecture for music AI, focusing on decoder components, masked attention, and practical tips for generating music. Dive into future research and neuro-symbolic integration for robust music generation.
Melody Generation with Transformers - Generative Music AI
Implement a transformer architecture in TensorFlow for end-to-end melody generation. Learn melody encoding, dataset preprocessing, model building, training, and inference techniques for AI-driven music creation.
Modular and Composable Transfer Learning
Explore parameter-efficient transfer learning with adapters, enabling modular and composable fine-tuning for improved task performance and cross-lingual generalization in transformer-based models.