Two Stories in Mechanistic Interpretation of Natural and Artificial Neural Computation
Explore two stories in mechanistic interpretation of neural computation, covering in-context learning in Transformers and insights into linear regression tasks using linear attention models.

Fine-Tuning BERT for Text Classification - Python Code Tutorial
Dive into fine-tuning BERT for text classification, focusing on phishing URL detection. Learn key concepts and implement Python code to enhance your natural language processing skills.
Generative AI Models Through the Lens of Dense Associative Memory
Explore Dense Associative Memories and their relationship to transformers and diffusion models. Gain insights into energy-based modeling and the memorization-generalization transition in AI.
Emergence and Grokking in Simple Neural Architectures
Dive into emergence and grokking in simple neural architectures. Explore MLPs' remarkable behaviors, feature-learning kernel machines, and their implications for understanding modern deep learning phenomena.
Scaling Insights from Infinite-Width Theory for Next Generation Architectures and Learning Paradigms
Explore scaling insights from infinite-width theory for advanced architectures and learning paradigms. Gain understanding of optimal scaling rules across various models and their impact on training stability and generalization.
Toward Understanding In-Context Learning
Dive into the mechanisms of in-context learning in large language models, exploring theoretical explanations and simplified data distributions with Stanford's Tengyu Ma.
Large Language Models and Transformers: Perspectives from Physics, Neuroscience, and Theory
Explore perspectives on large language models and transformers from physics, neuroscience, and theory with Stanford's Surya Ganguli in this insightful Simons Institute lecture.
Introduction to Transformers
Dive into the fundamentals of Transformers, exploring their architecture and applications in large language models with expert insights from Columbia University.
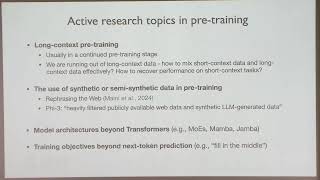
Training Large Language Models: Practices and Research Questions
Explore best practices and open research questions in training large language models, covering pre-training, post-training, data curation, algorithms, and safety mitigations.
The Pitfalls of Next-token Prediction in Language Models
Explore the limitations of next-token prediction in AI, examining its challenges in modeling human intelligence and potential solutions beyond this paradigm.
TinyEngine: Transformer and LLM - Lecture 12
Dive into Transformer and LLM architectures, exploring their efficiency and applications in machine learning, guided by Prof. Song Han's expertise.
TinyEngine: Transformer and Large Language Models - Lecture 12
Dive into Transformer and LLM architectures, exploring their applications and optimizations for efficient machine learning on resource-constrained devices.

Transformers and BERT Implementation
Learn to implement Transformers and BERT models, fine-tune pretrained models, and create custom question-answering systems using Hugging Face's powerful NLP tools.
NLP with BERT
Explore transformers and BERT in NLP, covering their architecture, applications, and hands-on implementation using PyTorch. Learn about sequence-to-sequence models, text summarization, and practical use cases.
SPLADE - The First Search Model to Beat BM25
Explore SPLADE, a groundbreaking sparse embedding model for AI-powered search. Learn its advantages over traditional methods, implementation techniques, and potential future developments in vector search technology.
How Do Transformers Work? - A Deep Dive into Neural Network Architecture
Dive into the fundamental mechanics and architecture of transformer models, exploring their key components and operational principles through expert insights from MIT's research.
Trillion Dollar Words in Julia - Natural Language Processing for Financial Markets
Explore how to predict financial market impacts from Federal Reserve communications using Julia and RoBERTa models, with practical implementations for analyzing monetary policy language.
Pre-training and Fine-tuning of Code Generation Models
探索代码生成模型的构建过程,包括StarCoder的训练、负责任的AI实践,以及如何利用开源库来部署和使用这些强大的模型。
Inferencia Eficiente de LLMs en CPUs y GPUs Intel con Neural Speed
Optimiza la inferencia de LLMs en hardware Intel utilizando Neural Speed para mejorar el rendimiento en CPUs y GPUs.
ML and MLOps with Databricks: LLMOps, MLFlow, Transformers, and Databricks - Spanish
Aprende LLMOps con MLFlow y Databricks: implementa y gestiona modelos de lenguaje a gran escala utilizando herramientas de vanguardia en español.
ML and MLOps with Databricks: LLMs Using HuggingFace Transformers - Spanish
Explora LLMs con HuggingFace Transformers en Databricks: summarization, traducción, análisis de sentimientos, zero-shot y few-shot prompting.