Provably Learning a Multi-Head Attention Layer
Explore algorithmic approaches and computational challenges in learning multi-head attention layers, with insights on provable algorithms and lower bounds for transformer model learnability.
Embeddings, Transformers, and Tokens - Introduction to Modern Generative AI Concepts
Demystify AI jargon and history, from Turing to ChatGPT. Learn key concepts like tokens and transformers, and discover open-source projects to run generative AI models on your own computer for learning and productivity.

xLSTM - Extended Long Short-Term Memory
Explore xLSTM architecture combining LSTM recurrency with transformer-scale training, achieving impressive language modeling results through exponential gating and modified memory structures.

Object Detection Using Detection Transformer (DETR) for Bone Fracture Dataset
Learn to build an advanced object detection system using DETR, covering data preparation, model implementation, training, and inference with PyTorch, Transformers, and PyTorch Lightning.
Brain-on-Switch: Advanced Intelligent Network Data Plane via NN-Driven Traffic Analysis
Innovative approach to enable neural network-driven traffic analysis at line-speed in programmable networks, overcoming limitations of tree-based models and enhancing intelligent network data plane capabilities.
Visual Introduction to Transformers and GPTs - Deep Learning Chapter 5
Visual introduction to transformers and GPTs, covering key concepts like word embeddings, deep learning premise, and softmax. Explores the inner workings of these models with clear animations and explanations.
Deepsets, Graph Neural Networks, and Transformers in High Energy Physics - Lecture 6
Explore advanced machine learning techniques like Deepsets, Graph Neural Networks, and Transformers, with applications in high energy physics research and data analysis.
ML and MLOps with Databricks: LLMOps, MLFlow, Transformers, and Databricks
Explore LLMOps, MLFlow, and Databricks for advanced machine learning operations. Master transformers and enhance your data science skills.
MLOps with MLflow: Fine-Tuning LLMs - Tracking Experiments and Logging Models
Fine-tune LLMs, track experiments, and log models using MLflow for efficient MLOps practices in data science and machine learning projects.
LLMOps: Converting Fine-Tuned ViT Classifier to ONNX for CPU Inference
Convert a fine-tuned ViT Transformer to ONNX format and perform CPU inference, enhancing model portability and efficiency for custom image classification tasks.
Converting BERT to ONNX and Inference with BERTTokenizer for C# - Machine Learning and Data Science
Convert Bert model to ONNX format and create a C# app using BERTTokenizer for inference with ONNX transformer models.
Text Summary Model with BERT
Explore BERT-based text summarization: task overview, algorithm implementation, and model weight importing for effective summary generation.
Transformers Meet Directed Graphs - Exploring Direction-Aware Positional Encodings
Explore direction-aware positional encodings for transformers on directed graphs, enhancing performance in code understanding and sorting network correctness testing.
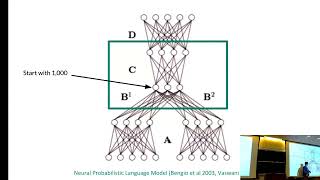
Learning Neural Network Hyperparameters for Machine Translation - 2019
Explore neural network hyperparameter optimization for machine translation, focusing on efficient methods to learn parameters during training without extensive grid searches.
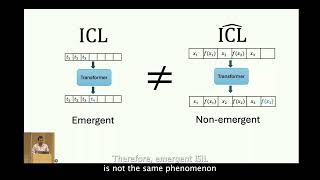
Do Pretrained Transformers Learn In-Context by Gradient Descent?
Explore the relationship between In-Context Learning and Gradient Descent in large language models, examining theoretical connections and empirical evidence from pre-trained transformers.
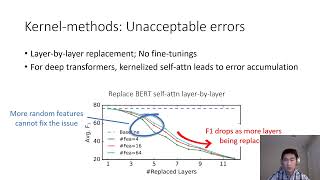
The NLP Task Effectiveness of Long-Range Transformers
Explore the effectiveness of long-range Transformer variants on NLP tasks, comparing their performance and analyzing attention behaviors to uncover strengths and limitations.
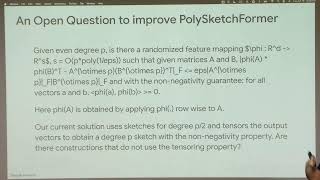
ML Efficiency for Large Models - From Data Efficiency to Faster Transformers
Explore algorithmic solutions for efficient scaling of large ML models, covering data efficiency, model efficiency, and faster attention mechanisms for improved training and inference.
Machine Learning for Developer Productivity
Explore innovative ML-driven software productivity tools, their impact on developer efficiency, and industry experiences. Gain insights into code prediction, autocomplete advancements, and future possibilities.
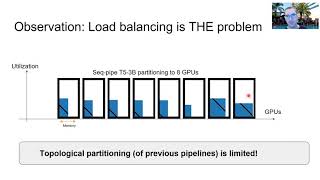
Fine-Tuning Giant Neural Networks on Commodity Hardware with Automatic Pipeline Model Parallelism
Explore fine-tuning giant neural networks on commodity hardware using FTPipe, a system enabling multi-GPU execution through innovative model partitioning and task allocation techniques.
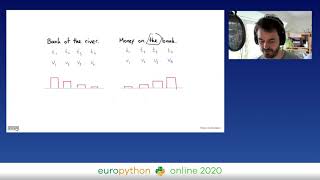
Why Transformers Work
Explore the inner workings of transformers in machine learning, their advantages over RNNs, and applications in NLP and dialogue handling, with live demos and clear explanations.
Deep Learning - The Final Frontier for Time Series Analysis
Explore deep learning's potential in time series analysis, covering classification, prediction, and anomaly detection. Learn how neural networks can revolutionize processing of sequential data across various domains.