GenAI and Datacomp: Creating the Largest Public Multimodal Dataset in Academia
Explore academia's role in GenAI, focusing on large-scale dataset management. Learn about AI-driven data cleaning, data-centric AI, legal challenges, and synthetic dataset potential in this insightful talk.

Synthetic Data Generation and Applications in Python
Discover how to generate synthetic data for machine learning and data analysis projects, with practical Python examples and implementation strategies.
AI-Driven Solutions for Text Anonymization - Implementing Machine Learning for Data Privacy
Explore AI-driven text anonymization techniques, from data labeling and NLP model training to implementing MLOps principles and human-in-the-loop processes for enhanced data privacy protection.
Leveraging GANs for Building Synthetic Data
Explore GANs for synthetic data generation to overcome data scarcity, preserve privacy, and enhance machine learning model training across various domains.
Synthetic Data for Computer Vision Problems When Real Annotation Is Too Expensive
Explore synthetic data generation for computer vision tasks when labeled data is scarce. Learn tools and approaches to build effective models using primarily synthetic data.
Crafting Flight Simulations: The Art of Synthetic Data Generation
Discover how synthetic data creates rich scenarios for flight simulations, mitigating real-world data risks while enhancing training and development.
Synthetic Data for AI, and AI for Synthetic Data in Open Source
Explore synthetic data generation for AI and its applications in open source, featuring live demos and discussions on biases and use cases.
Human-in-the-Loop Mixup: Aligning Synthetic Data with Human Perception - Oral Session 2
Explore human-aligned synthetic data in machine learning, focusing on mixup regularization. Discover how perceptual judgments and uncertainties can enhance model reliability and generalization.
BLEURT - Learning Robust Metrics for Text Generation
Explora BLEURT, una métrica de evaluación basada en BERT para generación de texto, su preentrenamiento con datos sintéticos y su capacidad de modelar juicios humanos con pocos ejemplos.
Fake It Till You Make It - An Introduction to Synthetic Data
Explore synthetic data generation for GDPR compliance, addressing privacy concerns while maintaining data usability. Learn practical techniques using Python for testing, debugging, and analytics.
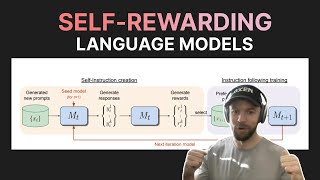
Deep Dive Into Self-Rewarding Language Models - Training Models as Their Own Judges
Explore how language models can be trained to evaluate and improve themselves, eliminating the need for human-labeled data while achieving superior performance in AI development and training.
Understanding How Llama 3.1 Works - A Technical Deep Dive
Dive into Meta's groundbreaking Llama 3 architecture, exploring pre-training techniques, model capabilities, synthetic data quality, and implementation strategies for advanced AI development.
The Transformative Impact of AI on Security and Security on AI
Explore how AI transforms security strategies through synthetic data, agents, and RAG technologies, while learning to leverage these tools for enhanced enterprise defense and protection.
Why Synthetic Data is Needed for AI Fairness and Explainability
Discover how synthetic data enhances AI fairness and explainability through machine learning techniques, focusing on audio data modeling and source separation applications.
Making GenAI Safe, Trustworthy and Fit for Purpose with Auto Alignment
Enhance fairness, robustness, and safety of generative AI through alignment templating. Learn to measure model performance, improve with minimal human intervention, and adapt for specific use cases.
Everything I Know About Data Science I Learned from Model Railroading
Explore parallels between data science and model railroading, uncovering valuable insights for building real-world models and improving data science practices.
Navigating the AI Frontier: The Power of Synthetic Data and Agent Evaluations in LLM Development
Explore synthetic data and agent evaluations in LLM development. Learn strategies for enhancing model behavior, prototyping, testing, and fine-tuning to build robust AI applications.
Synthetic Data - Friend or Foe in the Age of Scaling?
Explore synthetic data's impact on AI scaling laws, model performance, and potential degeneration. Analyze theoretical frameworks and experimental findings for future AI development challenges.

LLaMA 3 Deep Dive - Synthetic Data, Privacy, and Model Architecture
Explore LLaMA 3's innovations with Meta's Thomas Scialom, covering synthetic data, privacy concerns, scaling techniques, and architectural choices in this in-depth discussion on advanced language models.
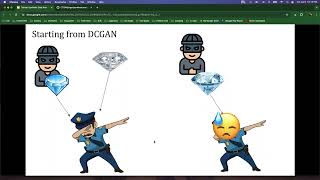
Generate Synthetic Tabular Data with GANs
Explore generating synthetic tabular data using GANs. Learn how TGANs work, see experiments and results, and discover tips for improving performance in this informative talk.
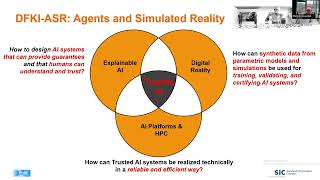
Digital Reality: From Learned Models via Synthetic Data to Trusted-AI - and Back
Explore AI systems' understanding of complex reality through modular learning, simulations, and synthetic data generation. Discover the "Digital Reality" approach combining modeling, AI, and high-performance computing.