Don't Stop at Data Democratization - Data Literacy and Diversity in AI Systems
Discover how synthetic data drives innovation by enabling data diversity and equitable AI systems, while promoting inclusive access to data resources for all professionals.
The Synthetic Data Advantage - Getting Both AI Privacy and Explainability
Discover how synthetic data revolutionizes AI development by enabling privacy-preserving machine learning, streamlined data access, and enhanced explainability while exploring practical implementation techniques.
Realistic Synthetic Data Generation at Scale - Modeling Production Data Without Exposure
Discover how to generate large-scale synthetic test data that mirrors production patterns without exposing sensitive information, using modeling techniques for directory trees, files, and various data characteristics.

SetFit and SBERT: Zero-Shot Classification with Synthetic Data Sets - Part 47
Discover how to leverage SetFit and SBERT for zero-shot classification by creating and utilizing synthetic data, enhancing performance in both zero-shot and few-shot scenarios.
Creating Self-Instruct Data Sets for LLM Fine-Tuning with ChatGPT
Master the creation of synthetic instruction datasets using ChatGPT and GPT-4 for fine-tuning language models, covering data generation, multi-task training, and task decomposition techniques.
Synthesizing Plausible Privacy-Preserving Location Traces
Explore techniques for generating synthetic location data that preserves privacy while maintaining statistical similarity to real human mobility patterns, enhancing protection against inference attacks.
Data Management Fundamentals
Explore data management fundamentals, resources, and techniques for enhancing data discoverability and comprehension in scientific work and publications.
Dealing with Privacy, Bias and Drift in Synthetic Primary Care Data
Explore synthetic healthcare data generation, addressing privacy concerns, bias detection, and concept drift in evolving medical datasets for improved research and policy-making.
Synthetic Data for Identity Systems - Face Synthesis Detection
Explore face synthesis detection techniques for identity systems, focusing on synthetic data generation and its applications in enhancing security and privacy.
ChatGPT 3.5 Turbo Fine-Tuning Tutorial - Specific Tasks with Synthetic Data
Step-by-step guide to fine-tuning ChatGPT 3.5 Turbo for specific tasks using synthetic data, covering when and why to fine-tune, data creation, dataset cleaning, and model testing.
The Art and Tech of Generating Secure and Authentic Synthetic Data
Explore techniques for creating secure synthetic data, including redaction, anonymization, and differential privacy, with practical examples and future developments.
Beyond 2026 - The Role of AI-Generated Content in Machine Learning
Explore the impact of AI-generated content on machine learning, addressing bias challenges and strategies for the future of ML in light of evolving regulations and technological advancements.
Creating Synthetic Data with Langchain and OpenAI for Data Science and Machine Learning
Create synthetic data using Langchain and OpenAI for machine learning applications. Learn techniques to generate realistic datasets for training and testing models.
Synthetic Data in Medical Imaging: Are We There Yet?
Explore synthetic data's potential and challenges in medical imaging, focusing on recent advancements and future prospects for improved healthcare applications.
Hacking the Pentagon - How a Rebel Alliance Shifts Culture to Protect National Security
Explore how a rebel alliance shifts Pentagon culture to enhance national security through innovative hacking, data science, and digital transformation strategies.
How Data and Analytics Unleash Innovation and Transform Uncertainty
Explore how data and analytics drive innovation and transform uncertainty in business. Learn strategies for leveraging metadata, synthetic data, and augmented analytics to make better decisions and maximize outcomes.
Transforming Transportation with the Metaverse and AI on Microsoft Azure
Explore how NVIDIA Omniverse and DRIVE Sim on Azure revolutionize vehicle development, from design to customer experience, using digital twins, AI, and immersive technologies.
Differential Privacy and the People's Data
Explore differential privacy mechanisms, applications, and challenges in data protection. Insights from Cynthia Dwork on privacy-preserving techniques, real-world implementations, and future directions.
How Generative AI Brings Synthetic Data to Software Engineering
Explore the impact of generative AI on software engineering, focusing on synthetic data creation and its applications in development processes and testing methodologies.
Craft Complex Mock Data Using Graph-Based Configuration Files
Master the creation of complex, interconnected mock datasets using Python's graph-data-generator package through JSON configuration files for more efficient development and testing workflows.
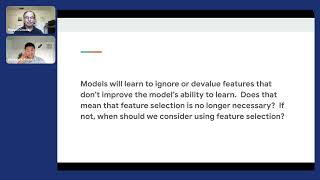
Practical Paths to Data-Centric AI
Explore data-centric AI with Google experts, covering data quality, feature selection, and large language model deployment. Learn about synthetic data, weak supervision, and data governance.