Lambda Functions and List Operations in DuckDB SQL
Explore DuckDB's innovative approach to handling LIST-type operations and Python-style list comprehension in SQL, focusing on efficient processing of nested data formats like JSON for enhanced analytics performance.
Data Mesh for Instant Query - Why Trino on Data Mesh
Discover how modern data platforms are evolving from producer-centric to consumer-centric approaches, exploring Trino's role in data mesh architecture for efficient cross-platform data analysis and instant querying.
SQL 엔진을 더욱 강력하게 - 비정형 데이터 분석 정상에 서다
Discover how SK Hynix transforms unstructured semiconductor equipment data into structured formats using TrinoPy+, an enhanced SQL solution that enables seamless data preprocessing, analysis, and loading with single SQL queries.
Modern Industrial Data Platform - Technical Deep Dive
Dive into SKT's innovative approach to modern industrial data platforms, exploring on-demand data mesh architecture and active metadata management for enhanced data pipeline efficiency.
REDLake Azure - Enterprise Data Lake and Business Satellites
Explore Bosch's REDLake Azure enterprise data repository system, focusing on data collection, storage, refinement, and analysis using Azure Synapse Analytics and Power BI for global accessibility.
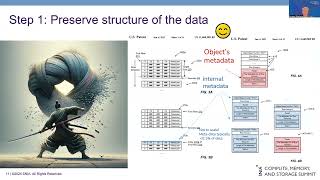
A Practical Approach to Device-Level Analytical Offloads
Discover how to transform storage devices into analytical processing engines through device-level computational offloads, reducing data transfer while maintaining simplicity and compatibility with existing APIs.
Translating Canonical SQL to Imperative Code in Coq
Explore a mechanically verified compiler translating SQL to imperative code, addressing implementation challenges and leveraging formalization advances in query compilation.
Automated Translation of Functional Big Data Queries to SQL
Explore automated translation of functional big data queries to SQL, improving efficiency while maintaining abstraction benefits. Learn about novel column-wise decomposition for query synthesis.
Indexed Streams - A Formal Intermediate Representation for Fused Contraction Programs
Explore a formal operational model for fused execution of contraction languages, covering sparse tensor and relational algebra. Learn about indexed streams and their compiler implementation.
A Type System for Feature Engineering in Machine Learning
Explore a dependent type system for feature engineering, enhancing machine learning model inputs through advanced data operations and compiler techniques.
Functional Programming in PostgreSQL - Lambda Days 2023
Explore functional pipelines in PostgreSQL using TimescaleDB toolkit, leveraging custom types and operators for powerful data analytics directly in SQL.
ElectricSQL - Local-first SQL with Elixir
Explore local-first development with ElectricSQL, a platform for reactive, realtime, multi-user sync using Postgres and SQLite, powered by Elixir's replication technology.
How to Generate Test Data for Your Database Project
Generate realistic test data for database projects using Python libraries and techniques. Improve development and testing processes.
Building SpiceDB: A gRPC-First Database
Explore the journey of building SpiceDB, a specialized database using gRPC as its primary query interface, and learn about API modeling, client maintenance, and optimizations.
Forecasting Time Series with Arrow and WASM
Explore novel time-series processing pipeline using Apache Arrow, S3, Polars/DuckDB, and WASM for efficient forecasting and MLOps deployment.
SQL for Efficient Data Organization in Machine Learning
Explore JoinBoost, a Python library transforming tree training algorithms into SQL queries for efficient ML on normalized databases, offering improved performance and scalability.
Major Migrations Made Easy
Discover strategies for simplifying major software migrations, enhancing efficiency and reducing risks in large-scale development projects.
Is Contributing to Open Source Difficult? - Overcoming Barriers and Achieving Success
Discover strategies to overcome barriers and balance work with open-source contributions, drawing from real experiences in the Apache community.
Understanding Maintenance in Azure SQL
Explore Azure SQL maintenance: timing, impact, and control options. Gain insights into Microsoft's patching and update processes for optimal database management.

Unlocking Azure OpenAI: A 20-Minute Introduction
Explore Azure OpenAI's core principles, capabilities, and applications in just 20 minutes, including integration with Azure Data Factory and Azure SQL.

Relational or Non-Relational? Choosing the Best Database for the Task
Explore strengths and weaknesses of relational and non-relational databases. Learn best use cases and real-world examples to make informed decisions for your data storage needs.