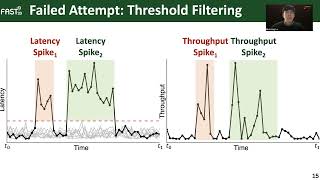
Perseus - A Fail-Slow Detection Framework for Cloud Storage Systems
Innovative framework for detecting and analyzing fail-slow failures in cloud storage systems, reducing tail latency and providing insights into root causes through large-scale dataset analysis.
Incident Analysis Before Chaos Engineering
Explore incident analysis in chaos engineering with real-world stories, learn its benefits, and discover how to implement it effectively for improved system resilience and reliability.
Getting Started with Chaos Engineering
Explore chaos engineering with industry experts as they discuss best practices, experiences, and key takeaways from their book. Learn how to optimize distributed systems and improve incident response.
Windows IR Made Easier and Faster - Find the Head of the Snake Using AutoRuns
Streamline Windows incident response with AutoRuns, focusing on efficient techniques to identify and neutralize threats quickly in large-scale environments.
We Are All on the Spectrum - What My 10-Year-Old Taught Me About Leading Teams
Explore insights on autism, team leadership, and workplace diversity through a parent's perspective, highlighting potential for excellence and strategies for inclusive team building.
Approaching Parity - Considerations for Adapting Enterprise Monitoring
Explore enterprise monitoring adaptation strategies, focusing on CSIRT implementation in AWS, automated playbooks, and effective incident response techniques.
AutoARTS - Taxonomy, Insights and Tools for Root Cause Labelling of Incidents in Microsoft Azure
Comprehensive study on incident root causes in Microsoft Azure, proposing a novel hierarchical taxonomy and automated labeling tool to improve postmortem analysis and prevent future incidents.
Planning for and Handling Failures - From Open Hardware and Aviation to Production at Google
Exploring failure management across hardware, aviation, and tech industries, offering insights to improve risk assessment and prevention strategies.
Facing the Music When Millions of Users Hit Delta.com After Release
Discover strategies for handling high-traffic Angular applications, including micro-frontend architecture, load balancing, and bug tracking, to ensure scalability and performance at enterprise level.
Using Machine Learning on K8s Logs to Find Root Cause Faster
Discover how to leverage machine learning on Kubernetes logs for faster root cause analysis and incident resolution in cloud-native environments.
The Hitchhiker's Guide to Kubernetes Vulnerabilities
Explore Kubernetes vulnerabilities, their patterns, and security trends. Gain insights into classification, root causes, and community efforts to enhance K8s security posture.
Delivering Better Results with Cisco Wireless - Network Deployment and Management Tools
Discover how to streamline wireless network deployment using Cisco's innovative tools, featuring proactive PCAP troubleshooting, AI-RRM for Meraki, and IoT platform management through Spaces Connect.
End-to-End Incident Analysis and Resolution with Catchpoint
Explore end-to-end incident management with Catchpoint Platform, from symptom detection through root cause analysis to implementing preventive measures for improved system reliability.
Annotating Log Data for Machine Learning
Explore an NLP-based log analysis system for automated error triage and fault categorization, streamlining root cause analysis in complex log data.
WatchTower Alert Insights and Machine Learning for Mainframe Systems
Discover how WatchTower leverages ML and centralized alerts to streamline mainframe IT operations, accelerate problem detection, and enable proactive system monitoring for faster incident resolution.
Modern Industrial Data Platform - Technical Deep Dive
Dive into SKT's innovative approach to modern industrial data platforms, exploring on-demand data mesh architecture and active metadata management for enhanced data pipeline efficiency.
Achieving 99.99% Uptime with Open Source Observability
Explore OpenTelemetry for achieving 99.99% uptime in distributed systems. Learn to collect, process, and export telemetry data for enhanced visibility and quick issue resolution.
The Art of Investigating Problems in Software
Odkryj sztukę debugowania i rozwiązywania problemów w oprogramowaniu, ucząc się technik opartych na rzeczywistych sytuacjach i wieloletnim doświadczeniu.
Incidents are a New Normal - Embracing Failure in Software Development
Learn to embrace and benefit from software incidents. Discover techniques for effective post-mortems, root cause analysis, and preventive actions. Improve engineering skills by focusing on system vulnerabilities.

Dodging Leadership Landmines - 9 Decision Pitfalls to Avoid
Discover 9 common decision-making pitfalls for leaders and strategies to avoid them. Learn to make confident, informed choices that drive success in your organization.
Preventing a Global Software Catastrophe - Disaster Recovery Strategies and Lessons Learned
Explore strategies to prevent global software outages, learn from recent examples, and discover tips for vendors and users to avoid catastrophes through disaster recovery and root cause analysis.