Medical Error - From Disclosure & Apology to RCA
Explore best practices for handling medical errors, including disclosure, apology, and root cause analysis. Learn about effects on staff, debriefing techniques, and the "second victim" concept.
Build High Performance MLOps With ML Monitoring and AI Explainability
Discover techniques for enhancing MLOps through ML monitoring and AI explainability. Learn to identify model failures, address operational issues, and streamline model deployment using advanced analytics.
Developer Observability - Automated Diagnostics - Part 1
Explore automated diagnostics in Dynatrace for efficient code execution, root cause analysis, and problem detection in distributed environments. Learn to leverage observability data effectively.
Jenkins Pipeline Analytics with OpenTelemetry - Dynatrace Tips and Tricks
Optimize Jenkins pipelines and infrastructure using OpenTelemetry for analytics. Identify root causes of failing or problematic jobs, stages, and steps to enhance engineering productivity.
Ownership-Driven Observability Use Cases with Dynatrace
Explore ownership-driven observability with Dynatrace. Learn to assign owners, manage team metadata, and leverage data for improved automation, reducing MTTR and enhancing collaboration.
Best Practices for Auto Remediation with Ansible and Dynatrace
Discover best practices for scaling incident response using automated problem detection and remediation with Ansible and Dynatrace. Learn to reduce MTTR by 99% and effectively manage growing systems.
Infrastructure and Operations App - Dynatrace App Spotlight Demo
Explore Dynatrace's Infrastructure and Operations app, providing ITOps and SRE teams with comprehensive environment monitoring, problem detection, and root cause analysis capabilities.
Build High Performance MLOps With ML Monitoring and AI Explainability
Discover techniques for enhancing MLOps through ML monitoring and AI explainability. Learn to identify model failures, address operational issues, and streamline model deployment using advanced analytics.
ML Observability: A Critical Piece in the ML Stack
Explore ML Observability's role in addressing model failures, monitoring performance, and improving models. Learn industry best practices for enhancing your ML stack's reliability and efficiency.
Network Incidents - What to Know Before the Chaos Strikes
Gain insights into network incident management, from preparation to resolution. Learn strategies for handling crises, avoiding pitfalls, and implementing post-incident reviews to enhance system resilience.
ABI Encoding and DeFi Hack Root Cause Analysis
Dive into ABI Encoding fundamentals and learn how to analyze DeFi hack root causes through transaction data, return values, and event examination in Ethereum smart contracts.
How to Discover and Locate Kubernetes Cluster Problems Before Users - Alibaba's Approach
阿里巴巴通过自研KubeProbe工具实现大规模K8s集群问题的快速发现和定位,包括链路探测、定向巡检、系统增强等功能,提高集群稳定性和故障处理效率。
Trace-Profiling: A New Way to Track Application Behavior
利用eBPF技术结合追踪和剖析,在线程级别全面分析应用行为,包括CPU和非CPU事件,快速定位特定URL的性能问题,提高根因分析和问题解决效率。
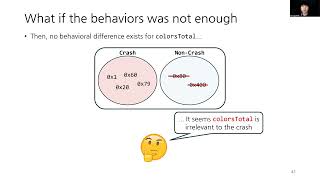
A Practical Root Cause Analysis System with Under-Constrained State Mutation - 2024
Explore an innovative approach to root cause analysis using under-constrained state mutation, enhancing system reliability and problem-solving efficiency.
كيف تكتشف الأسباب الحقيقية للألم
اكتشاف جذور المشاكل وإيجاد حلول جذرية بدلاً من مسكنات مؤقتة، من خلال تجارب شخصية ورؤى في مجال الابتكار والتفكير التصميمي.
5 Considerations for ICS Incident Response
Explore key considerations for effective ICS incident response, including preparation, decision-making, shutdown criteria, root cause analysis, and engaging IR teams for safe and efficient recovery.
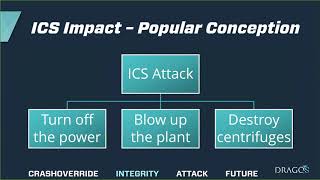
Reassessing CRASHOVERRIDE: Advanced ICS Cyber Attacks on Electric Utilities
Reexamination of CRASHOVERRIDE cyberattack, revealing its attempt at a more sophisticated assault on electric utility operations through manipulation of protective relays and system integrity.
The Cool Factor - Security's Secret Weapon
Explore hacking culture, security's impact on society, and innovative approaches to building a strong security culture program. Learn from industry insights and practical examples.
Hiding in Plain Sight - The Untold Story of Hidden Vulnerabilities
Uncover limitations of vulnerability scanners and SCA tools through groundbreaking research. Learn about hidden vulnerabilities, scanner blindspots, and the need for holistic software security approaches.
Clinical Troubleshooting: Diagnose Production Issues - Conf42 SRE 2024
Learn systematic approaches to diagnose production issues efficiently, enhancing your troubleshooting skills for improved site reliability engineering.
Reliability, Everyone’s Responsibility - Intro to Site Reliability Engineering Practices
Explore the fundamentals of Site Reliability Engineering, including SLAs, SLOs, and SLIs. Learn to establish a culture of reliability and navigate complex systems for robust platform maintenance.