Optimizing RAG Systems for Business Applications
Master the implementation of RAG systems in enterprise settings, from dynamic chunking to custom embedding models, while learning optimization techniques for enhanced AI response accuracy and relevance.
Data Preparation for RAG Applications Using Qdrant and FastEmbed
Master data preparation techniques for RAG applications using Qdrant and FastEmbed, covering chunking methods, embedding generation, indexing strategies, and efficient data loading processes.
RAG: Nvidia NIM Integration with Langchain for HTML Web Page Parsing
Descubre cómo implementar aplicaciones RAG utilizando Langchain y Nvidia NIM para extraer información de páginas HTML, integrando el modelo Mistral 8 7b Instruct para procesamiento avanzado.
RAG - Parsing HTML Content with BeautifulSoup and Nvidia NIM Integration in LangChain
Dive into building RAG systems by integrating Nvidia NIM with LangChain, using BeautifulSoup for HTML parsing and Mistral 8 7b Instruct as the foundation model.

Nixiesearch - Building a Serverless Search Engine with Lucene on S3
Explore how Nixiesearch leverages Lucene over S3 to create a simplified, serverless search engine with built-in AI capabilities, including RAG and text+image embeddings for modern search solutions.

Relevance Proof in Yelp Search - LLM-Powered Annotations
Discover how Yelp enhances search results using LLM-powered annotations, focusing on review highlights and business information to improve user experience and search relevance at scale.
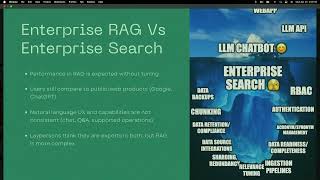
Why RAG Projects Fail and How to Make Yours Succeed
Explore common pitfalls in RAG projects and learn strategies to ensure success. Gain insights on project organization, execution, and overcoming challenges in implementing chatbots and QA systems.
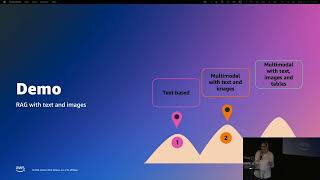
Expanding RAG with Multimodal Capabilities - Haystack US 2024
Explore multimodal RAG workflows for enhanced retrieval and generation, incorporating text, tables, and images. Live demo showcases PDF processing, vector database usage, and LLM-enriched responses.
Measuring and Improving Retrieval in RAG Systems - Haystack US 2024
Learn techniques to measure and enhance retrieval quality in RAG systems, exploring alternatives to human expert judgments and methods for tuning retrieval to improve generated responses.
Chat With Your Data - A Practical Guide to Production RAG Apps
Learn to build production-ready RAG applications with insights from Moody's rapid development. Gain strategies for embedding, relevance measurement, cost management, and team organization for impactful AI-driven data interaction.
Personalizing Search Using Multimodal Latent Behavioral Embeddings
Explore personalized search using multimodal latent behavioral embeddings. Learn to integrate user behavior into modern search retrieval pipelines for RAG and end-user search, enhancing relevance and user experience.
10x the Retrieval Quality of Vector Search - Enhancing Semantic Search and RAG Systems
Enhance vector search retrieval quality by encoding diverse information into single vectors, simplifying deployment and reducing post-processing needs.
Building RAG Systems with Mixed Numeric and Text Data - Workshop
Learn to build high-performing RAG systems by combining numeric and text data embeddings. Explore efficient retrieval techniques for LLMs and improve chatbot performance using an HR policy example.

3 Ways to Make a Custom AI Assistant: RAG, Tools, and Fine-tuning
Explore three methods to create custom AI assistants using OpenAI: GPTs, Assistants API, and Fine-tuning API. Learn to build a YouTube comment responder through practical demonstrations.
Optimizing RAG Implementations for Specialized Enterprise Tasks
Optimize RAG implementations for enterprise tasks. Learn to fine-tune components, apply AI data development techniques, and accelerate production delivery for increased accuracy and precision.
How to Optimize RAG Pipelines for Domain- and Enterprise-Specific Tasks
Master RAG pipeline optimization for accurate, reliable LLM applications. Learn semantic document chunking, embedding techniques, and fine-tuning strategies. Leverage Snorkel Flow to accelerate development and overcome retrieval errors.
Is RAG All You Need? A Look at the Limits of Retrieval Augmented Generation
Explore RAG's strengths and limitations in LLMs, examining its effectiveness for different applications and discussing alternative approaches for improved output quality.
Generative AI Use Cases and Design Patterns with Databases
Explore real-world generative AI applications using Google Cloud Databases, Vertex AI, and LangChain. Learn RAG techniques for enterprise-grade solutions.

Retrieval-Augmented Generation (RAG) - Explained
Explore RAG (Retrieval-Augmented Generation) to mitigate AI hallucinations. Learn key concepts, implementation details, and advanced techniques through multiple passes and quizzes.
Spring AI: Integrating AI into Enterprise Applications with Java
Explore Spring AI's seamless integration of AI into enterprise Java applications. Learn key concepts, create effective prompts, and implement features like embeddings, RAG, and semantic search.
Understanding the LLM Economics: The $360k Question - Lecture
Explore LLM economics, comparing costs of RAG vs fine-tuning and open-source vs commercial models. Gain insights on optimizing expenses for production-ready LLM applications.