Exploring Distributed Caching for Faster GPU Training with NVMe, GDS, and RDMA
Discover how to optimize GPU training performance through distributed caching techniques, leveraging NVMe storage, GDS, and RDMA networks for enhanced data access and reduced GPU wait times.
ZXDH DPU Adapter and Its Application in Hardware Acceleration and Networking
Discover ZTE's ASIC-based enhanced data processor with programmable packet processing, hardware offloading, and extensive driver interfaces for virtualization, AI computing, and security applications.
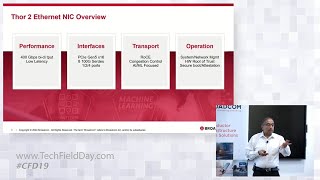
High-Performance Ethernet NIC for AI/ML - Thor 2 Architecture and Features
Explore high-performance networking solutions for AI/ML clusters, focusing on Broadcom's Thor 2 Ethernet NIC features, including RoCE support, congestion control, and end-to-end fabric management for optimal cluster performance.
Quantum Myriad - All-Flash Scale-Out Storage Architecture
Discover how Quantum Myriad's innovative all-flash scale-out storage system leverages microservices, Kubernetes, and NVMe optimization to deliver high-performance storage solutions for video and HPC workloads.
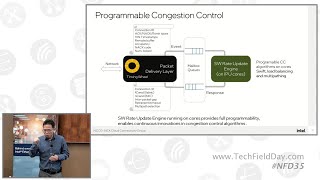
Reliable Transport of Lossy Fabrics with Falcon - A Low Latency Hardware Solution
Discover how Falcon enables reliable RDMA messaging and NVMe commands across cloud networks, optimizing performance for AI/ML, HPC, and storage workloads with low-latency transport.
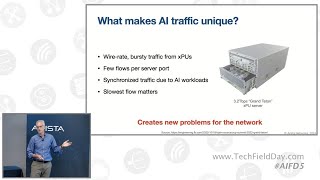
AI Network Challenges and Solutions for High-Performance Computing
Explore advanced networking solutions for AI workloads, focusing on load balancing, congestion control, and infrastructure optimization for high-bandwidth machine learning operations.
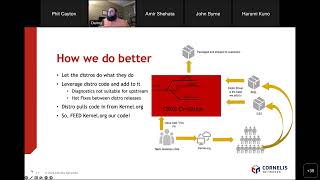
Supporting an Upstream First Kernel Driver for HPC Fabrics
Explore the evolution and improvements of the HPC fabric driver hfi1, from its staging phase to mainline kernel integration, focusing on upstream development and open-source delivery methods.
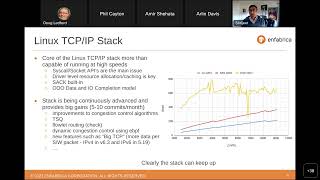
RDMA and Linux TCP - Zero-Copy Kernel Bypass for High-Performance Networking
Dive into high-performance networking with RDMA interfaces and Linux TCP stack optimization, exploring zero-copy techniques and kernel bypass for achieving 800Gbps throughput.
iCheck - Leveraging RDMA and Malleability for Application-Level Checkpointing in HPC Systems
Discover how RDMA and malleable multilevel checkpointing can enhance HPC system reliability through iCheck framework, offering improved performance and efficient data transfer mechanisms for supercomputing applications.
Accelerating Serverless AI Large Model Inference with Functionalized Scheduling and RDMA
Optimizing serverless AI inference with functionalized scheduling and RDMA for faster response times and efficient KV cache migration, addressing challenges in large-scale model deployment.
Solving I/O Scaling Challenges in Accelerated Compute with Networking Silicon
Discover how Enfabrica's Accelerated Compute Fabric revolutionizes I/O scaling in compute clusters through innovative networking silicon integration, optimizing data movement and enhancing GPU communication efficiency.
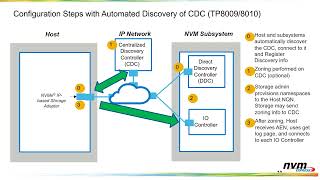
Discovery Automation and NVMe Fabric Zoning for IP-Based Storage Networks
Discover how to enhance NVMe over IP-based fabrics systems through automated discovery processes, centralized controllers, and efficient zoning implementations for improved data center management.
Peer Provider Composability and API Design in libfabric
Dive into advanced network communication optimization using libfabric's peer provider architecture for enhanced performance across multiple hardware and transport configurations.
Boosting Training and Inference Performance via Topology-Aware Scheduling of Heterogeneous Resources
Discover how ByteDance optimizes LLM workload performance through enhanced topology-aware scheduling, focusing on die-level affinity, RDMA optimization, and GPU-RDMA integration in Kubernetes environments.

The Linux NFS Server in 2024 - New Features and Development Roadmap
Discover the latest innovations in Linux in-kernel NFS server, including security enhancements, pNFS block layout support, RDMA capabilities, and network partition handling improvements.

High-Performance Block Volumes in Virtual Cloud Environment
Explore high-performance block volume solutions for virtual machines, comparing vhost, NVMe protocols, and DPU implementations to achieve optimal throughput and IOPS with minimal resource usage.