Web Scraping Puppy Data with Microsoft Fabric - 1st Leg
Explore CSS Selectors for web scraping in Power Query, m code, and PySpark Notebooks within Microsoft Fabric's Azure cloud environment.
Creating and Submitting PySpark Jobs to Spark Clusters
Create and submit PySpark jobs to Spark clusters in an end-to-end data engineering project using Airflow, Docker, and multiple programming languages. Learn job creation, cluster submission, and result visualization.
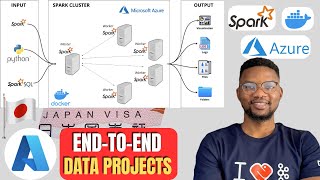
End-to-End Data Engineering on Azure Spark Cluster: Japan Visa Analysis
Set up Spark master-worker architecture in Docker on Azure, process and visualize Japan visa data using PySpark and Plotly. Clean, transform, and gain insights into visa trends through interactive data analysis.
The Intelligent Future of Data Warehouses and Delta Lake - Structured Streaming with PySPARK
Explore the evolution of data warehousing from traditional ETL to modern Lakehouse architecture, focusing on Delta Lake, Structured Streaming, and PySpark implementation with practical code examples.
Spark at Scale: Engineering Strategies for Data Science Workflows
Optimize PySpark applications and slash runtimes using engineering strategies for data science workflows, illustrated through a case study on in-store availability reporting.

Introduction to PySpark
Learn the fundamentals of PySpark for efficient big data processing and analytics using Python in Apache Spark's distributed computing environment.
New Features of Apache Spark 3.5 - In-Depth Analysis
Explore Apache Spark 3.5's advancements: Spark Connect, DeepSpeed integration, performance optimizations, new PySpark and SQL features for enhanced big data processing and AI capabilities.
What's Next for the Upcoming Apache Spark 4.0
Explore key enhancements in Apache Spark 4.0: Spark Connect, Structured Logging, PySpark updates, expanded SQL capabilities, improved connectivity, and real-time data processing advancements for optimized analytics.
Transaction Log as the Heart of Delta Lake - Understanding Structure and Operations
Dive into the mechanics of Delta Lake's transaction log through hands-on PySpark exercises, exploring its structure, operations, and advantages over traditional data lakes.
Apache Airflow with Spark for Data Engineers - Full Course
Build end-to-end data engineering projects using Apache Airflow, Docker, Spark, and multiple programming languages. Learn to create and submit jobs to Spark clusters for processing and view real-time results.