Azure Databricks Using Python With PySpark
Explore Python and PySpark in Azure Databricks: from basic concepts to advanced techniques, including DataFrame API, ML scaling, and data visualization.
Rapid PySpark Custom Processing on Time Series Big Data in Databricks
Efficient PySpark processing for time series big data, enabling rapid custom calculations on rolling windows with constant time complexity, demonstrated using Sleep Number Smartbed sensor data.
Best Practices for Unit Testing PySpark
Learn effective techniques for unit testing PySpark code, including local and CI testing, code structuring for testability, and integration testing with clusters for enhanced reliability and easier refactoring.
Exploring UDTFs and Polymorphism in PySpark
Learn to create and enhance User-Defined Table Functions in PySpark, including polymorphic UDTFs for flexible data processing. Gain practical insights through examples and expert guidance.
Spark NLP - State-of-the-Art Natural Language Processing at Scale
Discover scalable NLP techniques using Apache Spark, covering core algorithms, BERT embeddings, and multi-lingual challenges. Learn to build efficient pipelines for various NLP tasks through practical demonstrations.
Deep Learning for Price Action Prediction Using Databricks and AWS
Explore deep learning techniques to enhance price action prediction using Databricks and AWS. Learn to optimize technical indicators and train models with Amazon SageMaker for improved financial forecasting.
MLOps MLFlow: MLflow Projects with PySpark Docker Environments
Explore MLflow Projects with PySpark in Docker, utilizing Databricks for artifact storage and tracking in MLOps workflows.
Charlas - Marco Carranza: Estrategias para trabajar con datos a medida que estos crecen
Estrategias para procesar datos crecientes con recursos limitados, desde una sola máquina hasta clusters, utilizando Pandas, Pyspark, Vaex y Modin. Enfoque práctico para investigadores y startups.
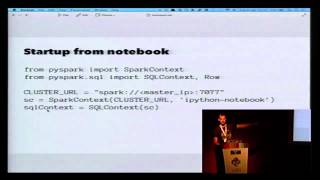
PySpark and Warcraft Data
Explore PySpark's capabilities for analyzing World of Warcraft auction data, comparing performance with other tools and demonstrating its application in processing large datasets efficiently.
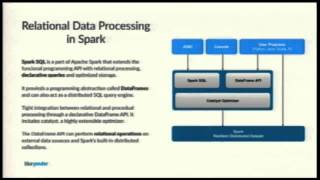
PySpark - Data Processing in Python on Top of Apache Spark
Learn PySpark for large-scale data processing with Python on Apache Spark. Covers RDDs, DataFrame API, transformations, actions, and data sources. Ideal for those seeking efficient big data analysis techniques.
Mastering a Data Pipeline with Python - 6 Years of Learned Lessons from Mistakes
Explore key insights and best practices for building robust data pipelines with Python, covering data acquisition, transformation, storage, and workflow management based on 6 years of experience.
Developing a Match-Making Algorithm Between Customers and Go-Jek Products
Explore how GoJek developed a personalized recommendation system using PySpark to match customers with relevant products and vouchers, improving conversion rates.
Building Reproducible Distributed Applications at Scale
Explore challenges and solutions for packaging Python code in distributed computing environments, focusing on shipping methods, pickling, self-contained executables, and real-world examples with PySpark and S3 storage.
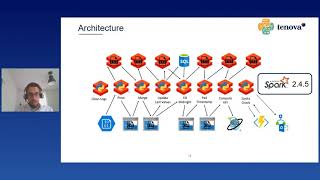
From Telemetry Data to CSVs with Python, Spark and Azure Databricks
Transforming industrial telemetry data into CSV format using Python, Spark, and Azure Databricks for analytics and AI model retraining in the context of Industry 4.0.
Data Warehouses Meet Data Lakes
Explore modern data architecture using PySpark, Hudi, Delta.io, and Iceberg to address datalake challenges, supporting real-time processing and enterprise-wide digital transformation.
Processing and Storing Time Series Instrument Data with Pandas and PySpark
Master data processing techniques for handling large-scale time series instrument data using pandas and PySpark, focusing on efficient solutions for scientific and laboratory information management challenges.
Smart Approach in Development and Deployment Process for ML Models
Discover efficient strategies for ML model development, focusing on smart data mart creation, preprocessing techniques, and streamlined deployment processes using Python/PySpark.
Web Scraping Puppy Data with Microsoft Fabric - 1st Leg
Explore CSS Selectors for web scraping in Power Query, m code, and PySpark Notebooks within Microsoft Fabric's Azure cloud environment.
Data Linkage Options: MDM vs Splink in PySpark
Explore data linkage solutions, comparing MDM and Splink (PySpark) for effective data integration and management.
Web Scraping Puppy Data with Microsoft Fabric - 2nd Leg
Learn web scraping techniques using CSS Selectors in Power Query, m code, and PySpark within Microsoft Fabric to extract puppy data from websites.
Web Scraping Puppy Data with Microsoft Fabric - 2nd Leg
Learn web scraping techniques using CSS Selectors in Power Query, m code, and PySpark within Microsoft Fabric to extract puppy data from websites.