Slack and Micronaut - Perfect Combo for Your Side Project
Explore building Slack applications with Micronaut, leveraging the Bolt SDK for seamless integration and mobile-friendly functionality.
How to Survive a Live Coding Session
Master live coding presentations with expert tips, tricks, and real-life stories. Enhance your skills to deliver engaging, well-prepared demos that showcase concrete tool and library usage.
How Much AI is in AI Engineering
Explore the role of AI in engineering, examining its applications and limitations in modern software development practices.
Building a Real-Time Analytics Database
Odkryj tajniki tworzenia bazy danych do analityki w czasie rzeczywistym. Poznaj kluczowe koncepcje i najlepsze praktyki w tej dziedzinie.
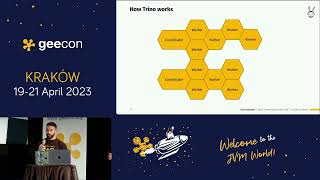
Cloud Agnostic Data Platform with DBT, Trino, Iceberg and MinIO
Explore a hands-on, cloud-agnostic data pipeline using TrinoDB, DBT, MinIO, and Apache Iceberg for scalable and lightweight analytics, suitable for both cloud and on-premise solutions.
The Science of Stories: Measuring and Exploring the Ecology of Human Stories with Lexical Instruments
Explore the use of lexical meters to measure social and cultural phenomena through social media and text analysis, uncovering insights into human behavior and storytelling.
Google's Cloud Partner Engineer Chief on AI Ethics - Challenges and Benefits of Foundation Models for Enterprises
Explore challenges and benefits of Foundation Models for enterprises, focusing on inadequacies in current ML pipelines for FM development workflows.
How to Create Data-Cleaning Auto-Pipelines With Python
Develop automated data cleaning pipelines using Scikit-Learn to streamline data processing, reduce time spent on preprocessing, and enhance reproducibility in your data science projects.
Unicorn's Baby Steps: What Should You Know as a First-Time Startup CTO
Navigate the challenges of being a first-time startup CTO with insights on prioritization, decision-making, and addressing key concerns in the early stages of a startup.
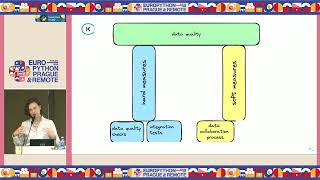
Don't Fix Bad Data, Do This Instead - Pragmatic Strategies for Data Quality
Explore pragmatic strategies for bridging the gap between data expectations and reality. Learn about integration tests, prioritization, and balancing technical and cultural measures in data quality management.
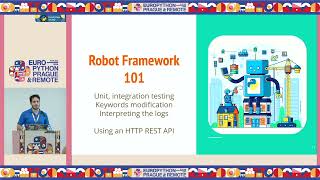
RPA, TDD, and Embedded - A World Glued Together with Python
Explore RPA, TDD, and embedded systems integration using Robot Framework and Python. Learn to maximize testing potential in microcontroller environments through practical examples.
Caching for Jupyter Notebooks
Aprenda técnicas de caching para acelerar o desenvolvimento em Jupyter Notebooks, melhorando o fluxo de trabalho e reduzindo o tempo de espera em células dispendiosas.
Creating Your Own Extensions for JupyterLab
Learn to create custom JupyterLab extensions, enhancing functionality and integrating complex tasks. Explore the extension infrastructure and build a step-by-step app with styling and parameter options.
DBT and Python - How to Write Reusable and Testable Pipelines
Develop reusable and testable data pipelines using DBT and Python. Learn best practices for version control, DAGs, and unit testing in SQL and Python-based models.

chDB - The Blazing Fast SQL Engine for Data Science
Explore chDB, a high-performance SQL engine for Python data ecosystem. Leverage its extensive data source support, ANSI SQL compliance, and seamless integration with popular libraries for efficient data analysis.
One Analysis a Day Keeps Anomalies Away - Detecting and Analyzing Data Anomalies
Explore Python techniques for data observability, anomaly detection, and root cause analysis in multivariate time series. Learn to distinguish anomalies from data drift and turn insights into opportunities.
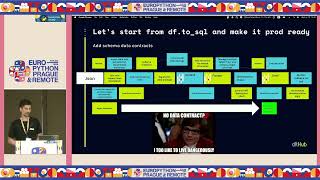
From Pandas to Production: ELT with dlt
Explore data load tool (dlt) to streamline data science workflows, overcome roadblocks, and transition smoothly from exploration to production. Learn best practices for data handling and managing failures with real-life examples.
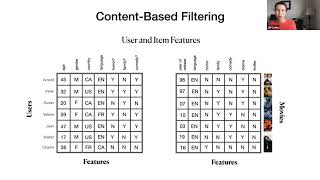
Building a MovieLens Recommender System
Explore recommendation systems and build your own using collaborative and content-based filtering techniques in Python with MovieLens dataset.
Machine Learning with PyCaret - Workshop
Explore rapid prototyping and ML pipeline development using PyCaret, an open-source, low-code machine learning library for Python.
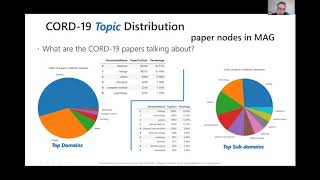
Knowledge Graph Recommendation Systems for COVID-19
Explore knowledge graph recommendation systems for COVID-19, leveraging Python skills to enhance understanding of pandemic-related data and insights.
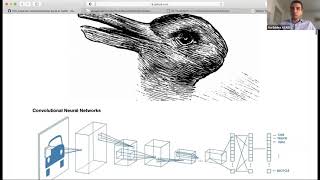
Computer Vision in Practice - Building an End-to-End Pipeline for Object Detection and Segmentation
Build an end-to-end image segmentation pipeline using deep learning. Learn dataset customization, model training, validation, testing, and mobile deployment techniques.