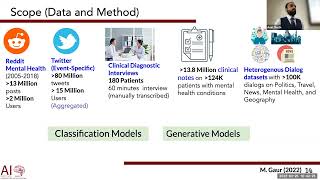
Knowledge-infused Learning - Dissertation Defense
Explore knowledge-infused learning techniques and their applications in AI through Manas Gaur's dissertation defense presentation.
scverse: An Introduction to Single-Cell Data Analysis in Python
Explore Python's ecosystem for single-cell data analysis with scverse, a community-driven initiative coordinating omics data work.

How to Build Data Pipelines for ML Projects with Python Code
Learn to build data pipelines for machine learning projects using Python. Explore ETL vs ELT, extraction, transformation, loading, and orchestration. Includes practical example of processing YouTube video transcripts.

Detecting Power Laws in Real-world Data with Python Code
Learn to detect power laws in real-world data using Python, covering log-log and maximum likelihood approaches with practical examples using artificial and social media datasets.

How to Manage Data Science Projects - A 5-Step Framework
Discover a 5-step framework for managing data science projects, including a case study on a YouTube video search tool. Learn the project manager's crucial role in implementation.

Introduction to Decision Trees - Gini Impurity and Python Code
Learn decision tree fundamentals, including Gini impurity and Python implementation, through a beginner-friendly introduction with concrete examples and code for sepsis survival prediction.

Causal Effects via Propensity Scores - Introduction and Python Implementation
Explore propensity scores for causal effects in observational data. Learn three methods: matching, stratification, and inverse probability weighting. Includes Python example and cautionary notes.

Automating Data Pipelines with Python and GitHub Actions - Code Walkthrough
Automate data pipelines using Python and GitHub Actions. Learn to create ETL scripts, set up repositories, configure workflows, and implement ML applications for efficient data processing.

Building Machine Learning Solutions with Python - Code Walkthrough
Develop a semantic search tool for YouTube videos using Python, focusing on experimentation, evaluation, and UI building in machine learning solutions.
How to Boost a Cloud-Native Lakehouse with 2X Performance
Boost cloud-native lakehouse performance using Kubernetes, Spark, and other open-source technologies. Learn to overcome challenges in resource management, task scheduling, and storage interconnection for enhanced analytics.
OpenEuler and Bigtop with Ambari - Empowering Data Lake Solutions
Explore free open-source data lake solutions using Bigtop with Ambari. Learn about the latest Bigtop release, integration with OpenEuler, and how this platform streamlines data management and analytics.
Practice of Building Real-Time Data Lake Based on Flink
Build a real-time data lake using Flink and Iceberg to address timeliness, diversity, consistency, and accuracy challenges in modern data architectures.
Apache Arrow Optimization on Arm
Discover techniques for profiling and optimizing Apache Arrow on Arm platforms, including Top-down methodology, Arm SPE, and NEON. Learn to identify and resolve performance bottlenecks in complex workloads.
Introducing Apache Pinot: Real-time Analytics for Large-Scale Data
Explore Apache Pinot's real-time analytics capabilities, architecture, and data model. Learn about its query language, indexing, and use cases in high-performance applications.
How to Boost Your Engineering Creativity and Productivity
Discover techniques to enhance engineering creativity and productivity, improving problem-solving skills and efficiency in software development.
Jupyter Notebook vs Classical IDEs - Do You Have to Choose?
Explore the strengths and limitations of Jupyter Notebooks and traditional IDEs, understanding when to use each for optimal coding efficiency and productivity.
RisingWave: Reinventing Stream Processing in the Cloud Era
Explore cloud-era stream processing innovations, focusing on state management, failure recovery, and elastic scaling. Learn about tiered storage and challenging problems in the field.
Spark Cloud Native Practice - Powered by Apache Kyuubi and Celeborn
Explore building enterprise-level Spark on Kubernetes cloud-native offline computing platforms using Apache Kyuubi and Celeborn. Learn architecture design, lessons, and efficiency enhancements.
State of Scala API in Apache Flink
Explore Scala API in Apache Flink 1.15+, including Scala 3 support, SBT project setup, and community wrappers. Learn to leverage Scala for efficient Flink job development and packaging.
Flink K8S Operator Autoscaling - Implementation and Best Practices
Explore Flink K8S Operator's autoscaling capabilities, origins, and future developments. Learn about resource optimization and non-stop updates in Apache Flink's stream processing ecosystem.
Real-Time Data Integration Practice Based on Flink CDC at Alibaba Cloud
Explore real-time data integration using Flink CDC, covering core design, key implementations, and Alibaba Cloud's solutions for data lake and warehouse integration scenarios.