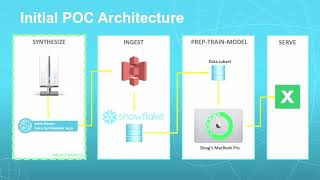
Securely Enabling Data Science in the Cloud
Explore secure cloud-based data science strategies, focusing on enabling analytics while maintaining data privacy and compliance across various cloud providers and data types.
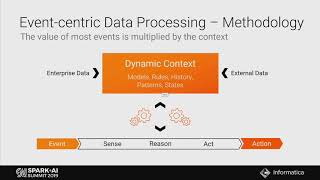
AI-Powered Streaming Analytics for Real-Time Customer Experience
Explore AI-powered streaming analytics for real-time customer engagement. Learn to capture, process, and respond to data from various sources using Spark Structured Streaming for improved customer experiences.
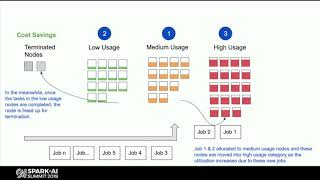
Downscaling Apache Spark Clusters - Challenges and Solutions
Explore techniques to improve downscaling in Spark-on-YARN clusters, addressing container fragmentation and shuffle data challenges for efficient resource management and faster autoscaling.
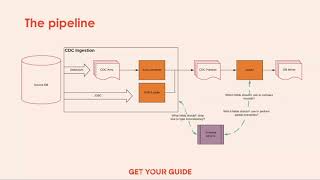
Modern ETL Pipelines with Change Data Capture - Building Resilient Data Streams
Discover how GetYourGuide built a resilient ETL pipeline using Debezium, Kafka, Spark, and Airflow. Learn to handle schema changes automatically, stream data from SQL databases, and refresh data lakes multiple times daily for fresher insights.
Best Practices for Building and Deploying Data Pipelines in Apache Spark
Learn best practices for building and deploying efficient, reproducible data pipelines in Apache Spark. Discover a toolkit that simplifies pipeline creation for non-engineers and explore deployment strategies.
Revolutionizing Legal Industry with Spark, NLP and Azure Databricks - Clifford Chance Case Study
Explore how a top law firm revolutionizes operations using advanced analytics, Spark, NLP, and Azure Databricks to handle millions of legal documents and enhance client relationships.
How to Handle High Cardinality Predictors for Data on Museums in the UK
Explore effect and likelihood encodings for high cardinality predictors in tidymodels, using UK museum data to demonstrate practical applications.
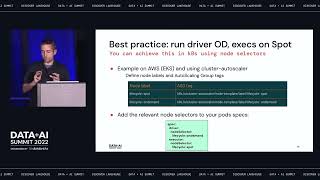
How to Make Apache Spark on Kubernetes Run Reliably on Spot Instances
Learn to run Apache Spark on Kubernetes using spot instances for cost savings. Discover best practices, code examples, and techniques to handle spot interruptions while maintaining reliability and performance.
Low-Code Machine Learning on Databricks with AutoML
Discover how to build, train, and deploy ML models using Databricks AutoML and low-code tools, empowering users of all expertise levels to create predictive analytics solutions.
Improving Apache Spark Application Processing Time - Configuration and Optimization Techniques
Optimize Spark streaming app performance through configurations, code improvements, and custom data source implementation for processing 700 MB/s of compressed data with strict KPIs.
Orchestration Made Easy with Databricks Workflows
Discover Databricks Workflows: a managed orchestration service for streamlined data pipelines. Learn to create, run, and monitor reliable workflows, implement recovery actions, and explore new features for efficient data management.
Administrator Best Practices for Scaling and Securing Databricks Deployments
Optimize Databricks administration for enterprise-scale deployments. Learn best practices, new capabilities, and customer insights for efficient onboarding, security, and workspace management.
Apache Spark on Kubernetes - Lessons Learned from Launching Millions of Spark Executors
Lessons learned from running massive Spark workloads on Kubernetes at Apple, covering orchestration, resource management, monitoring, and optimization for scalability and performance.
Securing Databricks on AWS Using PrivateLink - Deployment and Automation
Learn to secure Databricks on AWS using PrivateLink, covering architecture, setup, and automation. Gain insights on minimizing public internet data transfers for enhanced security and cost-efficiency.
PySpark in Apache Spark 3.3 and Beyond
Explore PySpark's evolution in Apache Spark 3.3, including improved Pandas API, enhanced productivity features, and future developments. Learn about new functionalities, usability improvements, and performance enhancements.
Data Warehousing on the Lakehouse - Unifying Data, AI, and Analytics
Unify data, AI, and analytics with the lakehouse architecture. Learn success stories, use cases, and best practices for ingesting, storing, and governing data at scale for SQL and BI workloads using Databricks SQL.

The New ACM Digital Library - User and Administrator Training
Explore ACM's new Digital Library interface, featuring enhanced search capabilities, user profiles, and administrative tools for efficient access to computing research and publications.
Crunching the Numbers- Navigating Mobile Game Metrics - Unite Now 2020
Explore key mobile game metrics, reporting, and optimization strategies for indie developers. Learn to leverage core metrics for game success and user retention.
The Azure Machine Learning Service - Introduction
Explore Azure ML Service's features for scaling, automating, and deploying machine learning pipelines. Learn how it enhances the data science process and addresses key challenges.

Jump Start on Data Science with an Azure Data Science VM
Learn to quickly set up and use an Azure Data Science Virtual Machine, equipped with essential tools for data science and machine learning projects.
Jupyter Notebooks - An Introduction
Learn to create interactive documents combining code, visualizations, and text using Jupyter Notebooks. Explore features, languages, and applications across various industries.