Dumb-Proofing Data Pipelines: Techniques for Configurable and Maintainable ETL - Databricks
Techniques to create configurable, maintainable data pipelines. Learn to externalize configurations, validate inputs, and leverage Scala features for robust, easily deployable ETL processes.
Learn to Use Databricks for Data Science
Discover how Databricks simplifies data science with a unified platform for analytics workloads, from data preparation to predictive analytics, enhancing collaboration and productivity at scale.
Fully Utilizing Spark for Data Validation with Fugue and Pandera
Explore lightweight data validation for Spark using Fugue and Pandera, enabling partition-specific rules and efficient big data processing without compromising on functionality.
Deep Dive into New Features of Apache Spark 3.1
Explore Apache Spark 3.1's new features: ANSI SQL compliance, streaming enhancements, Python improvements, and performance optimizations for faster, easier, and smarter data processing.
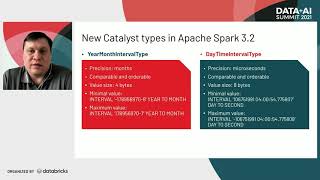
Comprehensive View on Intervals in Apache Spark 3.2
Explore Apache Spark 3.2's interval enhancements, including ANSI SQL conformance, new interval types, and improved APIs. Learn to construct, use, and manage intervals effectively in Spark SQL and PySpark.
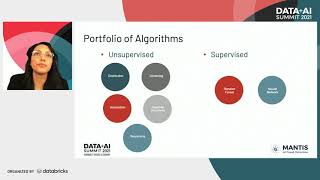
Wizard Driven AI Anomaly Detection with Databricks in Azure
Explore wizard-driven AI anomaly detection for fraud prevention using Databricks. Learn unsupervised and supervised methods, aggregation frameworks, and human-in-the-loop feedback to improve models over time.
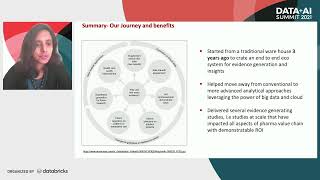
Real-World Evidence and Patient Analytics Using Databricks - A Use Case
Explore real-world health data analytics using Databricks, including insights generation, data security, and advanced use cases. Learn about big data ingestion and cloud-based platform industrialization for life sciences.
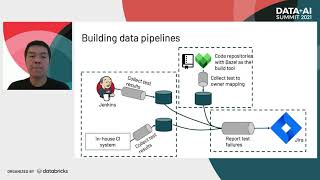
Managing Millions of Tests Using Databricks - Automated Monitoring and Reporting System
Explore automated test monitoring and reporting for Databricks Runtime using Delta, analyzing results from various sources to track quality and efficiently report failures to owners.
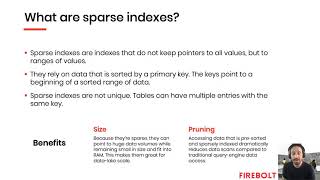
Low-Latency & High-Concurrency Analytics Over Data Lakes
Explore advanced techniques for achieving low-latency, high-concurrency analytics on large-scale data lakes. Learn about optimized storage, indexing, and practical approaches to handle massive data volumes efficiently.
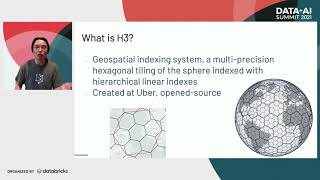
Large Scale Geospatial Indexing and Analysis on Apache Spark
Explore large-scale geospatial indexing and analysis using Apache Spark, covering challenges, frameworks, data structures, and practical applications in cloud-first architecture with Databricks.
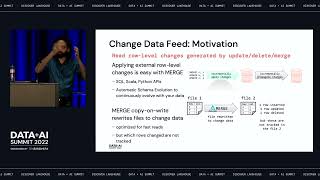
Delta Lake 2.0 Overview - New Features and Community Collaborations
Overview of Delta Lake 2.0 features, integrations, and community collaboration. Highlights include data skipping, Change Data Feed, column mapping, multi-cluster S3 writes, and support for various languages and platforms.
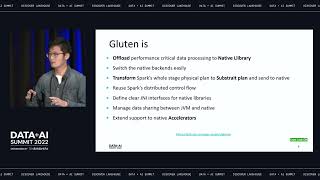
Gazelle-JNI: Offloading Spark SQL to Native Engines for Execution Acceleration
Explore Gazelle-Jni, a middle layer integrating native SQL engines with Spark SQL for accelerated execution through Substrait-transformed physical plan offloading.
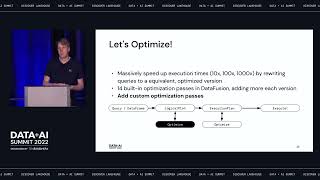
DataFusion and Apache Arrow: Supercharging Data Analytics with a Rust-Based Query Engine
Explore Rust, Apache Arrow, and DataFusion to accelerate modern data stacks. Learn implementation timelines, optimization techniques, and key features for efficient data analysis and querying.
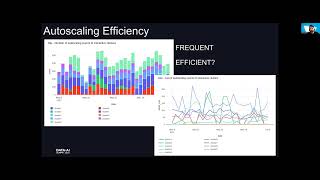
Databricks and Enterprise Observability with Overwatch - Understanding Cost, Utilization, and Workloads
Explore Overwatch's capabilities for monitoring Databricks platform costs, utilization, and workloads. Learn implementation, use cases, and solutions to common observability challenges.
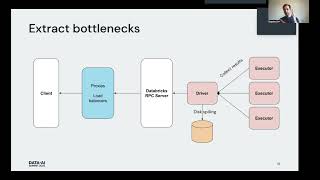
Cloud Fetch: High-Bandwidth Connectivity for BI Tools - Databricks
Explore high-bandwidth connectivity for BI tools using Cloud Fetch, a parallel data extraction mechanism that significantly speeds up query result retrieval from Databricks SQL endpoints.
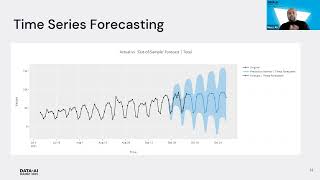
Time Series Forecasting with PyCaret
Explore automated time series forecasting with PyCaret's low-code module. Learn setup, EDA, training, and forecasting techniques to streamline your predictive modeling workflow.
Scaling XGBoost for Thousands of Features with Databricks
Scaling XGBoost for online advertising: Learn to handle thousands of features, optimize model training, and avoid common pitfalls in both Python and Scala implementations on Spark.

Discover the Data Lakehouse: Simplifying Data Architecture for Analytics and ML
Explore the data lakehouse architecture for managing massive data, supporting diverse analytics and ML requirements across multi-cloud environments, and enabling data teams to derive value efficiently.
Delta Lake Roadmap 2021 H2 - Features Overview and Community Feedback
Overview of Delta Lake's 2021 roadmap, highlighting new features, integrations, and community-driven developments for enhanced data management and analytics capabilities.
Multi-Table Transactions with LakeFS and Delta Lake - Tech Talk
Explore multi-table transactions using LakeFS and Delta Lake for collaborative data lake management, enabling CI/CD deployment and simplified multi-table pipelines in cloud storage systems.
Hot Technologies in Data Analytics - What You Need to Learn
Discover essential emerging technologies in Data Analytics and learn how to evaluate them for your career advancement.