A Collaborative Data Science Development Workflow Using Kedro and MLflow
Explore a collaborative data science workflow using Kedro pipelines, MLflow tracking, and cloud-agnostic GPU containers for efficient model development, training, and production deployment.
Growing the Delta Ecosystem - Delta-RS for Rust and Python
Explore delta-rs, a Rust library extending Delta Lake beyond Spark. Learn its current capabilities, roadmap, and real-world application in kafka-delta-ingest for high-throughput data transfer.
Why Lakehouse Architecture Now - Exploring Enterprise Data Warehouse Failures and the Need for Lakehouse Paradigm
Explore the shift from enterprise data warehouses to lakehouse architecture, focusing on benefits, challenges, and Starburst's role in powering SQL-based analytics on Delta Lake.
Creating a Lakehouse on AWS
Learn to build a Lakehouse on AWS, combining data lake affordability with data warehouse performance. Discover integration with AWS services and real-world examples of high-performance, cost-effective analytics solutions.
Building End-to-End Delta Pipelines on GCP
Explore building end-to-end Delta pipelines on GCP, covering data reliability, performance, and the Bronze-Silver-Gold architecture pattern, with practical code examples and Big Query integration.
Engagement Activity Delta Lake for Einstein Analytics and Sales Cloud Einstein
Explore how Salesforce built an engagement activity platform using Delta Lake to support Einstein Analytics and Sales Cloud Einstein, covering data ingestion, incremental reads, and mutation handling.
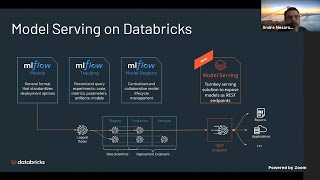
MLflow Model Serving - From Training to Production
Comprehensive overview of MLflow Model Serving, covering offline and online scoring, deployment options, and integration with Databricks, with practical examples and recent features.
Developing Scalable Machine Learning Pipelines for Gaming Industry
Explore scalable ML pipelines in gaming, leveraging Apache Spark for data-driven product development and improved user acquisition through advanced LTV modeling.
Accelerating MLOps with Apache Spark and SingleStore
Learn to accelerate MLOps using Apache Spark and SingleStore. Discover how to build fast analytical applications, manage supervised learning models, and scale AI/ML operations for data science success.
Cost Efficiency Strategies for Managed Apache Spark Service with Databricks
Explore cost-efficient strategies for Azure Databricks, including resource management, tier selection, and best practices for optimizing Apache Spark workloads in a managed cloud environment.
Migrating Airflow-Based Apache Spark Jobs to Kubernetes - The Native Way
Learn to migrate Airflow-based Apache Spark jobs to Kubernetes, reducing costs and improving stability. Explore challenges, best practices, and native Airflow integration for seamless transition from AWS EMR to K8s.
Project Zen - Improving Apache Spark for Python Users
Discover improvements in Apache Spark for Python users, including redesigned documentation, type hints, PyPI distribution options, and enhanced PySpark features for a more Pythonic experience.
Getting Started with Apache Spark on Kubernetes
Learn to deploy and optimize Apache Spark on Kubernetes with hands-on demos, covering environment setup, application sizing, performance tuning, and monitoring for efficient data pipeline management.
Building a Cloud Data Lake with Databricks and AWS - Best Practices and Implementation
Explore building a cloud data lake using Databricks and AWS. Learn about data lake architecture, AWS services, Delta Lake for reliability and performance, and best practices for implementation.
DBT Using Databricks and Delta
Learn to leverage Data Build Tool (DBT) with Databricks and Delta for efficient data lake management, including SQL-first approach, upsert capabilities, and Azure integration for enhanced observability.
SQL Analytics and the Lakehouse Architecture - Data + AI Summit EU 2020 Keynote
Explore lakehouse architecture, Delta Lake, and SQL Analytics for unified data management. Learn how this approach combines data warehouse capabilities with data lake flexibility, enabling faster analytics and decision-making.
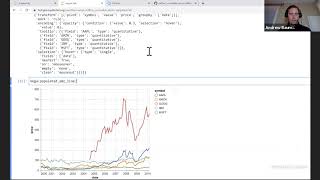
Encoding Multi-Layered Vega-Lite COVID-19 Geodata Visualizations with MLflow
Learn to create and manage multi-layered Vega-Lite visualizations for COVID-19 geodata using MLflow, enhancing data communication and lifecycle management for powerful insights.
Fugue: Unifying Big Data Analytics Ecosystems for ETL and Machine Learning
Unifying big data ecosystems with Fugue: SQL-like framework for ETL and ML pipelines, compatible with Spark, TensorFlow, and more. Simplifies development, improves performance, and enhances maintainability.
Presto on Apache Spark - A Tale of Two Computation Engines
Explore the integration of Presto and Spark, combining low-latency evaluation with robust execution for enhanced SQL experience in both interactive and batch use cases at Facebook scale.
From Idea to Model: Productionizing Data Pipelines with Apache Airflow
Learn to productionize data pipelines using Apache Airflow, bridging data science and engineering. Explore collaborative workflows, custom operators, and scalable solutions for efficient model deployment and iteration.
Simplify and Boost Spark 3 Deployments with Hypervisor-Native Kubernetes
Explore integrating Spark 3 with VMware Pacific for scalable, reliable, and high-performance big data analytics deployments using hypervisor-native Kubernetes on vSphere 7.