Clone Yourself with Azure Custom Neural Voice
Explore Azure Custom Neural Voice to create a synthesized version of your voice for various applications, from basic training to advanced techniques using larger audio datasets.
Tune and Deploy Gemini with Vertex AI and Ground with Cloud Databases
Master Gemini Pro's lifecycle: train on custom datasets, fine-tune, deploy scalable endpoints, evaluate models, and ground with Google Cloud databases for optimal AI performance.
How to Define a Storage Infrastructure for AI and Analytical Workloads
Optimize AI/ML data pipelines at scale by selecting the right storage solutions for data preparation, training, inference, and serving. Integrate with Compute Engine, GKE, or Vertex workflows.
Operationalizing Large Scale Machine Learning on Cloud TPUs with Google Kubernetes Engine
Discover efficient large-scale ML model training using Cloud TPUs and GKE. Learn orchestration techniques, TPU integration, and real-world applications for advanced ML infrastructure.
Vertex AI - Pipelines for Your MLOps Workflows
Explore Vertex AI Pipelines for MLOps workflows, covering experiment pipelining, infrastructure management, and practical examples of machine learning development and deployment cycles.
Vertex AI - Pipelines for Your MLOps Workflows
Explore Vertex AI Pipelines for streamlined MLOps workflows, covering experiment pipelining, infrastructure management, and practical examples for efficient machine learning development and deployment.

The Narrated Transformer Language Model
Visual introduction to the Transformer architecture, explaining its components and applications in AI/ML. Accessible to various experience levels, covering tokenization, embedding, and output projection.
Today Unsupervised Sentence Transformers, Tomorrow Skynet - How TSDAE Works
Explore unsupervised fine-tuning for sentence transformers using TSDAE. Learn to train models without labeled data, ideal for domains and languages with limited resources.
Making Neural Networks Run in Browser With ONNX
Explore ONNX format for deploying machine learning models to edge devices, including training, conversion, and deployment using high-performance JavaScript runtime.
Machine Learning for Software Developers and Knitters
Explore AI/ML applications, AWS services, and a unique demo on teaching computers to reverse engineer knitting patterns. Gain insights into creative uses of machine learning for developers.
Building an Enterprise Scale MLOps Platform - From Development to Deployment
Discover how NatWest built a streamlined MLOps platform to enhance productivity, automate ML workflows, and ensure security compliance in enterprise-scale machine learning operations.
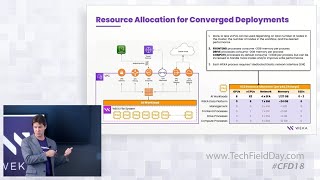
WEKA Converged Mode for AWS - Resource Efficiency for AI Workloads
Discover how WEKA's innovative Converged Mode optimizes GPU-accelerated workloads and AI model training in AWS, improving resource efficiency and performance for cloud deployments.
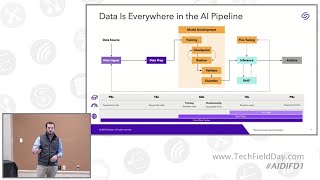
Data Infrastructure's Impact on AI Value Creation
Explore how data infrastructure shapes AI development, from training data quality to edge computing deployment, emphasizing storage solutions and performance optimization across the complete AI pipeline.
How to Fine-Tune Mamba for Question Answering
Dive into practical Mamba language model fine-tuning for question-answering tasks, from basic prompt engineering to complete model training implementation.
Direct Preference Optimization (DPO) vs RLHF - Understanding Language Model Training
Delve into Direct Preference Optimization (DPO) and discover how it eliminates the need for separate reward models in language model training, offering a more efficient alternative to RLHF.
Teaching Language Models to Use Tools - Deep Dive into Toolformer
Explore how language models can self-learn to utilize tools through API calls, covering architecture, training data generation, filtering mechanisms, and experimental results from Meta's Toolformer paper.
Understanding 1-Bit Large Language Models - From Theory to Implementation
Dive into the revolutionary concept of 1-bit Large Language Models, exploring how weights can be represented with simple integers (0, 1, -1) instead of complex floating-point numbers.
Understanding How Llama 3.1 Works - A Technical Deep Dive
Dive into Meta's groundbreaking Llama 3 architecture, exploring pre-training techniques, model capabilities, synthetic data quality, and implementation strategies for advanced AI development.
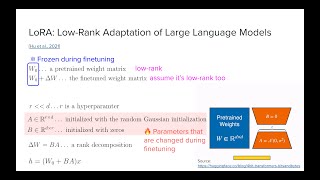
Parameter-Efficient Finetuning - QLoRA and LoRA Methods
Explore parameter-efficient fine-tuning techniques with LoRA and QLoRA, learning how to optimize large language models while maintaining performance and reducing computational costs.
Demystifying the Communication Characteristics for Distributed Transformer Models
Explore communication patterns and optimization strategies for distributed transformer models, focusing on collective operations and performance characteristics in large-scale deployments.
Hyperparameter Tuning on the Cloud - Optimizing Machine Learning Models with SEER and Rubberband
Master hyperparameter tuning optimization in cloud environments through SEER algorithm and Rubberband system, focusing on maximizing model accuracy while minimizing costs and time constraints.