On-Device Speech Models Optimization and Deployment for Mobile Hardware
Explore on-device speech model optimization and deployment, covering streaming-aware design, quantization techniques, and benchmarks for popular speech processing model topologies on mobile platforms.
Tiny Models with Big Appetites: Cultivating the Perfect Data Diet for Computer Vision
Explore techniques for curating optimal training datasets and designing sampling strategies for tiny computer vision models, emphasizing data quality and model robustness in real-world environments.
Delta Keyword Transformer: Bringing Transformers to the Edge Through Dynamically Pruned Multi-Head Self-Attention
Explore cutting-edge techniques for optimizing Transformers in edge computing, focusing on the Delta Keyword Transformer and its dynamic pruning approach for efficient multi-head self-attention.
Embedded Machine Learning in the Real World
Explore embedded ML applications, challenges, and opportunities in real-world scenarios, focusing on tiny models, accelerated hardware, and practical tooling.
Tiny but Powerful: Hardware for High Performance, Low Power Machine Learning
Explore cutting-edge hardware for ultra-low power machine learning at the edge, covering TinyML applications, model optimization, and emerging trends in efficient computing.
Train One Network and Specialize It for Efficient Deployment
Explore efficient neural network deployment across diverse devices using the Once-for-All network approach, which enables quick specialization without retraining and outperforms state-of-the-art methods on edge devices.
Avoiding Loss of Quality in Tiny Models - Neuton.ai Partner Session
Explore compact AI models without sacrificing quality. Learn to assess model quality, understand decision-making logic, evaluate training data, and interpret model outputs for tinyML applications.
Hardware Aware Training for Efficient Keyword Spotting - tinyML Research Symposium 2021
Explore hardware-aware training for efficient keyword spotting, focusing on Legendre Memory Unit networks to achieve state-of-the-art accuracy and power efficiency on various hardware platforms.
How Amazon Search Leverages PyTorch to Build and Deploy LLMs in Production
Explore Amazon Search's innovative use of PyTorch and its ecosystem for building and deploying large language models in production environments.
ML On-Device: Building Efficient Models
Explore on-device machine learning for efficient, privacy-preserving models on mobile and edge devices. Learn about real-time AI applications, model optimization, and deployment strategies.
CNN Training Loop Explained - Neural Network Code Project
Learn to build a convolutional neural network training loop using Python and PyTorch. Gain practical skills in implementing deep learning algorithms for image processing tasks.
Hyperparameter Tuning Using Kubeflow
Explore automated machine learning with Katib, a Kubernetes-native platform for hyperparameter tuning and neural architecture search, enhancing model performance efficiently.
AI Model Efficiency Toolkit
Explore cutting-edge techniques for optimizing AI models with Qualcomm's toolkit, enhancing performance and efficiency in machine learning applications.

ORPO: Monolithic Preference Optimization without Reference Model
Innovative approach to language model preference alignment without separate fine-tuning, achieving state-of-the-art performance using odds ratio optimization across various model sizes.
Prompt Engineering with Watsonx - Workshop
Aprenda técnicas de engenharia de prompts para otimizar modelos de linguagem, equilibrando inteligência e segurança. Exercícios práticos para dominar habilidades essenciais na interação com LLMs.
Leveraging Open-Source LLMs for Production
Explore open-source LLMs, comparing them to proprietary options. Learn about hosting costs, performance evaluation, and practical applications. Gain insights into fine-tuning techniques and emerging trends in AI development.
PyTorch 2.1 - New Features and Accelerating Generative AI Models
Explore PyTorch 2.1's new features for AI model acceleration, including compile, distributed, inference, and edge technologies, with insights on optimizing generative AI models for enhanced performance.
Shrinking Deep Learning Models: Techniques and Energy Considerations
Explore techniques to shrink deep learning models, reduce energy consumption, and run advanced architectures on commodity hardware. Gain insights into model efficiency and accessibility.
Strategies for Efficient LLM Deployments in Any Cluster
Explore strategies to optimize LLM deployments in Kubernetes clusters, focusing on reducing model size, improving resource utilization, and balancing performance with efficiency for cloud-to-edge scenarios.
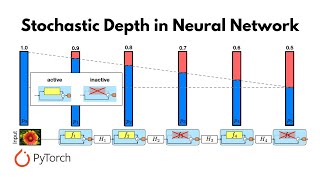
Stochastic Depth for Neural Networks - Implementation and Analysis
Explore stochastic depth in neural networks: a regularization method for residual networks that enhances training speed and test performance. Includes methodology explanation and PyTorch implementation.
LLM Efficient Inference in CPUs and Intel GPUs - Intel Neural Speed
Optimize LLM inference on Intel CPUs and GPUs using Neural Speed. Explore efficient techniques for enhanced performance in machine learning and data science applications.