3D Printing: Sculpting, Detailing, and Preparation for Resin Printing - Week 3
Learn advanced 3D printing techniques for resin models, including layered sculpting, detail optimization, and print preparation. Gain insights on client approaches and industry trends.
ZBrush 2024 - Cosmo Armor 3D Printing Preparation Tutorial
Explore ZBrush 2024 techniques for 3D printing cosplay armor with Ian Robinson. Learn about model preparation, detailing, and optimization for successful costume creation.
3D Printing Post-Production: Exporting and Slicing - Week 4
Explore advanced 3D printing techniques, from ZBrush export to Lychee Slicer optimization. Learn model preparation, support structures, hollowing, and troubleshooting for successful prints.
Lightweight Deep Learning on Edge Devices - Energy Efficient Approaches
Discover efficient deep learning techniques for edge devices, focusing on energy-saving approximation methods that maintain accuracy while improving performance on smartphones and IoT devices.
Efficient Edge Computing: Unleashing the Potential of AI/ML with Lightweight Kubernetes
Explore deploying AI/ML models in edge scenarios, comparing traditional and lightweight Kubernetes distributions. Learn strategies for efficient edge computing, including power consumption, model size, and performance optimization.
Bringing AI to the Heterogeneous Edge with WebAssembly and ONNX
Explore deploying AI workloads to edge devices using WebAssembly and ONNX, addressing challenges of heterogeneous environments, security, and resource constraints in a multiplatform development approach.
Importing Geopipe New York City 3D Models into Unreal Engine 5.1 - Game Ready with Collision
Step-by-step guide to import New York City 3D models from Geopipe into Unreal Engine 5.1, creating a game-ready scene with perfect collision for immersive game development projects.
Importing 100 Mixamo Characters into Smile Game Builder
Learn to import 100 free Mixamo characters into Smile Game Builder using 3DXchange and Simplygon. Step-by-step tutorial covers workflow and software integration for game development.

LLM Deployment Techniques - Lecture 13
Dive into advanced LLM deployment strategies, covering optimization techniques, infrastructure scaling, and practical implementation methods for efficient large language model deployment.

EfficientML.AI - Introduction to Efficient Machine Learning
Master efficient machine learning techniques and optimization strategies for deploying ML models in resource-constrained environments, focusing on practical implementation methods.
LLM Deployment Techniques - Lecture 13
Dive into advanced LLM deployment strategies, covering optimization techniques, infrastructure scaling, and practical implementation methods for efficient large language model deployment in production environments.

Quantization in Deep Learning: Types, Algorithms, and Implementation
Explore quantization techniques in deep learning, from uniform to non-uniform approaches, and learn practical implementation strategies for optimizing large-scale neural networks.

QLoRA: Efficient Training of Large Language Models Using Quantization and Low-Rank Adaptation
Discover how QLoRA enables efficient training of large language models on a single GPU through innovative techniques like NormalFloat, Double Quantization, and Paged Optimizers.
CriticGPT: Understanding RLHF and Force Sampling Beam Search Optimization
Dive into OpenAI's innovative CriticGPT algorithm, exploring how RLHF and Force Sampling Beam Search optimize language models and enhance their reliability.
LoftQ: Understanding LoRA-Fine-Tuning-aware Quantization for LLMs
Dive into LoftQ, a groundbreaking LLM quantization method that combines with LoRA to achieve superior performance and efficiency in large language models.
ChatGPT vs Flan-T5: Comparing Proprietary and Free LLMs with Performance Tuning
Explore the differences between ChatGPT and Flan-T5 LLM models, comparing their capabilities, accessibility, and performance optimization through practical demonstrations and hyperparameter tuning techniques.
Running Flan-T5-XL Model on Google Colab - A Free Self-Explaining Language Model
Discover how to implement and optimize the Flan-T5-XL language model on Google Colab, exploring its capabilities in reasoning, essay writing, and translation tasks while working within free resource constraints.
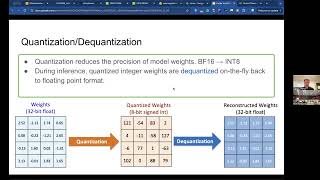
Faster and Cheaper LLMs with Weight and Key-value Cache Quantization
Explore advanced techniques for optimizing Large Language Models through weight and key-value cache quantization methods to improve speed and reduce computational costs.
Accelerating High-Performance Machine Learning at Scale in Kubernetes
Hands-on guide for deploying optimized machine learning models in cloud native ecosystems, focusing on GPT-2 NLP model deployment in Kubernetes using ONNX Runtime and Seldon Core Triton server.
EfficientNetV2 - Smaller Models and Faster Training - Paper Explained
Explore EfficientNetV2's improved image classification performance, including progressive training, Fused-MBConv layer, and novel reward function for Neural Architecture Search.
How to Make Your CPU as Fast as a GPU - Advances in Sparsity with Nir Shavit
Explore advances in sparsity and how CPUs can match GPU performance in neural networks. Learn about pruning, efficient algorithms, and the future of sparse architectures in deep learning.