Interpretable Machine Learning - Data Brew Season 2 Episode 7
Explore interpretable machine learning with Ameet Talwalkar, discussing its relation to data privacy, fairness, and practical applications in this insightful interview on cutting-edge ML research.
Mitigating Bias in Models with SHAP and Fairlearn
Learn techniques to identify and mitigate bias in machine learning models using SHAP and Fairlearn, enhancing fairness and transparency in AI systems.
SHERPA: Explainable Robust Algorithms for Privacy-Preserved Federated Learning in Future Networks
Explore robust algorithms for privacy-preserved federated learning in future networks, focusing on explainable and secure data collaboration techniques.
Machine Learning - From Black Boxes to White Boxes - Mihaela van der Schaar
Exploring innovative approaches to make complex machine learning models interpretable and trustworthy, especially in medical applications, for diverse users including clinicians and patients.
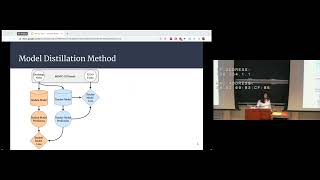
Model Distillation for Faithful Explanations of Medical Code Predictions
Explore knowledge distillation techniques for generating faithful explanations of medical code predictions, enhancing trust in machine learning models for clinical decision-making.
Linguistic Interaction in Humans and Machines - Understanding Higher-Level Intelligence
Exploring methods from cognitive science to study ML models and human cognition, focusing on language-based projects that analyze adaptation and generalization in linguistic interactions.
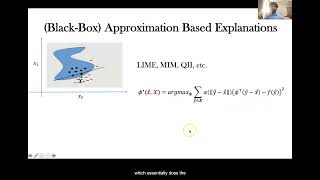
Model Explanations with Differential Privacy
Explore techniques for generating privacy-preserving explanations of machine learning models, balancing transparency with data protection in AI systems.
Ethical ML - Who's Afraid of the Black Box Models
Explore ethical machine learning beyond interpretability, focusing on responsible data handling and fairness testing to meet GDPR and ALTAI guidelines while using black-box models.
Trust Me, I'm a Data Scientist - Ethics for Builders of Data-Based Applications
Explore ethical pitfalls in data science through a practical example, covering algorithmic fairness, model interpretability, and handling minority classes in AI applications.
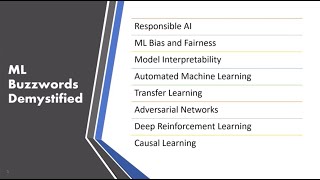
ML BuzzWords Demystified
Demystifies latest ML trends like Reinforcement Learning, AutoML, and ML bias. Provides clear insights into complex concepts, ensuring you're up-to-date with the field's advancements.
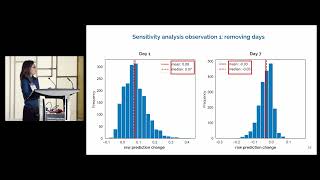
Sensitivity and Interpretability of AI Models in Regulated Industries
Explore sensitivity analysis for AI model interpretability in regulated industries. Learn design and implementation approaches using case studies from healthcare and human activity data.
Responsible AI: Challenges and Emerging Practices - Keynote
Explore challenges and emerging practices in responsible AI, including unintended consequences, model interpretability, fairness, and engineering objectives.
Where Did My Model Go Wrong? Toolkits of Interpretability, Bias and Fairness to the Rescue
Explore techniques to identify and correct biases in machine learning models, interpret results, and ensure fair outcomes in model development and deployment.
Interpretable Self-Explanatory Machine Learning Models
Explore interpretable machine learning models that are self-explanatory, focusing on making complex neural networks more transparent and understandable for critical applications.
Computational Social Choice and AI Value Learning
Explore computational social choice and AI value learning, focusing on misspecification in RLHF, model interpretability, and foundation model capability evaluations.
How to Interpret and Explain Black Box Models
Explore popular model explanation techniques for machine learning interpretability, including LIME, SHAP, and visual analytics. Gain insights into making complex models more understandable and explainable.
A Journey Towards Explainable AI and Its Societal Implications - From Trust Issues to Complex Models
Explore the principles of explainable AI, from feature-based to data-driven models, examining key algorithms like LIME and Shapley while understanding their broader societal impact and applications in search systems.
Responsible AI Toolbox: Practical Approaches and Tools for Ethical Machine Learning
Explore practical approaches to responsible AI and learn how open-source and cloud-integrated capabilities empower data scientists to understand and improve ML models ethically.
DNN-GP: Diagnosing and Mitigating Model's Faults Using Latent Concepts
Explore an innovative fault diagnosis tool for Deep Neural Networks that interprets latent concepts to detect and mitigate various model vulnerabilities, from adversarial attacks to concept drift.
Scalably Understanding AI with AI - Using AI Systems for Model Behavior Analysis
Explore advanced techniques for analyzing AI systems, from behavior elicitation to neuron description, focusing on using AI tools to understand and improve AI model behaviors and representations.