Production RL and Decision-Making with RLlib
Learn to implement production-ready reinforcement learning and decision-making systems using RLlib, exploring real-world applications, challenges, and best practices.

Explaining OpenAI's O1 Reasoning Models - Analysis and Demonstration
Explore OpenAI's o1 models: their reasoning capabilities, trade-offs, and performance in various tasks. Includes demos and pricing information for practical understanding.
Gemma 2 2B: Performance and Safety Testing of DeepMind's New Small Language Model
Explore DeepMind's Gemma 2 2B: capabilities, safety features, and real-world performance in this comprehensive analysis of the latest small language model.
Model Evaluation for Computer Vision - Precision, Recall, F1 Score, and Confusion Matrix
Explore key metrics for evaluating computer vision models, including precision, recall, F1 score, and confusion matrices, to enhance your understanding of model performance.
BLEURT - Learning Robust Metrics for Text Generation
Explora BLEURT, una métrica de evaluación basada en BERT para generación de texto, su preentrenamiento con datos sintéticos y su capacidad de modelar juicios humanos con pocos ejemplos.
Machine Learning - Testing and Error Metrics
Explore machine learning model evaluation, including metrics, error types, cross-validation, and optimization techniques for improved performance and decision-making.
Tune and Deploy Gemini with Vertex AI and Ground with Cloud Databases
Master Gemini Pro's lifecycle: train on custom datasets, fine-tune, deploy scalable endpoints, evaluate models, and ground with Google Cloud databases for optimal AI performance.
Inside TensorFlow - Parameter Server Training
Explore parameter server training in TensorFlow for scaling model training across multiple machines, covering concepts, APIs, limitations, and future developments.
Gone Phishing: Lessons Learned Training a Phishing Email Classifier with Highly Imbalanced Biased Labels
Explore challenges and solutions in training a phishing email classifier with imbalanced, biased data. Learn practical strategies for evaluation and deployment in real-world scenarios.
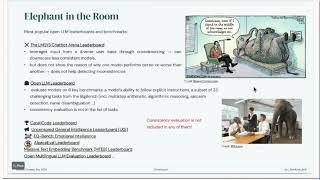
The Dual Nature of Consistency in Foundation Models - Challenges and Opportunities
Explore the complexities of consistency in Large Language Models, including measurement methods, mitigation strategies, and leveraging opportunities for improved model reliability.
Machine Unlearning - Addressing Bias, Privacy, and Regulation in LLMs and Multimodal Models
Explore techniques for machine unlearning in AI models, focusing on bias removal, data privacy, and regulatory compliance while maintaining model performance and fostering responsible AI development.
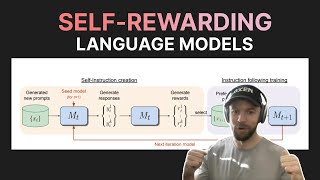
Deep Dive Into Self-Rewarding Language Models - Training Models as Their Own Judges
Explore how language models can be trained to evaluate and improve themselves, eliminating the need for human-labeled data while achieving superior performance in AI development and training.
Fine-Tuning Self-Rewarding Language Models with Mistral 7B
Dive into implementing Meta's Self-Rewarding Language Model with Mistral 7B, covering fine-tuning techniques, data preparation, prompt generation, and practical demonstrations.

Decision Trees and Overfitting in Machine Learning - Lecture 5
Dive into practical aspects of decision tree learning, exploring overfitting challenges and essential implementation considerations in machine learning applications.
Introduction to Machine Learning: Regression - Part 1
Explore regression in machine learning: estimate relationships, predict outcomes, and apply algorithms for continuous target variables. Learn evaluation techniques and practical considerations.
Where Did My Model Go Wrong? Toolkits of Interpretability, Bias and Fairness to the Rescue
Explore techniques to identify and correct biases in machine learning models, interpret results, and ensure fair outcomes in model development and deployment.
Building Profitable Models - Lessons from Marks and Spencer
Discover strategies for creating successful, profitable data models in supply chain and product lifecycle management, focusing on decision-making processes and forecast accuracy.
A Guide to Cross-Validation for AI - Avoiding Overfitting and Ensuring Generalizability
Explore cross-validation techniques for AI, including K-fold and nested methods. Learn to avoid overfitting, ensure generalizability, and select optimal approaches for model evaluation.
DynaTask: A New Open Source Approach for AI Benchmarking
Explore DynaTask, a novel open-source AI benchmarking paradigm using dynamic adversarial data collection to evaluate and assess AI model vulnerabilities to human deception.
How to Fine-Tune LLMs for Specialized Enterprise Tasks - Curating Data and Emerging Methods
Explore fine-tuning methods for LLMs, learn to curate high-quality training data efficiently, and understand evaluation techniques for accurate enterprise deployment of specialized language models.
Task Me Anything: Revolutionizing Multimodal Model Benchmarking
Explore Task Me Anything platform for efficient multimodal model evaluation. Learn programmatic task generation and active learning techniques to create custom benchmarks for data science projects.