Automating FAA's SWIM Data Ingestion and Analysis with Databricks
Automating FAA's SWIM data ingestion and analysis using cloud-based services, showcasing infrastructure setup, configuration, and insights derived from flight data for improved air transportation management.
Data Microservices in Apache Spark Using Apache Arrow Flight
Explore efficient machine learning pipelines using Apache Arrow Flight in Spark, enabling faster data transport and simplified microservices for improved ML model production.
Data Science Across Data Sources with Apache Arrow - Accelerating Analytics and Interoperability
Explore Apache Arrow's columnar in-memory data representation for real-time analytics across distributed systems. Learn how it accelerates data processing and enables interoperability between various analytical tools and data sources.
Building a Streaming Microservice Architecture with Apache Spark Structured Streaming
Explore building a scalable, fault-tolerant streaming microservice architecture using Apache Spark, Kafka, gRPC, and Delta Lake for real-time data processing and reliable insights.
Running Apache Spark Jobs Using Kubernetes
Learn to run Apache Spark jobs on Kubernetes, unifying analytics and data science on a cloud-native architecture. Discover how this approach simplifies infrastructure, enables on-demand deployment, and eliminates big data cluster overhead.
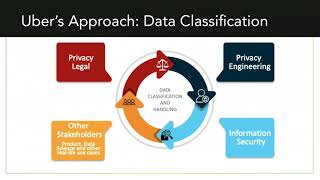
Privacy by Design for Agile Development - Uber's Approach
Integrating privacy by design principles in agile development at Uber: challenges, strategies, and practical approaches for ensuring data protection in a fast-paced tech environment.
From Buy to Build - The Case for Building a Digital Automation Platform
Explore the shift from buying to building digital automation platforms, focusing on microservices architecture and process orchestration for enhanced business agility and scalability.
External Tasks for Service Orchestration
Explore external tasks in service orchestration, their advantages, and practical applications for efficient process management and scalable architectures.
Fluentd - A Complete Logging Ecosystem for Kubernetes
Explore Fluentd's internals, best practices, SDKs, and sub-projects for efficient logging in cloud-native environments, with a focus on Kubernetes integration and operational challenges.
Building Cloud Integration Applications Through Knative and Apache Camel
Explore cloud-native integration using Knative and Apache Camel, focusing on EIP DSL for middleware integration and leveraging serverless frameworks for efficient service connectivity in modern applications.
Hail Hydrate - From Stream to Lake Using Open Source
Explore open-source tools for efficient data streaming and lake management, enhancing your skills in modern data architecture and processing techniques.
Astronomer's Journey from Cloud Lock-in to Open Source Independence
Discover how Astronomer transitioned from AWS-managed services to open-source solutions, enhancing flexibility and independence in their data engineering platform.
Building Robust Streaming Data Pipelines with Apache Spark
Learn to build robust streaming data pipelines using Apache Spark, Kafka, and Camel. Explore ETL challenges, data management, and lessons from running these technologies in Docker.
Highly Available Search Platform for Data Resilience and Compliance at Shopify
Explore Shopify's highly available search platform, leveraging Kafka for real-time indexing and Elasticsearch for efficient querying across global regions, ensuring data resilience and compliance.
How Camunda 8 Manages Diverse Endpoints in Distributed Systems
Explore Camunda 8's integration of diverse endpoints in distributed systems, showcasing flow logic implementation and end-to-end process visualization across microservices, people, and devices.
Apache Arrow and Go: A Match Made in Data
Explore Apache Arrow's Go implementation, covering Arrow and Parquet libraries, Flight server/client, C Data API integration, and performance optimization techniques.
Logging Modernization and Cybersecurity at Scale with MiNiFi, Kafka and Flink
Modernize logging and enhance cybersecurity using MiNiFi, Kafka, and Flink. Learn efficient log collection, processing, and streaming analytics for global network monitoring and alert generation.
Building a Real-Time Analytics Database
Odkryj tajniki tworzenia bazy danych do analityki w czasie rzeczywistym. Poznaj kluczowe koncepcje i najlepsze praktyki w tej dziedzinie.
Evolution of Real-time User Engagement Event Consumption at Pinterest - Current 2023
Explore Pinterest's evolution in real-time event processing using Apache Flink, improving data quality and efficiency while saving millions in infrastructure costs and boosting user engagement.
Data Pipelines Evolution from Batch to Streaming
Explore the evolution from batch to streaming data pipelines using Apache Flink and Kafka. Learn strategies for seamless transition, including query-based connectors, change data capture, and handling late events.
Streaming vs. Batch Processing: The Future of Data Architecture
Explore the future of data processing with industry experts as they debate streaming vs. batch, adoption challenges, and best practices for real-time data architecture.