Kafka Streams - Real-time Stream Processing - Book Appendix
Learn real-time stream processing with Kafka Streams, from installation to application development and testing. Covers multi-node clusters, Windows setup, and IntelliJ IDEA configuration.
Building Data Infrastructure at Scale for AI/ML with Open Data Lakehouses
Explore how data lakehouse architecture with Apache Hudi supports real-world predictive ML and vector-based AI use cases in this 30-minute keynote by Vinoth Chandar, creator of Apache Hudi. Learn about ingesting data with minute-level freshness, providin…
Real-Time Data Streaming Architectures for Generative AI
Explore the evolution of data processing architectures for Generative AI in this 12-minute talk by Emily Ekdahl at the MLOps.community event. Discover how real-time data streaming solutions using Apache Kafka and Apache Flink are revolutionizing the way…

A Kafka Producer's Request: From Send() to Disk and Back
Explore the intricate journey of data into Apache Kafka® in this 49-minute conference talk from Devoxx. Delve into the complex process behind the seemingly simple producer.send() call, tracing the path of a request from its inception to disk storage and…
Data Streaming with Confluent: Stream, Connect, Govern, and Process Information
Explore the world of data streaming through this 39-minute conference talk from Devoxx. Dive into Confluent's Data Streaming Platform and discover how to Stream, Connect, Govern, and Process large volumes of information effectively. Learn about the revol…
Realtime Streaming for Anomaly Detection - An End-to-End Data Engineering Project
Build a real-time anomaly detection system using streaming data engineering techniques. Learn end-to-end implementation for monitoring and identifying unusual patterns in data streams.

15 Essential Do's and Don'ts with Apache Kafka
Discover 15 crucial best practices for Apache Kafka, covering naming conventions, replication, partitioning, data quality, and more. Gain practical insights to optimize your Kafka environment.

Dynatrace Extensions 2.0 for Visual Studio Code - Tutorial and Live Demo
Extend Dynatrace's observability capabilities using Extensions 2.0 framework. Learn to develop, test, and manage extensions with the new Visual Studio Code Add-On through a hands-on Apache Kafka example.
Building a CML Pipeline with Spark and Kafka - YOW! 2018
Explore building a CML pipeline using Apache Spark and Kafka. Learn functional programming techniques for efficient data processing and machine learning workflows.
Replication in Apache Kafka Explained - Monitoring and Troubleshooting Data Streaming Applications
Explore Apache Kafka® replication: challenges, approaches, monitoring, and failure handling. Gain practical insights through Docker and Jupyter notebook experiments, with code available on GitHub.
A Kafka Producer's Request: From Send() to Disk and Back
Explore the lifecycle of Kafka producer requests, from initial call to disk storage and back, enhancing your debugging and performance analysis skills for Apache Kafka.

Streams API for Apache Kafka - Produced by Confluent
Learn to build real-time data processing applications using Apache Kafka's Streams API, covering creation, data transformation, and advanced techniques.
Docker
Comprehensive guide to Docker, covering containerization, databases, message queues, and microservices with practical examples and performance insights.

Distributed Systems
Learn key concepts in distributed systems including multiprocessing, concurrent requests, transactions, caching, and publish-subscribe architecture through practical examples and real-world scenarios.
Apache Kafka Crash Course
Comprehensive introduction to Apache Kafka, covering core concepts, architecture, and hands-on implementation. Includes practical examples, coding demonstrations, and discussion of pros and cons.
Apache Kafka Tutorial for Beginners
Learn Apache Kafka fundamentals, including topics, partitions, producers, and consumers in this comprehensive beginner-friendly tutorial.
Apache Kafka for Beginners
Learn Apache Kafka fundamentals: topics, partitions, brokers, producers, consumers, and enterprise architecture. Understand core concepts and ecosystem components in this concise introduction.
Apache Kafka Streams for Data Processing
Learn to process data with Apache Kafka Streams, covering core concepts, application setup, WordCount topology, and various stream processing techniques.
Apache Kafka - Confluent Schema Registry & REST Proxy
Learn to implement Schema Registry in Kafka, write Avro producers, and understand the architecture of Schema Registry and REST Proxy for efficient data serialization and management.
Apache Kafka Cluster Setup & Administration
Learn to set up and manage Apache Kafka clusters, including Zookeeper configuration, cloud provider considerations, and cluster sizing for optimal performance.
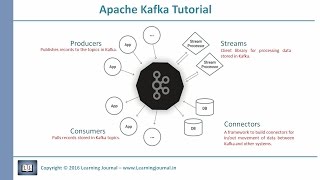
Apache Kafka Tutorials
Comprehensive tutorials on Apache Kafka, covering core concepts, installation, APIs, configurations, and advanced topics for building real-time data streaming applications.