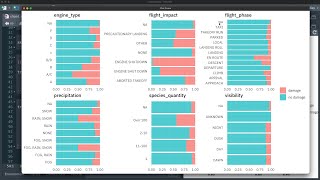
Class Imbalance and Classification Metrics With Aircraft Wildlife Strikes
Explore how handling class imbalance affects classification metrics using aircraft wildlife strike data, with focus on sensitivity and specificity in predictive modeling.
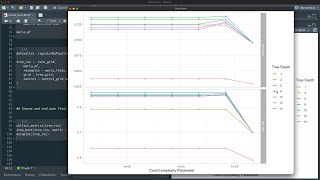
Partial Dependence Plots for Mario Kart World Records
Explore decision tree modeling and partial dependence profiles for Mario Kart world records using tidymodels and DALEX, with a focus on predicting shortcut usage.
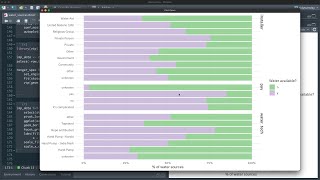
Predict Water Availability in Sierra Leone With Random Forests
Explore random forest modeling with tidymodels to analyze water sources in Sierra Leone, covering data preparation, model building, and evaluation techniques.
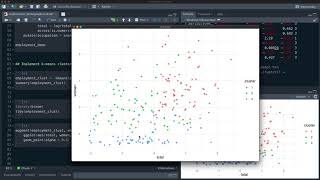
Explore Demographic Employment Data With K-Means
Explore employment demographics using k-means clustering to identify similarities across industries and roles, with hands-on data analysis and visualization techniques.
Predict Class Membership for the Datasaurus Dozen With Tidymodels
Explore multiclass evaluation metrics for random forest models using the Datasaurus Dozen dataset, focusing on model performance and visualization techniques.
Impute Missing Data and Handle Class Imbalance for Himalayan Climbing Expeditions
Learn to predict survival in Himalayan climbing expeditions using tidymodels in R. Explore data handling, imputation, and modeling techniques for imbalanced datasets.
Getting Started with Jupyter Notebook
Learn to create interactive computational documents with Jupyter Notebook, exploring its architecture, features, and practical applications in data analysis and machine learning.
Redash - Open Source SQL Analytics on Data Lakes
Explore open-source SQL analytics on data lakes using Redash. Learn to create dashboards, develop workflows, and connect to Databricks for comprehensive analytics with Managed Delta Lake.
Data Microservices in Apache Spark Using Apache Arrow Flight
Explore efficient machine learning pipelines using Apache Arrow Flight in Spark, enabling faster data transport and simplified microservices for improved ML model production.
AutoML Toolkit Deep Dive - Automating Feature Engineering and Model Optimization
Explore Databricks Labs' AutoML Toolkit for automating feature engineering, model selection, tuning, and deployment. Learn to accelerate machine learning workflows and enhance productivity.
Introducing Apache Spark 3.0 - A Decade of Progress and Future Outlook
Apache Spark 3.0: Reflecting on a decade of progress and unveiling new features to enhance data processing accessibility, speed, and compatibility across various sources and environments.
Managing the Complete Machine Learning Lifecycle with MLflow - Introduction to MLflow Tracking
Introduction to MLflow: tracking experiments, packaging projects, deploying models, and managing lifecycle. Learn to record, reproduce, and compare ML runs using MLflow's components and UI.
State of the Industry - Machine Learning Platforms and MLOps
Explore the state of MLOps and ML platforms with industry leaders, focusing on challenges, common components, and Databricks' approach to unified data analytics and machine learning.
Predictive Maintenance on IoT Data for Early Fault Detection with Delta Lake
Explore predictive maintenance using IoT data and Delta Lake for early fault detection. Learn about Industry 4.0 applications, data analytics, and machine learning techniques for improved efficiency and cost savings.
How to Build a Cloud Data Platform - Machine Learning and Business Intelligence - Part 4
Learn to leverage Delta Lake for dashboards and advanced analytics, enabling downstream teams with machine learning and business intelligence capabilities on a unified data platform.
How Slot Machines Are Advancing the State of the Art in Computer Go AI
Explore Monte Carlo Tree Search in computer Go AI, covering its advantages, UCB1 strategy, and recent refinements like AMAF/RAVE, with insights into ongoing research topics.
How to Build a Cloud Data Platform - Part 1: Architecture
Learn to build a unified cloud data platform using Delta Lake, combining data warehouses and lakes for improved reliability, performance, and operations.
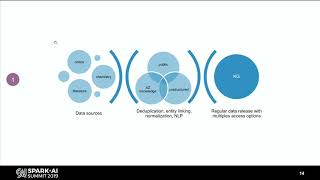
Building a Knowledge Graph with Spark and NLP for Novel Drug Recommendations
Explore drug discovery using knowledge graphs, NLP, and Spark. Learn techniques for efficient data processing, entity recognition, and relationship extraction to enhance pharmaceutical research.
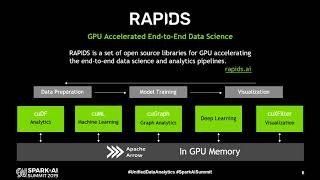
Accelerating Apache Spark with GPUs Using RAPIDS
Explore GPU acceleration for data science with RAPIDS, offering significant performance gains over CPU-only solutions. Learn its functionality, architecture, and integration with Apache Spark for large-scale computation.
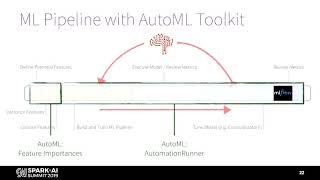
Augmenting Machine Learning with Databricks Labs AutoML Toolkit
Explore how Databricks Labs AutoML Toolkit simplifies and optimizes machine learning processes, from data preparation to model optimization, using financial loan risk data examples.
Revolutionizing Legal Industry with Spark, NLP and Azure Databricks - Clifford Chance Case Study
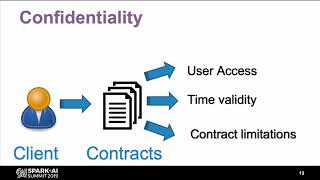
Explore how a top law firm revolutionizes operations using advanced analytics, Spark, NLP, and Azure Databricks to handle millions of legal documents and enhance client relationships.