Fugue: Unifying Big Data Analytics Ecosystems for ETL and Machine Learning
Unifying big data ecosystems with Fugue: SQL-like framework for ETL and ML pipelines, compatible with Spark, TensorFlow, and more. Simplifies development, improves performance, and enhances maintainability.
From Idea to Model: Productionizing Data Pipelines with Apache Airflow
Learn to productionize data pipelines using Apache Airflow, bridging data science and engineering. Explore collaborative workflows, custom operators, and scalable solutions for efficient model deployment and iteration.
Simplify and Boost Spark 3 Deployments with Hypervisor-Native Kubernetes
Explore integrating Spark 3 with VMware Pacific for scalable, reliable, and high-performance big data analytics deployments using hypervisor-native Kubernetes on vSphere 7.
Modernizing Apache Spark 3.0 Applications - Best Practices and Optimization Techniques
Optimize legacy Spark applications for 3.0: leverage Adaptive Query Execution, columnar processing, GPU acceleration, and ML integration. Concrete examples and lessons from modernizing analytics workloads.
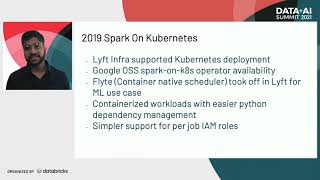
Hybrid Apache Spark Architecture: Optimizing YARN and Kubernetes for Lyft's Workloads
Explore Lyft's hybrid Apache Spark architecture using YARN and Kubernetes, addressing scalability challenges and optimizing workload management for improved reliability and efficiency.
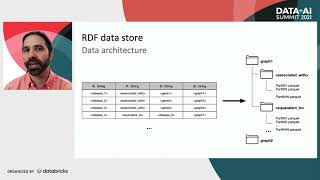
Drug and Vaccine Discovery Using Knowledge Graphs and Apache Spark
Explore how GSK uses knowledge graphs and Apache Spark to build a massive medical database, enabling advanced drug and vaccine discovery through innovative data querying and machine learning techniques.
Scaling AI at H&M - Democratizing and Accelerating AI Usage
H&M's evolving AI platform democratizes and accelerates AI usage across the group, focusing on speed to production, data abstraction, feature store, and pipeline orchestration for efficient model management and development.
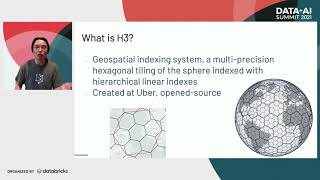
Large Scale Geospatial Indexing and Analysis on Apache Spark
Explore large-scale geospatial indexing and analysis using Apache Spark, covering challenges, frameworks, data structures, and practical applications in cloud-first architecture with Databricks.
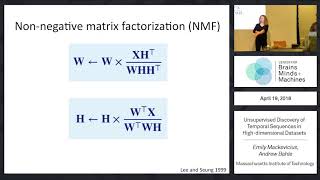
Unsupervised Discovery of Temporal Sequences in High-Dimensional Datasets
Explore unsupervised discovery of temporal sequences in high-dimensional datasets using seqNMF, a tool extending convolutional NMF. Learn to extract and validate neural sequences from large-scale recordings.
What is Your Data Worth? Equitable Data Valuation in Machine Learning
Explore equitable data valuation in machine learning, focusing on Data Shapley Value and its applications in healthcare, face recognition, and NLP.
Enable Production ML with Databricks Feature Store
Simplify production ML with Databricks Feature Store. Learn to overcome data challenges, enable real-time inference, and streamline ML projects using a unified data lakehouse platform integrated with Apache Spark and MLflow.
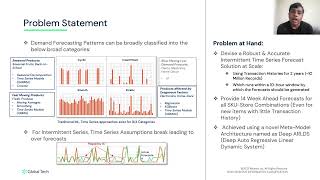
Intermittent Demand Forecasting at Scale Using Meta-Modeling - Deep Auto-Regressive Linear Dynamic Systems
Discover Walmart's innovative solution for predicting demand of slow-moving items using meta-modeling, combining linear dynamic systems and deep auto-regressive networks for accurate forecasts across thousands of SKUs and stores.
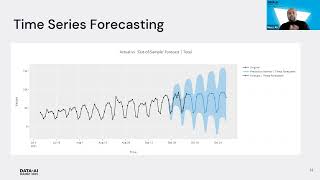
Time Series Forecasting with PyCaret
Explore automated time series forecasting with PyCaret's low-code module. Learn setup, EDA, training, and forecasting techniques to streamline your predictive modeling workflow.
Scaling XGBoost for Thousands of Features with Databricks
Scaling XGBoost for online advertising: Learn to handle thousands of features, optimize model training, and avoid common pitfalls in both Python and Scala implementations on Spark.

Discover the Data Lakehouse: Simplifying Data Architecture for Analytics and ML
Explore the data lakehouse architecture for managing massive data, supporting diverse analytics and ML requirements across multi-cloud environments, and enabling data teams to derive value efficiently.
Solving Business Problems with Data - Delivering Value Through Use Case Deconstruction
Explore strategies for aligning data teams with business goals, focusing on use case deconstruction and value delivery. Learn to bridge the gap between technical expertise and practical business impact.
Data Culture Outside Silicon Valley - Building Teams and Blocking Spam Calls
Exploring data culture beyond Silicon Valley, featuring First Orion's innovative approach to spam call blocking and insights on building effective data teams in Arkansas.
Using the Data Science Process - Lesson 5
Explore the data science process from project inception to completion, covering key steps for successful implementation in Databricks and Apache Spark projects.
Fit and Predict With Logistic Regression for Bird Bath Observations in Australia
Learn to model bird bath observations in Australia using tidymodels, combining model specifications with feature engineering recipes for effective fitting and prediction.
Use Tidymodels Workflowsets to Predict Human-Computer Interactions from Star Trek
Explore machine learning with tidymodels workflowsets to predict speaker type in Star Trek interactions, featuring data preprocessing, model evaluation, and result analysis.

Predict Housing Prices in Austin TX with Tidymodels and XGBoost
Explore feature engineering for boosted tree models using Austin housing data. Learn to incorporate text information as indicator variables and tune models for accurate price predictions.