LLaMA2 Tokenizer and Prompt Tricks
Explore LLaMA2 tokenizer tricks, prompt engineering techniques, and JSON conversion strategies to enhance your language model interactions and outputs.
Llama 2 in LangChain - First Open Source Conversational Agent
Explore Llama 2, the top open-source LLM, in LangChain. Learn to implement a 70B parameter chat model using Hugging Face and create a conversational agent with practical examples.
ChatGPT, Stable Diffusion, and the Future of Open Source AI
Explore the impact of generative AI on open source ethics, data usage, and individual rights, with insights from a leading AI scientist on the future of this technology.
LLaMA 2 and Meta AI Projects - Interview with Thomas Scialom
Insightful discussion with LLaMA 2 lead Thomas Scialom, covering his journey, Meta projects, and the future of AI. Explores key concepts like supervised fine-tuning and human preference in language models.
From OpenAI to Open Source AI: Navigating Between Commercial Ownership and Collaborative Openness
Explore the evolution of generative AI, examining the balance between commercial interests and open collaboration. Analyze openness levels, computing power dynamics, and diverse projects shaping AI's future.
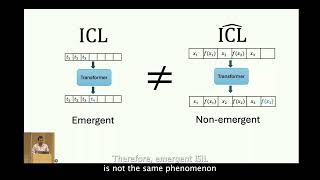
Do Pretrained Transformers Learn In-Context by Gradient Descent?
Explore the relationship between In-Context Learning and Gradient Descent in large language models, examining theoretical connections and empirical evidence from pre-trained transformers.
Local Llama 3.2 (3B) Tutorial - Summarization, Structured Text Extraction, and Data Labelling
Explore Llama 3.2 (3B) on Ollama for summarization, data extraction, and labeling. Learn setup, coding, and practical applications in this hands-on tutorial.
Deploying LLM Workloads on Kubernetes Using WasmEdge and Kuasar
Deploy LLM workloads efficiently on Kubernetes using WasmEdge and Kuasar. Explore solutions for faster container startup, reduced management overhead, and enhanced scalability in LLM operations.
Language Model Zen
Explore the frontier of AI Language Models, understanding their nature and various approaches to using them. Discover tools like TransformerLens and learn about options from prompt engineering to fine-tuning.
NVIDIA NIM: Deploying and Integrating Generative AI Models in Applications
Learn to deploy and integrate generative AI models using NVIDIA NIM. Explore vision and text models, create user interfaces, and implement image analysis and chat functionality in your applications.

Create Local No-Code AI Agents with N8N and Ollama - A Step-by-Step Tutorial
Learn to build local AI agents using n8n and Ollama - create calculator, news search, and blog writer agents with PostgreSQL integration and no-code workflows in just 10 minutes.
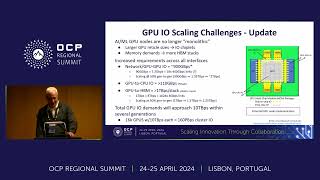
Optical Interconnects for Large-Scale AI Clusters - A Meta Perspective
Explore how optical interconnects and integrated optics solutions address IO challenges in large-scale AI clusters, focusing on Meta's GPU infrastructure and future hardware design requirements.
Machine Learning Software Ecosystems: Frameworks, Compilers, and Models - Part 1
Explore the landscape of ML frameworks, compilers, and models while understanding performance considerations for various hardware platforms and edge computing requirements.
RAG Integration with Nvidia NIM and LlamaIndex - Building Document Query Applications
Explore building a RAG application using LlamaIndex and Nvidia NIM to effectively query private documents with LLama 3.2 3B and Phi3 3.5 Small 128k models.
LLMs: Revolutionizing Customer Support or Ringing its Death Knell?
Explore the impact of LLMs on customer support, examining pros, cons, hybrid approaches, and stakeholder perspectives for a balanced view of this technological shift.
How Meta Technologies are Built with Llama Models
Explore Llama's potential for AI tools and discover how Meta leverages its 405B model for products like Meta AI, showcasing advanced reasoning capabilities.
Run Local LLMs on Hardware from $50 to $50,000 - Testing and Comparison
Explore local LLM performance across diverse hardware, from Raspberry Pi to high-end workstations. Compare Llama models on various systems and discover surprising results in AI accessibility.

Llama 3.2 - Multimodal and Edge Computing Advancements
Explore Llama 3.2's multimodal capabilities, edge computing potential, and performance benchmarks. Learn about its vision-tuned models, lightweight versions, and integration with Ollama.

Getting Started with Meta Llama 3.2 and Its Variants Using Groq and Hugging Face
Explore Meta Llama 3.2 variants using Groq and Huggingface. Learn to fine-tune, distill, and deploy this open-source AI model in various sizes for your projects.
Llama 101: Introduction to Meta's Large Language Model
Explore Meta's Llama language model, its capabilities, applications, and the community-driven approach to innovation and positive impact.
How Meta Technologies Are Built with Llama Models
Explore Llama's capabilities and learn how Meta leverages it to power AI products like Meta AI, featuring 405B parameters and advanced reasoning.