Flushing Away Preconceptions of Risk
Explore risk management in security, challenging misconceptions and revealing its value. Learn to interpret, measure, and leverage risk effectively for better organizational outcomes.
Discover How EclecticIQ Platform and MISP Go Together
Explore the synergy between EclecticIQ Platform and MISP for enhanced threat intelligence sharing, automated analysis, and streamlined incident response workflows.
Being a Cyberdefender - Behind the Curtains
Explore the realities of cyberdefense, including incident management, communication challenges, and maintaining work-life balance in this insightful talk by a seasoned professional.
Ensuring a Reliable Microsoft Teams User Experience - Modern Workplace Use Cases
Explore real-world examples of ensuring reliable Microsoft Teams experiences. Learn how IT can gain end-to-end visibility to detect and resolve issues, maintaining productivity in various industries.
Enterprise Incident Management - How to Get Everyone Ready for a Crisis
Discover strategies for building an enterprise cyber-response program, including war games and tabletop exercises. Learn key lessons for preparing leadership and teams for potential security crises.
Incident Insights from NASA, NTSB, and the CDC
Explore incident handling practices from NASA, NTSB, and CDC to improve software system recovery and prevent recurring failures in an increasingly automated world.
Availability, Latency, and Cost - Withstanding Regional Outages
Explore Netflix's multi-region strategy for improved availability and latency, including algebraic models, incident management, and design considerations for efficient failovers and user steering.
The Pandemic and The Classroom - Enabling Education for Millions
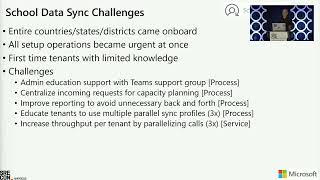
Explore how Microsoft Teams adapted to enable remote education for millions during COVID-19, discussing challenges, solutions, and engineering strategies for large-scale online learning.
What Breaks Our Systems - A Taxonomy of Black Swans
Explore categories of unforeseen, catastrophic system failures and strategies to fortify against them, including capacity testing, incident management, and communication.
The Good, the Bad and the Ugly - The 3 Learnings of an SRE
Explore core SRE principles, focusing on incident management, monitoring, and proactive approaches. Gain insights from a young engineer's journey transitioning from academia to industry.
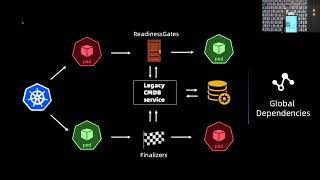
How to Not Destroy Your Production Kubernetes Clusters
Learn from real Kubernetes production incidents and best practices for maintaining high cluster availability, focusing on challenges with large-scale deployments and common operational pitfalls.
How to SRE When Everything's Already on Fire
Learn how Squarespace's team adopted SRE practices to transform their unreliable logging platform into a trusted system with 99.9% uptime, sharing valuable insights and strategies for improving service reliability.
My Life as a Solo SRE
Transforming engineering culture: One SRE's journey from chaos to improved reliability, featuring practical tips on implementing SLIs, reducing incident response times, and fostering organizational change.
A Tale of Two Postmortems - A Human Factors View
Explore the contrast between Safety I and Safety II approaches in incident reviews, using a fictional company's experience to demonstrate more effective postmortem practices for improved system reliability.
The Secret Lives of SREs - Controlling the Costs of Coordination across Remote Teams
Exploring hidden complexities in SRE incident response, revealing surprising findings on coordination strategies, tooling impacts, and adaptive choreography in managing service outages.
Learning More from Complex Systems
Explore complex systems' traits and learn better approaches to incident analysis beyond linear root-cause methods. Gain insights from history, science, and philosophy to enhance understanding of resilience in modern organizations.
Evolution of Incident Management at Slack
Explore Slack's evolution in incident management, covering strategies for handling numerous incidents, team-wide capability building, and future directions in maintaining platform reliability.
Move Fast and Learn Things - Principles of Cognition, Teaming, and Coordination
Explore cognitive and coordinative mechanisms for resilient software engineering, drawing from psychology and management theory to enhance SRE practices and organizational effectiveness.
A Post Incident Review Review
Explore ANZx's unique post-incident review process, focusing on safety science concepts and avoiding root cause analysis or action items tracking in a regulated industry environment.
Bugs in Collaboration - Learning from Incidents Edition
Discover how to identify and overcome collaboration challenges during critical incidents, turning crises into learning opportunities for improved system resilience and team performance.
Managing Incidents in Microservices
Explore incident response strategies for microservices architectures, focusing on distributed tracing, on-call practices, and adapting monitoring approaches to meet evolving needs in complex systems.