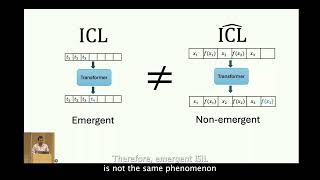
Do Pretrained Transformers Learn In-Context by Gradient Descent?
Explore the relationship between In-Context Learning and Gradient Descent in large language models, examining theoretical connections and empirical evidence from pre-trained transformers.
What You Always Wanted to Know About Deep Learning, but Were Afraid to Ask
Demystifying deep learning concepts like back-propagation, gradient descent, and neural networks. Practical guide to training a model for object recognition using TensorFlow and Keras.
Machine Learning - The Bare Math Behind Libraries
Demystifying machine learning by exploring the mathematical foundations of neural networks, gradient descent, and linear regression. Gain deeper insights to confidently select and optimize algorithms.
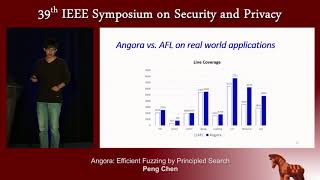
Angora - Efficient Fuzzing by Principled Search
Innovative fuzzing technique combining mutation-based speed with high-quality input generation, outperforming existing fuzzers in bug detection and branch coverage through advanced constraint-solving methods.
Hello Deep Learning
Explore deep learning from scratch, building an OCR solution for handwritten letters. Learn the fundamentals of machine learning and gain insights into the world of AI and neural networks.
Distributed Parametric Optimization with the Geneva Library
Explore Geneva, an open-source library for distributed optimization algorithms, leveraging Boost libraries to solve large-scale parametric problems on multi-core systems, clusters, and cloud environments.
Introduction to TensorFlow
Aprende los conceptos básicos de deep learning y TensorFlow, desde la instalación hasta la creación de redes neuronales, a través de ejemplos prácticos y visualizaciones amigables.
Differentiable Functional Programming
Explore differentiable functional programming, covering supervised learning, gradient descent, and automatic differentiation techniques for efficient deep learning implementations in Scala.
Differentiable Functional Programming
Explore differentiable functional programming, covering supervised learning, gradient descent, and deep learning concepts. Learn about tensor operations, algorithmic differentiation, and Scala's potential in next-gen deep learning systems.
Deep Learning with TensorFlow
Interactive TensorFlow session: build deep learning models from basics to advanced concepts. Hands-on approach to creating and using models in applications, suitable for beginners and experienced developers alike.
Writing a Neural Net from Scratch
Learn to build a neural network for image recognition from scratch in C#, covering key concepts like gradient descent and backpropagation without complex math or external libraries.
Deep Learning with TensorFlow
Explore TensorFlow's fundamentals and create deep learning models through interactive discussions. Gain practical skills to develop and implement AI in your applications.
Developer Accessible Machine Learning
Explore building and training a basic prediction model, understanding its workings, and incorporating cloud solutions into projects. No mathematical expertise required.
Writing a Neural Net from Scratch
Learn to code a neural network for image recognition in C# from scratch, covering gradient descent, activation functions, and backpropagation without complex math or external libraries.
What You Always Wanted to Know About Deep Learning, but Were Afraid to Ask
Demystifying Deep Learning: key concepts, practical applications, and hands-on training for object recognition. Gain a clear understanding of AI fundamentals and start your journey into machine learning.
A Friendly Introduction to Recurrent Neural Networks
Explore how computers predict and generate sequences using Recurrent Neural Networks. Learn about vectors, neural networks, and practical applications in cooking, weather, and more.
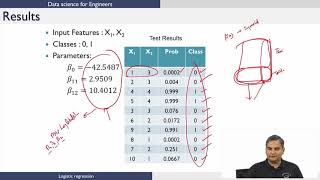
Logistic Regression - Continued
Explore advanced concepts and applications of logistic regression for enhanced predictive modeling and data analysis skills.
JAX vs PyTorch 2 - Converting Stateful to Stateless Operations in Neural Networks
Explore functional programming in JAX through hands-on comparison with PyTorch 2, focusing on neural network implementation and stateless operations for gradient descent.
Neural ODEs: Continuous-Time Models for Machine Learning - TMLS 2019
Explore neural networks as implicit models and their applications in scientific computing with David Duvenaud at TMLS2019.
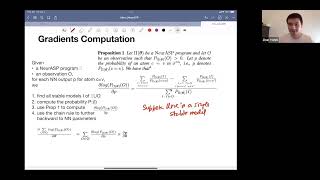
NeurASP: Model Training - Part 2
Explore NeurASP's end-to-end training process, connecting ASP programs to neural architectures for gradient flow. Learn model training techniques in this neuro-symbolic framework.
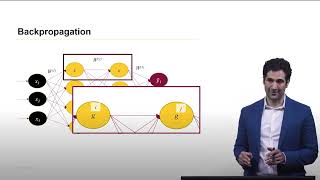
Backpropagation: Training Deep Neural Networks
Explore backpropagation, a crucial technique for training deep neural networks through gradient descent, with insights from ASU's Paulo Shakarian.