Learning Deep Matrix Factorizations Via Gradient Descent - Implicit Bias Towards Low Rank
Explores implicit bias in gradient descent algorithms for deep matrix factorizations, analyzing convergence to low-rank matrices and discussing implications for tensor decompositions.
Gradient Descent, Stochastic Gradient Descent, and Acceleration - Part 2
Explore advanced gradient-based optimization methods for large-scale machine learning, including stochastic gradient descent and accelerated versions, with convergence analysis and ODE connections.
Statistical Learning Theory and Neural Networks
Explore statistical learning theory for deep neural networks, covering uniform laws, Rademacher complexity, and optimization perspectives including gradient descent and neural tangent kernel regime.
Analyzing Optimization and Generalization in Deep Learning via Trajectories of Gradient Descent
Explore deep learning optimization and generalization through gradient descent trajectories, uncovering insights into neural network behavior and performance.
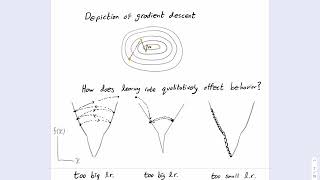
Gradient Descent and Stochastic Gradient Descent
Explore gradient descent and stochastic gradient descent in deep neural networks, covering convergence rates, learning rate effects, and challenges in optimization algorithms.
Statistical Learning Theory and Applications - Class 7
Explore statistical learning theory, covering least squares, gradient descent, regularization, and induction, with insights into historical context and practical applications.

MIT Introduction to Deep Learning
Comprehensive introduction to deep learning fundamentals, covering perceptrons, neural networks, loss functions, gradient descent, backpropagation, and regularization techniques.
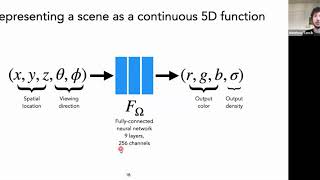
Neural Radiance Fields for View Synthesis
Explore neural radiance fields for view synthesis, combining coordinate-based neural representations with volumetric rendering to achieve state-of-the-art results in synthesizing novel views of complex scenes.
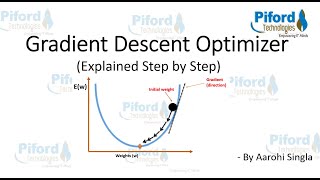
Explained Gradient Descent Optimizer
Comprehensive explanation of gradient descent optimization, covering mathematical foundations, weight updates, and backpropagation for machine learning and deep learning applications.
Optimization
Explore optimization techniques for machine learning, covering likelihood estimation, cost functions, gradient descent, and regularization methods for improved model performance.
Introduction to Optimization
Learn optimization techniques for machine learning, including likelihood estimation, gradient descent, and regularization, with practical examples and applications.
End-to-End Differentiable Proving - Tim Rocktäschel, University of Oxford
Innovative neural network approach for differentiable proving, combining symbolic reasoning with subsymbolic vector representations to infer facts and induce logical rules from incomplete knowledge bases.
Differentiable Programming for End-to-end Optimization of Experiments - Lecture 5
Explore differentiable programming for optimizing experiments in high-energy physics. Learn advanced techniques to enhance data analysis and improve experimental design in particle physics research.
Differentiable Programming for End-to-End Optimization of Experiments - Lecture 7
Explore differentiable programming for optimizing experiments in high-energy physics. Learn advanced techniques to enhance data analysis and improve experimental design in particle physics research.
NeurIPS 2023 Research Highlights - Poster Session 2
Explore cutting-edge AI research from NeurIPS 2023, covering topics like RNN training, image editing, language models, transformers, geo-localization, and hardware resilience in image classifiers.
Memory as a Lens to Understand Efficient Learning and Optimization
Exploring memory's role in optimization, discussing convergence rates of memory-limited algorithms vs. computationally expensive methods, and examining new problem structures to improve gradient descent variants.

MIT Introduction to Deep Learning - Foundations of Deep Learning - Lecture 1
Comprehensive introduction to deep learning fundamentals, covering perceptrons, neural networks, loss functions, gradient descent, backpropagation, and regularization techniques for effective model training.
Neural Networks For Your Dog
Learn to build neural networks from scratch in Python, covering perceptrons, gradient descent, and deep learning concepts through simple, engaging explanations and hands-on coding.

The Most Important Algorithm in Machine Learning - Backpropagation Explained
Explore backpropagation's fundamentals, from curve fitting to gradient descent, chain rule, and computational graphs. Gain insights into this crucial machine learning algorithm's principles and applications.
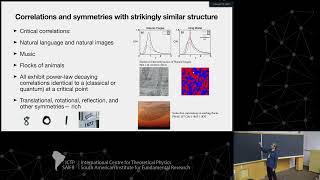
Machine Learning for Quantum Matter - Lecture 1
Explore machine learning applications in quantum matter, covering classical algorithms, high-dimensional data, supervised learning, neural networks, and practical examples in physics.
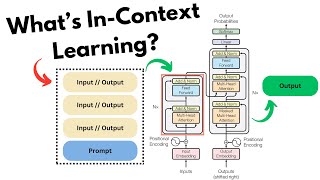
In-Context Learning in Deep Learning - How It Works in Large and Small Language Models
Explore in-context learning in LLMs: definition, significance, Bayesian framework, and implementation. Gain insights into this surprising capability of language models and its implications for AI.