
TensorFlow and Deep Reinforcement Learning, Without a PhD - Google I/O '18
Learn to implement deep reinforcement learning with TensorFlow, teaching a neural network to play Pong using only pixel data. No prior expertise required.

Introduction to Deep Learning
Comprehensive introduction to deep learning fundamentals, covering perceptrons, neural networks, loss functions, gradient descent, backpropagation, and regularization techniques.

How Convolutional Neural Networks Work, in Depth
Comprehensive exploration of convolutional neural networks, covering their structure, operation, and training process, including key concepts like filtering, pooling, and backpropagation.
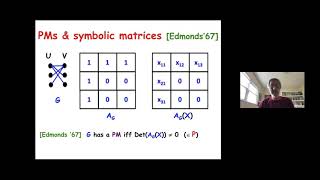
Geodesically Convex Optimization - Can We Prove P!=NP Using Gradient Descent - Avi Wigderson
Explore geodesically convex optimization and its potential to prove P≠NP using gradient descent in this advanced seminar by renowned mathematician Avi Wigderson.
Fixing GAN Optimization Through Competitive Gradient Descent - Anima Anandkumar
Explore competitive gradient descent for optimizing GANs, covering strategic equilibria, applications in ML, and numerical results. Gain insights into modeling competing agents and solving GANs.
A Practical Guide to Deep Learning - Richard Zemel
Explore deep learning fundamentals, from perceptrons to neural networks, with practical insights on object recognition, vision, and advanced techniques like regularization.
Machine Learning
從基礎到高級主題的全面機器學習課程,涵蓋回歸、分類、深度學習、無監督學習等,並包含實際演示和案例研究,幫助學習者掌握關鍵概念和技術。
PyTorch Tutorials 神经网络 教学
深入探讨PyTorch神经网络:从基础概念到高级应用,涵盖CNN、RNN、自编码器、强化学习和GAN,并讲解优化技巧如批标准化和过拟合处理。
모두를 위한 딥러닝 - PyTorch
PyTorch를 활용한 딥러닝 기초부터 고급 기술까지 실습 중심으로 학습. 텐서 조작, 선형 회귀, CNN, RNN 등 다양한 모델 구현 및 최적화 기법 습득.
Deep learning ด้วย tensorflow และ keras
เรียนรู้การสร้างโมเดล Deep Learning ด้วย TensorFlow และ Keras ตั้งแต่พื้นฐานจนถึงระดับสูง ครอบคลุมการติดตั้ง การใช้งาน และเทคนิคการปรับแต่งโมเดล
TensorFlow Tutorials 神经网络 教学 教程
从零开始学习TensorFlow构建神经网络,涵盖基础概念、CNN、RNN等高级主题,通过实例和可视化深入理解深度学习原理和应用。
Formation Tensorflow 2.0
Apprenez les fondamentaux de TensorFlow 2.0, des perceptrons aux réseaux de neurones récurrents, en passant par la normalisation des données et la création de modèles personnalisés.
Machine Learning and Neural Networks: Cost Function and Gradient Descent - Day 12
Explore cost functions and gradient descent in machine learning and neural networks, focusing on their role in optimizing model performance and accuracy.
Curiosities and Counterexamples in Smooth Convex Optimization
Explore counterexamples and curiosities in smooth convex optimization, focusing on key concepts and unique aspects of this mathematical field.
What Does It Take to Be a Good Fisherman?
Explore statistical challenges in learning from biased data, focusing on self-selection issues in various fields and discussing recent progress in econometric modeling and auction theory.
Min-Max Optimization - Part I
Explore min-max optimization, equilibrium computation, and adversarial gradient descent in zero-sum games, connecting classical techniques to deep learning applications.
Differentially Private Online-to-Batch Conversion for Stochastic Optimization
Explore differentially private stochastic optimization techniques, comparing simple preprocessing and custom algorithms. Learn about a novel online-to-batch conversion method for optimal private convergence rates.
Stable Adaptation and Learning in Nonlinear Systems and Neural Networks
Explore nonlinear systems tools for insights on collective computation and learning in large dynamical networks, focusing on stable adaptation and implicit sparse regularization.
Rodin: Density and Topology Optimization Framework - MFEM Workshop 2022
Explore Rodin, a C++17 framework for shape, density, and topology optimization. Learn its functionalities, from refining shapes to solving variational problems in scientific simulations.
I Built a Neural Network in Minecraft - Analog Redstone Network with Backprop and Optimizer (No Mods)
Explore the creation of an analog neural network in Minecraft using redstone, featuring backpropagation and weight updates. Learn about innovative applications of game mechanics in machine learning.
Yes, Generative Models Are The New Sparsity
Explore how generative models revolutionize data compression and signal processing, offering new perspectives on sparsity and optimization in machine learning.