Preventing Common Pitfalls in Production Streaming Jobs
Explore key strategies for optimizing streaming jobs in production, covering input parameters, stateful streaming, output configurations, and job modifications to ensure performance and fault tolerance.
Super Reliable Cloud Native Data Processing Using Apache Spark and Cloud Shuffle Manager
Enhance Apache Spark's reliability on Kubernetes with Cloud Shuffle Manager, enabling fault tolerance and cost savings through Spot Instances while maintaining performance for large-scale data processing.
Through the Looking Glass: Key Architectural Choices in Flink and Kafka Streams
Explore architectural differences between Apache Flink and Kafka Streams, gaining insights into stream processing fundamentals and design choices for improved system performance.
Solr Eclipse - Zomato's Journey to 64 Million Search Queries a Day
Explore Zomato's journey scaling Apache Solr to handle 64 million daily searches across 100 million restaurant items in 13 languages, powering their homepage and overcoming technical challenges.

Spark Unveiled: Essential Insights for All Developers
Discover Apache Spark's core concepts, architecture, and impact on data processing. Gain essential insights to enhance your development skills and unlock Spark's potential.

State Storage in Spark Structured Streaming
Learn to configure and manage state storage in Spark Structured Streaming for efficient data processing and analysis.

Unlocking the Power of Apache Flink - An Introduction in 4 Acts
Explore Apache Flink's core principles for real-time data processing, including shared-nothing architecture, event-time processing, and state snapshots, through practical examples and demos.
Пирамида Потребностей Multitenant-системы: От Инженерных к Бизнес-решениям
Discover how YTsaurus evolved its big data platform automation, from basic infrastructure needs to advanced user-centric features, managing 20K+ hosts and 4.5K daily active users at Yandex.
On Scrambling Times of Quantum Systems, Including Black Holes
Explore quantum system scrambling times, including black holes, with insights from Peter Shor of MIT. Delve into near-term quantum computing challenges and advancements.
Optimize LLM Workflows with Smart Infrastructure Enhanced by Volcano
Insights on managing large-scale LLM platforms using Kubernetes and Volcano, addressing challenges in training efficiency, fault tolerance, resource optimization, and topology-aware scheduling for GPU workloads.
Above the Clouds - Introducing Akka
Explore Akka's unified runtime for scalable, fault-tolerant systems using Actors and STM. Learn to solve complex scalability issues and implement a high-performance compute grid.
Demystifying Stream Processing with Apache Kafka
Demystifying stream processing with Apache Kafka, exploring key features, benefits, and challenges. Introduces Kafka Streams library, highlighting its unique design decisions and tradeoffs in the stream processing landscape.
Cloud Native Live - Building Stability
Explore strategies for enhancing stability in cloud-native environments, focusing on resilience, scalability, and best practices for robust system architecture.
Microservices Madness - Application and Infrastructure Automation Using Temporal
Explore fault-tolerant microservices architecture and infrastructure automation using Temporal. Learn to build self-deploying, auto-scaling, resilient applications that simplify distributed system challenges.
Technical Overview of FoundationDB - Internal Operations and Scalability
Explore FoundationDB's internals, focusing on external consistency and scalability in distributed databases. Learn about stateful components, API, reads, commits, and failure handling.

Disaster Recovery with Distributed Databases - Implementing Asynchronous Replication
Explore disaster recovery strategies for distributed databases using asynchronous replication, Kafka, and Apache Mesos. Learn implementation techniques and best practices for fault tolerance and scalability.
Building MongoDB Replica Set for Fault-Tolerant Task Management with Mesos
Learn to create fault-tolerant MongoDB Replica Sets using Mesos frameworks, ensuring robust task management in unreliable network environments and system failures.
Sōzu: A Hot Reconfigurable Reverse HTTP Proxy in Rust
Explore Sōzu, a Rust-based HTTP reverse proxy designed for continuous operation, handling high traffic loads, and dynamic reconfiguration without downtime. Learn its architecture and tooling.
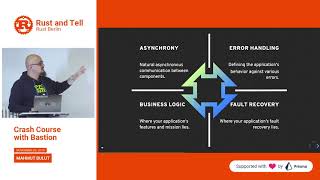
Crash Course on Asynchronous Execution and Fault Tolerance with Bastion
Explore asynchronous execution, fault-tolerance, and error handling in Rust with Bastion runtime, offering innovative solutions to modern system challenges.
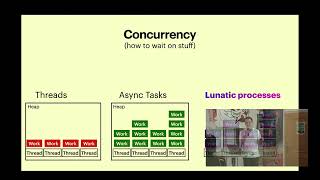
Lunatic - Erlang-Inspired Runtime for WebAssembly
Explore Lunatic: an Erlang-inspired WebAssembly runtime. Learn about its features, architecture, and potential applications in modern software development.
Dapr, Workflows, and the Road Ahead
Explore Dapr's latest features for cloud-native apps, including long-running stateful services, multi-cluster capabilities, and durable workflows for orchestrating microservices and business applications.