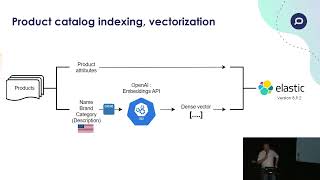
Vector (Hybrid) Search Live A/B Test Results in E-commerce Sector
Explore significant A/B test results of Vector (Hybrid) Search in e-commerce, revealing revenue increases and improved user engagement. Learn about embedding creation and result blending techniques.
Chat With Your Data - A Practical Guide to Production RAG Apps
Learn to build production-ready RAG applications with insights from Moody's rapid development. Gain strategies for embedding, relevance measurement, cost management, and team organization for impactful AI-driven data interaction.
Building RAG Systems with Mixed Numeric and Text Data - Workshop
Learn to build high-performing RAG systems by combining numeric and text data embeddings. Explore efficient retrieval techniques for LLMs and improve chatbot performance using an HR policy example.
SliceGPT Explained - Compressing Large Language Models
Explore SliceGPT's innovative approach to compressing large language models by deleting rows and columns, maintaining high performance while reducing parameters significantly.
ROBOSHOT: Improving Foundation Model Performance Without Fine-Tuning
Boost zero-shot foundation model performance with ROBOSHOT. Learn to improve robustness, reduce biases, and understand conditions for enhanced results without fine-tuning.
Optimizing RAG Implementations for Specialized Enterprise Tasks
Optimize RAG implementations for enterprise tasks. Learn to fine-tune components, apply AI data development techniques, and accelerate production delivery for increased accuracy and precision.
Unlocking Innovative Generative AI Use Cases with Text and Multimodal Embeddings
Explore innovative generative AI applications using text and multimodal embeddings, focusing on semantic search, recommender systems, and content classification.
Building Differentiated Generative AI Applications on Google Cloud
Explore building Generative AI apps on Google Cloud using Vertex AI's models, embeddings APIs, and vector databases. Learn to create enterprise-grade conversational AI and search experiences.
Spring AI: Integrating AI into Enterprise Applications with Java
Explore Spring AI's seamless integration of AI into enterprise Java applications. Learn key concepts, create effective prompts, and implement features like embeddings, RAG, and semantic search.
Embeddings and Retrieval for LLMs: Techniques and Challenges
Explore embedding-based retrieval for AI apps, including key limitations and mitigation techniques. Learn about Chroma, an open-source embedding database for LLM applications.
Building RAG-based LLM Applications for Production - LLMs III Talk
Develop and deploy scalable RAG-based LLM applications. Learn to handle data loading, preprocessing, embedding, and serving on clusters. Explore Anyscale Endpoints for cost-effective open-source model serving.
RAG Has Been Oversimplified - Exploring Complexities in Retrieval Augmented Generation
Explore the complexities of Retrieval Augmented Generation (RAG) beyond its oversimplified portrayal. Gain insights into practical challenges and nuanced considerations for developers working with RAG systems.
Seeing Like a Language Model - Understanding Embeddings and Meaning in AI
Explore how language models process text and represent meaning through embeddings. Gain insights into building better retrieval-augmented LLM systems and designing natural interfaces for reading and writing.
RecSys at Spotify - Building and Evaluating Large-Scale Recommender Systems
Explore Spotify's large-scale recommender systems, foundational embeddings for transfer learning, evaluation methods, and MLOps challenges with Senior ML Engineer Sanket Gupta.
From Robotics to Recommender Systems - MLOps Podcast #240
Explore robotics, computer vision, and recommender systems with Miguel Fierro. Gain insights on ML applications, sports analytics, and AI integration in various fields from a Microsoft Principal Data Science Manager.
Visualize - Bringing Structure to Unstructured Data - MLOps Podcast #258
Explore techniques for structuring and visualizing unstructured data in machine learning, from classification to Retrieval-Augmented Generation, using tools like UMAP and Renumics Spotlight to uncover patterns and evaluate model performance.
Document Similarity: Langchain Sentence Transformers and Chroma
Explore document similarity using Langchain, HuggingFace Transformers, and Chromadb. Learn to create embeddings and implement vector storage for efficient text analysis and classification.
Installing and Using Ollama Framework for Data Science and Machine Learning
Explore Ollama framework installation, usage, and Python integration for generating, embedding, and chatting with AI models.
Neo4J as Vector Store with Langchain, OpenAI, and Wikipedia
Explore Neo4J as a vector store using Langchain, OpenAI embeddings, and Wikipedia data for advanced data science and machine learning applications.
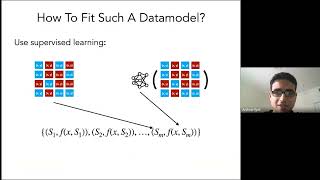
Mapping from Training Data to Predictions with Datamodels - Differential Privacy in Machine Learning
Explore datamodels in machine learning, from training data to predictions. Learn about model brittleness, data counterfactuals, and applications in ML pipelines.
Live Coding a Quick and Easy Semantic Search with Qdrant from Scratch - Rust Implementation
Build a simple semantic search using Qdrant's Rust API in a live coding session. Learn implementation techniques and enjoy Rust-related humor along the way.