Document Similarity: Langchain, Ollama Mistral 7B, and Chroma for Machine Learning and Data Science
Explore document similarity using Langchain, Ollama with Mistral 7B or LLama 2, and Chromadb as VectorStore for machine learning and data science applications.
Embeddings vs Fine-Tuning - Part 3: Unsupervised Fine-Tuning
Explore unsupervised fine-tuning techniques for embeddings, including dataset cleanup, Google Colab implementation, and expert tips for optimal results.
Developing and Serving RAG-Based LLM Applications in Production
Learn to develop, evaluate, and scale RAG-based LLM applications for production, including advanced topics like hybrid routing to bridge the gap between open-source and closed LLMs.
Developing Local AI Copilots with LangChain, NVIDIA NIM, and FAISS - LLM App Development
Learn to build a local AI copilot using LangChain, NVIDIA NIM, and FAISS. Covers document processing, vector storage, inference with Llama 3, and LangChain orchestration for responsive LLM applications.
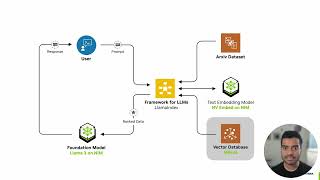
Building LLM Assistants with LlamaIndex, NVIDIA NIM, and Milvus - LLM App Development
Learn to create a Q&A chatbot using NVIDIA NIM for embeddings, Milvus for storage, Llama3 for inference, and LlamaIndex for seamless integration in this comprehensive tutorial.
RAG from Scratch with Llama 3.1 - Building a Custom Data Chatbot
Hands-on tutorial for building a RAG system from scratch using Llama 3.1, Groq API, Sqlite-vec, and FastEmbed. Learn to create a chatbot with custom data without external libraries.
Vector Search Over Complex Semi-Structured Data
Explore production-grade vector search systems combining unstructured and structured data, with focus on user objectives and feedback loops for improved results in various applications.
TxtAI - Simplifying RAG and Semantic Search with an All-in-One Embeddings Database
Explore TxtAI: all-in-one solution for semantic search, LLM orchestration, and language model workflows. Learn embeddings, indexing, and advanced text processing techniques.
Creating an AI Research Assistant Using Ollama RAG - Cost-Free Implementation
Create a free AI research assistant using Ollama AI to streamline article searches, generate insights, and build a user-friendly interface for efficient literature review and analysis.

RAG from the Ground Up with Python and Ollama - Building a Document Interaction System
Build a RAG system with Python and Ollama: parse documents, create embeddings, implement relevance scoring, and enable LLM interaction with your own datasets.

Privacy-Friendly Applications with Ollama, Vector Functions, and LangChainJS
Explore building privacy-focused AI applications using Ollama for local LLMs, vector functions for efficient searches, and LangChainJS for versatile agents, ensuring data stays on your device.
Vector Databases 101 - How Do They Work?
Explore vector databases' functionality, applications, and architecture. Learn about similarity search, indexing techniques, and real-world use cases in machine learning and AI.

The Narrated Transformer Language Model
Visual introduction to the Transformer architecture, explaining its components and applications in AI/ML. Accessible to various experience levels, covering tokenization, embedding, and output projection.
Retrieval, Search and Knowledge in the Age of LLMs and Vector Databases
Explore vector embeddings' impact on information compression, search, and knowledge retrieval. Learn how enterprises can leverage this technology to enhance customer understanding and interaction.
Embeddings - What They Are and Why They Matter
Discover how embeddings work in machine learning, from basic concepts to practical applications in semantic search and content relationships, with hands-on examples and implementation techniques.
Troubleshooting Unstructured Data with Embeddings
Explore embedding techniques for troubleshooting unstructured data models, gaining insights into internal representations and improving ML workflows.
Making RAG Work - Building Robust Retrieval Augmented Generation Systems
Dive into practical techniques for implementing robust RAG systems, exploring common pitfalls, optimization strategies, and design principles for production-ready LLM applications.
Optimizing RAG Systems for Business Applications
Master the implementation of RAG systems in enterprise settings, from dynamic chunking to custom embedding models, while learning optimization techniques for enhanced AI response accuracy and relevance.
Data Preparation for RAG Applications Using Qdrant and FastEmbed
Master data preparation techniques for RAG applications using Qdrant and FastEmbed, covering chunking methods, embedding generation, indexing strategies, and efficient data loading processes.
Vector Storage for Large Scale Multimodal RAG
Explore advanced vector storage techniques for implementing large-scale multimodal retrieval-augmented generation systems and their practical applications.
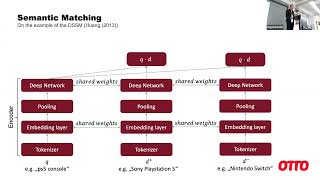
Unbiased Neural Ranking Model for Product Search
Explore an unbiased neural ranking model for product search, leveraging implicit customer feedback and addressing position bias to improve e-commerce search results.