Spark SQL Shuffle Join Optimization at eBay
Optimize Spark SQL shuffle join performance with advanced techniques like unwrapping join conditions, enhancing shuffle exchange reuse, and pushing down partial aggregations.

Snowflake Data Warehouse Internals - Lecture 21
Explore Snowflake's data warehouse architecture, design principles, and internal mechanisms for efficient cloud-based data management and analytics.
Accelerating Apache Spark Workloads with Apache DataFusion Comet
Explore Apache DataFusion Comet's potential to enhance Apache Spark performance, optimizing data processing workflows and improving efficiency in large-scale analytics.
Apache Arrow DataFusion - A Fast, Embeddable, Modular Analytic Query Engine
Explore Apache Arrow DataFusion's fast, embeddable, and modular analytic query engine capabilities with insights from expert Andrew Lamb.
Yellowbrick Data Warehouse System - Lecture 21
Explore Yellowbrick's innovative data warehouse system, its architecture, and performance optimizations for analytical workloads in this advanced database systems lecture.
Snowflake Data Warehouse Internals - Lecture 19
Explore Snowflake's data warehouse architecture, design principles, and internal workings. Gain insights into its innovative approach to cloud-based data management and analytics.

ETL Observability: Azure to Snowflake - Monitoring with Splunk and Power BI
Explore ETL monitoring from Azure to Snowflake using ADF, Splunk, and Power BI. Learn data lineage and observability techniques for efficient pipeline management.

Understanding the SQL Aspects of Spark - Spark SQL
Explore Spark SQL's capabilities for distributed processing of structured data, integrating relational operations with Spark's high-performance engine.

Introduction to Data Build Tool (DBT)
Master data build tool (DBT) for efficient data product development, including CICD, pipelines, validation, quality testing, deployment, and monitoring.
Real-Time Data Integration Practice Based on Flink CDC at Alibaba Cloud
Explore real-time data integration using Flink CDC, covering core design, key implementations, and Alibaba Cloud's solutions for data lake and warehouse integration scenarios.
Cloud Agnostic Data Platform with DBT, Trino, Iceberg and MinIO
Explore a hands-on, cloud-agnostic data pipeline using TrinoDB, DBT, MinIO, and Apache Iceberg for scalable and lightweight analytics, suitable for both cloud and on-premise solutions.
DBT and Python - How to Write Reusable and Testable Pipelines
Develop reusable and testable data pipelines using DBT and Python. Learn best practices for version control, DAGs, and unit testing in SQL and Python-based models.

chDB - The Blazing Fast SQL Engine for Data Science
Explore chDB, a high-performance SQL engine for Python data ecosystem. Leverage its extensive data source support, ANSI SQL compliance, and seamless integration with popular libraries for efficient data analysis.
Building Data Applications on Databricks in 20 Minutes
Learn to create data apps for non-technical users, enabling data-driven decisions. Explore rapid app development using Python frameworks, data access methods, security, governance, and production deployment on Databricks.
Getting Started with Databricks Clean Rooms
Explore privacy-safe data collaboration using Databricks Clean Rooms. Learn to analyze shared data, train ML models, enforce privacy policies, and enable advanced use cases across platforms.
Data Warehousing Performance, Scale and Security with Databricks SQL
Explore high-performance data warehousing with Databricks SQL, focusing on scalability, security, and resource management for enterprise environments. Learn about latest advancements in scheduling and caching.
Maximizing Productivity with Databricks Assistant - Key Strategies and Tips
Discover how Databricks Assistant enhances productivity through AI-powered code creation, optimization, and troubleshooting. Learn to leverage natural language for SQL, Python, and data visualization while ensuring privacy and security.
Unity Catalog Managed Tables - Powerful, Easy, Interoperable
Discover Unity Catalog's Managed Tables: lightning-fast performance, hands-free management, and complete interoperability for efficient data handling and analysis in the Databricks ecosystem.
Is Flink SQL a Database? Understanding Apache Flink SQL
Explore Apache Flink SQL's unique approach to stream processing, adapting database concepts like queries and materialized views for real-time data analysis and processing.
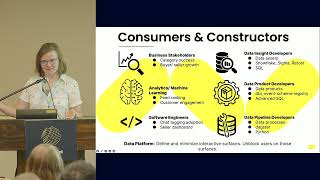
Extreme Self-Service: Turning Data Consumers into Data Constructors
Empower data consumers to create their own products with minimal training. Learn best practices, community building, SQL literacy promotion, and guard rail establishment for self-service analytics.
The Metadata-Driven Data Warehouse
Streamline data warehouse development using metadata-driven approaches. Learn efficient techniques for Insert/Update/Delete operations and pipeline management.