Automated Metadata Management in Data Lakes - A CI/CD Driven Approach
Discover a CI/CD-driven approach to automated metadata management in data lakes, focusing on balancing development speed, governance, and schema evolution for rapidly growing organizations.
Advanced SQL for Data Scientists
Master essential SQL skills for data science: statistics, data prep, advanced filtering, window functions, and analytics tool integration.
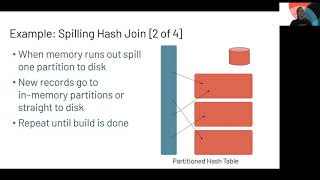
Photon: Accelerating SQL Queries on Databricks Lakehouse Platform
Explore Photon, a C++ component for efficient query execution in Databricks Lakehouse. Learn about its vectorized processing, compatibility with Apache Spark, and performance enhancements for data-driven decision-making.
Why Lakehouse Architecture Now - Exploring Enterprise Data Warehouse Failures and the Need for Lakehouse Paradigm
Explore the shift from enterprise data warehouses to lakehouse architecture, focusing on benefits, challenges, and Starburst's role in powering SQL-based analytics on Delta Lake.
Accelerating MLOps with Apache Spark and SingleStore
Learn to accelerate MLOps using Apache Spark and SingleStore. Discover how to build fast analytical applications, manage supervised learning models, and scale AI/ML operations for data science success.
DBT Using Databricks and Delta
Learn to leverage Data Build Tool (DBT) with Databricks and Delta for efficient data lake management, including SQL-first approach, upsert capabilities, and Azure integration for enhanced observability.
Fugue: Unifying Big Data Analytics Ecosystems for ETL and Machine Learning
Unifying big data ecosystems with Fugue: SQL-like framework for ETL and ML pipelines, compatible with Spark, TensorFlow, and more. Simplifies development, improves performance, and enhances maintainability.
Presto on Apache Spark - A Tale of Two Computation Engines
Explore the integration of Presto and Spark, combining low-latency evaluation with robust execution for enhanced SQL experience in both interactive and batch use cases at Facebook scale.
Learn to Use Databricks for Data Science
Discover how Databricks simplifies data science with a unified platform for analytics workloads, from data preparation to predictive analytics, enhancing collaboration and productivity at scale.
Deep Dive into New Features of Apache Spark 3.1
Explore Apache Spark 3.1's new features: ANSI SQL compliance, streaming enhancements, Python improvements, and performance optimizations for faster, easier, and smarter data processing.
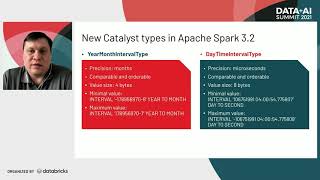
Comprehensive View on Intervals in Apache Spark 3.2
Explore Apache Spark 3.2's interval enhancements, including ANSI SQL conformance, new interval types, and improved APIs. Learn to construct, use, and manage intervals effectively in Spark SQL and PySpark.
Large Scale Geospatial Indexing and Analysis on Apache Spark
Explore large-scale geospatial indexing and analysis using Apache Spark, covering challenges, frameworks, data structures, and practical applications in cloud-first architecture with Databricks.
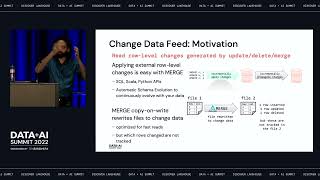
Delta Lake 2.0 Overview - New Features and Community Collaborations
Overview of Delta Lake 2.0 features, integrations, and community collaboration. Highlights include data skipping, Change Data Feed, column mapping, multi-cluster S3 writes, and support for various languages and platforms.
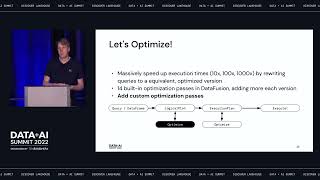
DataFusion and Apache Arrow: Supercharging Data Analytics with a Rust-Based Query Engine
Explore Rust, Apache Arrow, and DataFusion to accelerate modern data stacks. Learn implementation timelines, optimization techniques, and key features for efficient data analysis and querying.
Master Databricks and Apache Spark - SparkR Usage - Lesson 35
Explore SparkR for integrating R with Databricks and Apache Spark, covering architecture, APIs, libraries, and practical examples of data manipulation and analysis.
Using SQL Views in Databricks and Apache Spark - Lesson 12
Learn to create and utilize SQL views in Databricks for efficient data analysis and pipeline reuse. Explore common table expressions, aggregations, and case statements for advanced querying techniques.
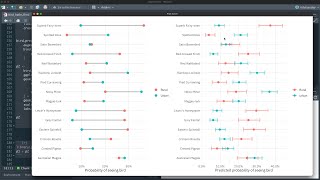
Fit and Predict With Logistic Regression for Bird Bath Observations in Australia
Learn to model bird bath observations in Australia using tidymodels, combining model specifications with feature engineering recipes for effective fitting and prediction.
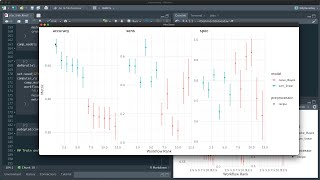
Use Tidymodels Workflowsets to Predict Human-Computer Interactions from Star Trek
Explore machine learning with tidymodels workflowsets to predict speaker type in Star Trek interactions, featuring data preprocessing, model evaluation, and result analysis.

Predict Housing Prices in Austin TX with Tidymodels and XGBoost
Explore feature engineering for boosted tree models using Austin housing data. Learn to incorporate text information as indicator variables and tune models for accurate price predictions.
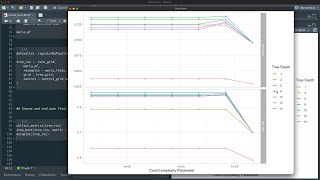
Partial Dependence Plots for Mario Kart World Records
Explore decision tree modeling and partial dependence profiles for Mario Kart world records using tidymodels and DALEX, with a focus on predicting shortcut usage.
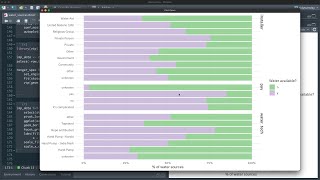
Predict Water Availability in Sierra Leone With Random Forests
Explore random forest modeling with tidymodels to analyze water sources in Sierra Leone, covering data preparation, model building, and evaluation techniques.