OpenAI Embeddings with Voice Cloning - Eleven Labs API, ChatGPT API, Whisper API
Learn to build a voice assistant using OpenAI Embeddings, ChatGPT, Whisper, and Eleven Labs APIs. Combine AI technologies for realistic voice responses and create a custom Q&A system with a Gradio UI.

Building a Machine Learning Drowsiness Detector App with Sound Alerts
Build a ML drowsiness detector app with PyTorch YOLOv5 and Tkinter. Detect awake/drowsy states, play alerts for sleeping, and learn object detection implementation in a practical application.

Building an AI Rap God - Cloning a Rapper Using Machine Learning
Learn to create an AI-powered rap generator using Python, combining text generation, voice cloning, and lip-syncing technologies to produce custom rap performances.
Attempting to Clone My Voice Using ML
Explore voice cloning with machine learning using CorentinJ's package. Setup, test, and develop on your PC using Python in this hands-on coding livestream.
Can We Clone My Voice Using ML?
Explore voice cloning with machine learning using CorentinJ's package. Setup, test, and develop on your PC using Python in this hands-on live stream.
Sound Programming on the X68000 with ChibiSound Pro - Lesson P43
Explore sound programming on the x68000 using ChibiSound Pro. Learn hardware abstraction, testing, music coding, and sound creation techniques for this classic computer system.
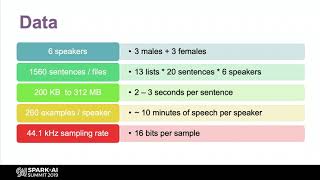
Listening at the Cocktail Party - Deep Neural Networks for Speech Separation
Explore deep neural networks for speech separation, focusing on data preparation, network architectures, and real-time implementation on embedded devices for smart audio applications.

Industry Shocking Text-To-Music AI Model by Facebook Audiocraft - Full Tutorial - Better Than MusicLM
Learn to use Facebook's Audiocraft AI model for text-to-music generation. Install, run, and experiment with this powerful tool on your computer or Google Colab to create amazing AI-generated music.
Multi-Way Analysis - The Algorithm
Explore the alternating least squares algorithm for multi-way analysis, focusing on PARAFAC modeling in chemometrics. Learn about notation, potential problems, and alternative approaches.

Understanding Audio Data for Deep Learning
Explore fundamental audio processing concepts for deep learning, including waveforms, pitch, Fourier transform, and MFCCs, essential for AI applications in sound analysis.
Inversion of 2D Remote Sensing Data to 3D Volumetric Models Using Deep Dimensionality Exchange
Innovative deep learning approach for inverting 2D remote sensing data to 3D models, reducing computation time from months to milliseconds. Explores unique embedding strategies and model architectures for efficient volumetric space reconstruction.
Audio Processing in Keras with Kapre
Learn to process audio in Keras using Kapre, exploring its advantages, features, and implementation. Discover how to embed audio transformations within deep learning models for optimized GPU-based calculations and easier deployment.
Generating Sound Digits with a Variational Autoencoder
Learn to generate audio spectrograms of sound digits using a trained Variational Autoencoder, then convert them into audio. Includes implementation, scripting, debugging, and result evaluation.
OpenAI Whisper - Translate and Transcribe Your Video and Audio at Command Line
Comprehensive walkthrough of OpenAI Whisper for multilingual speech recognition, translation, and transcription using command-line interface, with practical demonstrations across various audio formats.
tinyML Trailblazers: Success Stories with Mouna Elkhatib
Explore tinyML success with Mouna Elkhatib, AONDevices CEO. Learn about voice processing innovations, entrepreneurial challenges, and future trends in edge AI and IoT technologies.
Dissecting a Low Power AI/ML Edge Application - Noise Suppression
Explore noise suppression in AI/ML edge applications, focusing on energy-efficient implementation for battery-powered devices and software frameworks for optimal user experience.
How to Train and Deploy TinyML Models for Three Common Sensor Types
Learn to train and deploy tinyML models for sensor, audio, and vision data using Edge Impulse. Explore workflows, best practices, and optimization techniques for embedded machine learning applications.
Ultra-Low-Power Command Recognition for Ubiquitous Devices
Explore ultra-low-power command recognition for ubiquitous devices, covering noise challenges, system goals, core functions, training, and implementation on tiny hardware.
24 Key AI Updates and News in 26 Minutes
Comprehensive overview of recent AI advancements, including updates from major tech companies, new AI models, and emerging technologies in voice, vision, and language processing.
Dynamic vCPU Priority Boosting in KVM for Latency-Sensitive Workloads
Exploring a framework for host-guest communication in KVM to minimize VM latencies by dynamically boosting vCPU thread priorities based on guest scheduling needs and host insights.
The Digital Hearth: An Automated Group Speech-to-Text System for Community Conversations
Explore an innovative group conversation recording device designed to capture and analyze community discussions, featuring offline operation and advanced speech recognition capabilities.