Diving into Delta Lake: How DELETE, UPDATE, and MERGE Work - Part 3
Explore Delta Lake's internals: DELETE, UPDATE, and MERGE operations, transaction log mechanics, and performance optimization techniques for efficient data management.
How to Build a Cloud Data Platform - Part 1: Architecture
Learn to build a unified cloud data platform using Delta Lake, combining data warehouses and lakes for improved reliability, performance, and operations.
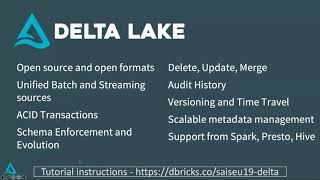
Building Data Intensive Analytic Applications on Top of Delta Lakes
Explore Delta Lake's ACID transactions for Apache Spark, enhancing data reliability and query performance. Learn to address challenges in modern data engineering through hands-on examples and practical applications.

The Parquet Format and Performance Optimization Opportunities
Explore Parquet format intricacies, columnar storage basics, and optimization techniques for Spark workloads. Learn about encoding, compression, predicate pushdown, and Delta Lake to enhance analytical performance.
Simplify and Scale Data Engineering Pipelines with Delta Lake
Learn to build scalable data engineering pipelines using Delta Lake's multi-hop architecture. Discover how to progress from raw data ingestion to machine learning-ready datasets efficiently and effectively.
Introduction to Databricks Lakehouse Platform Architecture and Security
Explore Databricks Lakehouse Platform's architecture, focusing on data reliability, Delta Lake features, and Photon's performance enhancements for efficient data management and analytics.
Implementing End-to-End Demand Forecasting with Databricks and MLflow
Discover how to implement a scalable demand forecasting solution using Databricks and MLflow, improving retail efficiency and reducing food waste through accurate production and delivery planning.
Best Practices for Building Robust Data Platforms with Apache Spark and Delta
Learn best practices for building robust data platforms using Apache Spark and Delta. Gain insights on optimizing performance, scaling, security, and cost-effectiveness in big data architectures from real-world experiences.
Patterns and Operational Insights for Large-Scale Delta Lake Workloads
Explore effective Delta Lake patterns, optimization techniques, and operational insights for managing large-scale data workloads on Databricks, including streaming ETL, data enrichment, and analytics.
Delta Lake 0.7.0 and Spark 3.0 - Ask Me Anything Session
Illuminating AMA session with Apache Spark and Delta Lake experts. Explore Spark 3.0 and Delta Lake's latest features, use cases, and development insights. Perfect for data engineers seeking cutting-edge knowledge.
Healthcare Claim Reimbursement Using Apache Spark - Optum's System Transformation
Optimizing healthcare claim processing with Apache Spark: Improved performance, reduced costs, and enhanced capabilities for hospitals' revenue recovery through efficient data processing and analysis.
Building a Real-Time Feature Store for Machine Learning at iFood
Discover how iFood built a real-time feature store using Databricks and Spark Structured Streaming to process event streams, store data, and develop reliable code for efficient machine learning model predictions.
Real-Time Forecasting at Scale Using Delta Lake and Delta Caching
Explore real-time forecasting at scale using Delta Lake and Delta Caching. Learn efficient data sampling, storage, and caching techniques for handling massive datasets and achieving rapid forecast response times.
Building a Streaming Microservice Architecture with Apache Spark Structured Streaming
Explore building a scalable, fault-tolerant streaming microservice architecture using Apache Spark, Kafka, gRPC, and Delta Lake for real-time data processing and reliable insights.
Building the Petcare Data Platform with Delta Lake and Spark ETL Pipeline
Explore Mars Petcare's data platform using Delta Lake and Spark ETL pipeline 'Kyte'. Learn about advantages over Azure Data Factory and leveraging Delta Lake for ETL configurations and data science.
Getting Started with Delta Lake
Learn to create a Lakehouse architecture with Delta Lake, an open-source storage framework. Explore data reliability challenges, hands-on examples, and benefits for big data use cases in modern data engineering.
The Pace of Innovation in Delta Lake
Explore the rapid advancements and innovative features of Delta Lake, enhancing data reliability and performance in modern data architectures.
Delta Lake - Diving into Data Lakes Without the Downsides
Explore Delta Lake's innovative approach to data management, offering enhanced reliability and performance for large-scale analytics without traditional data lake drawbacks.

Delta Format and Live Tables - Pioneering Data Innovation
Explore Delta format and Live tables, understanding their role in scalable big data pipelines and modern data engineering innovations.

Data Engineering with Databricks - Leveraging the Lakehouse Platform for ETL Pipelines
Leverage Databricks Lakehouse Platform to build ETL pipelines, use Delta Live Tables, and orchestrate tasks with Workflows for efficient data processing.
Streamline Real-Time Ingestion and Serving with DLT and Online Tables
Västtrafik improves public transport efficiency using near real-time data ingestion for its Travel Planner App. Learn how Delta Live Tables and Brickstore optimize low-latency pipelines, balancing cost and performance.