Symbiosis: The Art of Application and Kernel Cache Cooperation - FAST '24
Explore Symbiosis, a framework optimizing key-value storage systems by dynamically configuring cache sizes. Learn how it improves performance across various workloads and environments.
In-Memory Key-Value Store Live Migration with NetMigrate
NetMigrate: A novel approach for live migration of in-memory key-value stores using programmable network data planes, improving query throughput and maintaining low latency during migration.

37% Better Output with 15 Lines of Code - Llama 3 Improved RAG
Improve RAG performance for Llama 3 models with simple code modifications, enhancing output quality by 37% for both local 8B and cloud-based 70B versions.

Complete Langchain Course for Generative AI
Comprehensive guide to building AI applications with LangChain, covering chatbots, RAG pipelines, and integration with various tools and platforms for generative AI development.
Taylor Swift and the Democratization of AI for Developers - React Miami 2024
Explore how AI tools like OpenAI and Vercel's AI SDK enable developers to create smart experiences, illustrated through the development of SwiftieGPT, a Taylor Swift-focused chatbot.
LangChain Multi-Query Retriever for RAG - Advanced Technique for Broader Vector Space Search
Learn advanced RAG techniques using LangChain's Multi-Query Retriever. Explore how to broaden search results, customize queries, and integrate this method into larger RAG pipelines for improved AI applications.
Multi-Tenancy Architecture Lessons Learned
Explore multi-tenancy architecture approaches, their pros and cons, and how to handle unique configurations. Learn about hidden costs, long-term impacts, and recent advancements in tooling for better support.
Building Smart Farms with Edge Computing Systems Using Kubernetes
Explore edge computing for smart farms using K3s, sensors, and Raspberry Pi. Learn to design and implement real-time monitoring systems for agriculture in Latin America.
Machine Learning Day: From Generative AI to Vector Databases
Explore cutting-edge Machine Learning topics with expert talks on multimodal generative AI, OpenAI embeddings, vector databases, and building products in the GenAI era.

Getting Started with Retrieval Augmented Generation (RAG) in Java and Spring AI
Learn to implement Retrieval Augmented Generation (RAG) using Java and Spring AI. Explore RAG's applications, setup process, and practical implementation with a simple example.
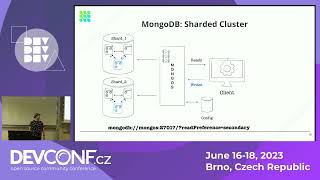
Change Data Capture for Non-Relational Databases
Explore Debezium for real-time data streaming with MongoDB. Learn deployment topologies, outbox pattern implementation, and building scalable architectures for efficient data synchronization.
Next Generation of Datastores: Hot Queries, Cold Storage
Explore how blob stores revolutionize datastore architecture, offering scalability and cost-efficiency. Learn about S3-compatible options, use cases, and trade-offs.
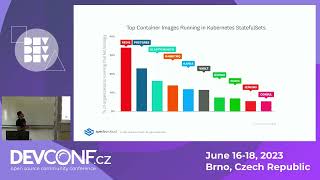
Kube-Native CI/CD Pipelines for Containerized Databases
Explore Kube-native CI/CD pipelines for containerized databases, covering automated workflows, database operators, and Tekton optimization for microservices architecture.
Open Source Databases on Kubernetes: Best Practices
Discover best practices for running open-source databases on Kubernetes, covering high availability, security, backups, and disaster recovery using Percona Operators.
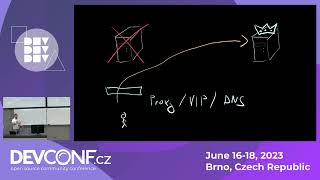
Distributed SQL Transactions
Explore distributed SQL transactions and two-phase commits, learning implementation over PostgreSQL and handling server failures in large-scale data systems.
Introduction to Kubernetes Operators for Databases
Explore Kubernetes Operators for automating database management, reducing complexity, and enhancing DevOps practices in modern architectures.

Orchestrating RAG: Retrieval, Canopy, and Pinecone
Explore orchestrating RAG pipelines, optimizing retrieval strategies, and leveraging Canopy and Pinecone for scalable AI applications with billions of documents.

Building LLM-Powered Apps: Best Practices for Vector Databases and LLMOps
Explore best practices for LLM-based app development, covering design considerations, technical aspects, and deployment strategies for optimal performance and scalability.
Advanced RAG: Chunking, Embeddings, and Vector Databases
Explore advanced RAG concepts: chunking for efficient retrieval, embeddings for text representation, and vector databases for optimized storage and retrieval in LLM applications.
Building an LLMOps Stack for Large Language Models
Explore LLMOps architecture: MLFlow for LLMs, Vector Databases, RAG strategies, and prompt evaluation. Gain insights into optimizing and deploying large language models effectively.
VertexAI Embeddings with Pinecone and LangChain - Building a Retrieval Component
Aprenda a implementar un componente de recuperación utilizando VertexAI Embeddings, Pinecone y Langchain para aplicaciones de aprendizaje automático y ciencia de datos.