Zero Downtime Data Relocation with Vitess
Explore Vitess's flexible sharding architecture for zero-downtime data relocation across jurisdictions, enabling data locality compliance without application redesign.
Still Writing SQL Migrations? You Could Use A Schema Hero
Discover SchemaHero, a Kubernetes-based solution for database schema migrations. Learn how declarative desired state simplifies and automates the process, making migrations predictable and reliable.
Five Great Ways to Lose Data on Kubernetes - And How to Avoid Them
Explore common data loss scenarios in Kubernetes and learn effective prevention strategies. Gain insights on high availability, disaster recovery, and cloud-native challenges for database management.
Patterns to Build Stateful Apps with Serverless
Explore patterns for building stateful serverless apps, addressing data access, persistence, and sharing across executions. Learn solutions for integrating serverless with existing applications.
TiFlash - Make TiKV 10x Faster and HTAP-able
Explore TiFlash: a columnar engine for TiKV that enables real-time analytics and HTAP scenarios, offering consistent replicas and significant performance improvements for analytical workloads.
TiFlash - Make TiKV 10x Faster and HTAP-able
Explore TiFlash, a novel component for TiKV that enables HTAP capabilities, offering 10x faster analytical processing and strong workload isolation through a Raft-based architecture and columnar storage.
Elastic Scheduling with TiKV
Explore elastic scheduling in TiKV, a distributed Key-Value database. Learn how this feature automatically balances cost and load, handling traffic bursts in cloud-native environments.
Codename VIFL - How to Migrate MySQL Database Clusters to Vitess
Learn how Slack migrated petabytes of data to Vitess with zero downtime using a transparent, application-agnostic framework. Discover strategies for seamless large-scale database migrations.
Running Vitess on Kubernetes at Massive Scale - JD.com Case Study
Explore Vitess on Kubernetes: JD.com's massive-scale implementation, architecture insights, and future plans for this cloud-ready relational database system.
Operating Deep Learning Pipelines Anywhere Using Kubeflow
Explore building and operating production-grade deep learning pipelines using Kubeflow, covering data preparation, storage, automation, and infrastructure management for multiple tenants.
SIG Service Catalog
Explore Kubernetes Service Catalog: provision cloud services across platforms using Open Service Broker API. Learn to access third-party services and connect databases to applications in Kubernetes clusters.
Polymorphic Record Types in a Lifted Embedding
Explore Slick's lifted embedding for database operations in Scala, focusing on polymorphic record types, abstractions for tuples, and functional dependencies in DSL design.
Lessons to Scala Native from Kotlin Native
Explore insights from Kotlin Native for Scala Native development, covering compilation, memory management, debugging, and practical applications in native environments.
Processing Data at Scale with Rails
Strategies for handling large datasets using Rails, covering data ingestion, transformation, and storage with tools like ActiveRecord, Sidekiq, and Postgres.
The Cost of Data
Explore the physical impact of data storage and creation, examining the challenges and advancements in data centers, and learn how our code affects the real world.
Scaling Rails API to Write-Heavy Traffic
Practical techniques for scaling Rails API to handle millions of database transactions per minute, focusing on multiple databases and sharding for write-heavy traffic in mobile gaming.
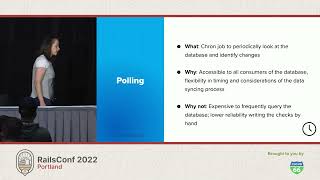
Call Me Back, Postgres
Explore Postgres triggers as an alternative to Active Record callbacks, enabling seamless data syncing and process management in complex Rails applications.
Your Service Layer Needn't be Fancy, It Just Needs to Exist
Learn how to implement a service layer in your Rails app to improve sustainability and separate business logic from Active Records, without complex patterns or libraries.
Data Indexing with RGB - Ruby, Graphs and Bitmaps
Explore data indexing using Ruby, graph databases, and bitmap stores to build a unique data engine, improving query speed and enabling cross-market analysis and harmonization.
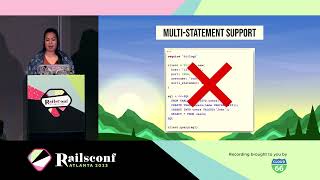
Migrating Shopify's Core Rails Monolith to Trilogy
Explore Shopify's migration from Mysql2 to Trilogy, covering MySQL protocols, Active Record adapters, and open source contributions. Learn about implementation challenges and the impact on Shopify's monolith.
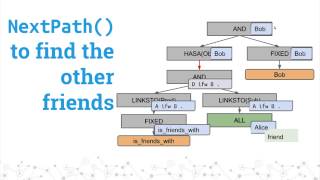
Cayley - Building a Graph Database
Explore the architecture and components of Cayley, a Go-based graph database inspired by Freebase.com, including query languages, storage engines, and iterator trees.