Scaling Postgres for Time Series Data with Citus
Scaling Postgres for time series data using Citus: partitioning, distribution, and automation techniques to handle high-volume, ever-growing data efficiently across a cluster.
Build a High Performance Remote Storage for Prometheus with Unlimited Time Series
高性能Prometheus远程存储方案:支持无限时间序列,将目标标签编码到一列,应用标签展平为独立列,实现高性能查询,解决高基数问题

The Parquet Format and Performance Optimization Opportunities
Explore Parquet format intricacies, columnar storage basics, and optimization techniques for Spark workloads. Learn about encoding, compression, predicate pushdown, and Delta Lake to enhance analytical performance.
Meta Velox - Advanced Database Systems - Lecture 23
Explore Meta's Velox query execution engine, its architecture, and its role in modern data processing systems. Learn about its features and performance optimizations.
Databricks Photon and Spark SQL in Advanced Database Systems - Lecture 20
Explore Databricks Photon and Spark SQL's advanced features for efficient data processing and analysis in modern database systems.
Modern Analytical Database Systems - Lecture 2
Explore modern analytical database systems, covering distributed architectures, query execution, and OLAP commoditization in this advanced CMU lecture.
Yellowbrick Data Warehouse System - Lecture 21
Explore Yellowbrick's innovative data warehouse system, its architecture, and performance optimizations for analytical workloads in this advanced database systems lecture.
Snowflake Data Warehouse Internals - Lecture 19
Explore Snowflake's data warehouse architecture, design principles, and internal workings. Gain insights into its innovative approach to cloud-based data management and analytics.
Databricks Photon and Spark SQL in Advanced Database Systems - Lecture 18
Explore Databricks Photon and Spark SQL architectures, optimizations, and performance improvements in modern data processing systems.
Modern OLAP Database Systems - Lecture 1
Explore modern OLAP database systems, their architectures, and optimizations for analytical workloads in this advanced lecture from Carnegie Mellon University.
Zedstore - Compressed Columnar Storage for Postgres
Explore Zedstore, a compressed columnar storage solution enhancing Postgres performance and efficiency. Learn its architecture, benefits, and implementation from VMware experts.
Columnar Storage: Redefining Data Management for the Modern Era
Discover how columnar storage optimizes data warehousing through Apache Arrow, Parquet, and Pandas, improving query performance and reducing costs while enhancing analytics workflows.

Powering Interactive Data Applications at Scale
Explore Druid's architecture for powering interactive analytic applications with millisecond query latencies, comparing it to traditional databases and key/value stores for OLAP use cases.
Inside the VertiPaq Engine
Explore VertiPaq engine internals, database architecture, and optimization techniques for improved performance and compression in SQL Server Analysis Services Tabular, Power BI, and Power Pivot.
TiFlash - Make TiKV 10x Faster and HTAP-able
Explore TiFlash: a columnar engine for TiKV that enables real-time analytics and HTAP scenarios, offering consistent replicas and significant performance improvements for analytical workloads.
TiFlash - Make TiKV 10x Faster and HTAP-able
Explore TiFlash, a novel component for TiKV that enables HTAP capabilities, offering 10x faster analytical processing and strong workload isolation through a Raft-based architecture and columnar storage.
Shredding Deeply Nested JSON for Efficient Analytics in DuckDB
Discover how DuckDB efficiently processes nested JSON data through vectorized analytics, enabling direct reading of JSON files as tables with automatic schema detection for powerful data analysis.
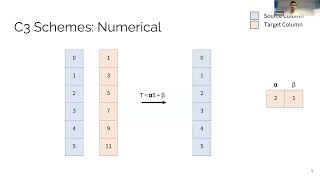
C3: Compressing Correlated Columns - A Framework for Multi-Column Data Compression
Discover how C3 framework revolutionizes data compression by exploiting correlations between columns, achieving 20% better compression ratios through innovative multi-column compression schemes.
Leveraging Apache Flight Python Client and InfluxDB for Time Series Data Management
Explore Apache Flight Python Client and InfluxDB integration for efficient time series data management. Learn about columnar storage, benchmarks, and real-world applications in data architecture.
Ten Years of Building Open Source Standards: From Parquet to Arrow to OpenLineage
Explore the journey of building open-source data standards, from Apache Parquet to Arrow to OpenLineage. Gain insights into successful project ideation, growth, and ecosystem impact in data management.
Amazon Redshift Data Warehouse System - Lecture 22
Explore Amazon Redshift's architecture, design principles, and performance optimizations for large-scale data warehousing in this advanced database systems lecture.