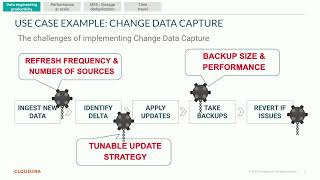
Four Technical Value Drivers of a Data Lakehouse with Iceberg
Explore four key technical value drivers of data lakehouses and how Apache Iceberg enhances these capabilities for data practitioners across various roles.
Meta Velox - Advanced Database Systems - Lecture 23
Explore Meta's Velox query execution engine, its architecture, and its role in modern data processing systems. Learn about its features and performance optimizations.

Snowflake Data Warehouse Internals - Lecture 21
Explore Snowflake's data warehouse architecture, design principles, and internal mechanisms for efficient cloud-based data management and analytics.
Databricks Photon and Spark SQL in Advanced Database Systems - Lecture 20
Explore Databricks Photon and Spark SQL's advanced features for efficient data processing and analysis in modern database systems.
Modern Analytical Database Systems - Lecture 2
Explore modern analytical database systems, covering distributed architectures, query execution, and OLAP commoditization in this advanced CMU lecture.
Snowflake Database Architecture Overview - Lecture 25
Explore Snowflake's cloud-based database architecture, including query execution, optimization, and workload management, with insights from industry experts.
Domain Knowledge Augmented AI for Databases - Alibaba
Explore domain knowledge augmented AI for databases, focusing on Alibaba's innovative approaches and their impact on database management systems.
Yellowbrick Data Warehouse System - Lecture 21
Explore Yellowbrick's innovative data warehouse system, its architecture, and performance optimizations for analytical workloads in this advanced database systems lecture.
Snowflake Data Warehouse Internals - Lecture 19
Explore Snowflake's data warehouse architecture, design principles, and internal workings. Gain insights into its innovative approach to cloud-based data management and analytics.
Databricks Photon and Spark SQL in Advanced Database Systems - Lecture 18
Explore Databricks Photon and Spark SQL architectures, optimizations, and performance improvements in modern data processing systems.
Modern OLAP Database Systems - Lecture 1
Explore modern OLAP database systems, their architectures, and optimizations for analytical workloads in this advanced lecture from Carnegie Mellon University.
Challenges of Spark Application Coexisting with NoSQL Databases
Explore challenges and solutions for integrating Apache Spark with NoSQL databases like MongoDB and Cassandra in high-volume transaction processing systems, focusing on performance optimization and data modeling.

Data Engineering: A Deep Dive into Databricks
Master Databricks for efficient data processing, focusing on Apache Spark transformations, ingestion methods, storage, orchestration, and best practices to optimize data engineering workflows.

State Storage in Spark Structured Streaming
Learn to configure and manage state storage in Spark Structured Streaming for efficient data processing and analysis.
Full Airtable Project Management Demo 2024 - How to Use Airtable
Learn to manage projects efficiently with Airtable's powerful features. Master inventory tracking, task organization, and collaboration tools for streamlined workflows and improved productivity.
Full Notion Tutorial for Beginners - How to Use Notion
Master Notion's features: create journals, tables, and documents. Learn text formatting, image insertion, and formula usage in this comprehensive beginner's guide.
Challenges and Solutions for Building Real-time Data Warehousing with Apache Flink, Apache Hive and Apache Iceberg
Explore solutions for real-time data warehousing using Apache Flink, Hive, and Iceberg. Learn to handle challenges like late events and dirty data routing in enterprise-level ETL migration.
Smooth Migration Practice from MapReduce to Spark at ByteDance
Learn ByteDance's smooth migration solution from MapReduce to Spark, reducing costs and improving performance. Explore design, implementation, and benefits of transitioning legacy jobs with minimal changes.
Hive-Iceberg Integration: Breaking the Ice - A Closer Look at Features and Developments
Explore latest developments in Hive-Iceberg integration, including statistics, branching, tagging, compactions, and concurrency. Gain insights into seamless integration and advanced features.
Cloud Agnostic Data Platform with DBT, Trino, Iceberg and MinIO
Explore a hands-on, cloud-agnostic data pipeline using TrinoDB, DBT, MinIO, and Apache Iceberg for scalable and lightweight analytics, suitable for both cloud and on-premise solutions.
Gravitino - A Multi-Regional Geo-Distributed Meta Datalake
Discover how to build and manage distributed meta datalakes using Gravitino, exploring multi-regional architectures and implementation strategies for scalable data solutions.