Automating Data Management with Oracle Autonomous Database
Discover how Oracle Autonomous Database simplifies data management, enhancing productivity for analysts, data scientists, and developers through continuous innovation in operational and analytical workloads.

Big Query Live Training - A Deep Dive Into Data Pipelining
Explore data pipelining with BigQuery: learn to process, analyze, and visualize large datasets efficiently. Gain hands-on experience in extracting, loading, and transforming data for marketing insights.
Timebase CE: Open Source Time-Series Data Warehouse for Crypto Exchanges
Explore TimeBase CE: open-source time-series data warehouse for building analytical models and applications, with focus on crypto exchange connectivity and community-driven development.
OLAP on Cassandra Data with Arrow, Flight SQL, ADBC, and DuckDB
Explore modern OLAP techniques for Cassandra data using Arrow, Flight SQL, ADBC, and DuckDB. Learn to convert sstable snapshots to Parquet, enable real-time analytics, and leverage Flight SQL for efficient querying.
Microsoft Fabric: Tour of the User Interface
Explore Microsoft Fabric's self-service data and AI platform interface, learning key concepts and navigation for effective data management and analysis.
SQL Programming on Databricks - Advanced Features and Future Roadmap
Explore advanced SQL features in Databricks, including GROUP BY ALL and EXECUTE IMMEDIATE, to tackle complex scenarios efficiently. Preview upcoming SQL programming enhancements.
BigQuery Native Integration with Delta Lake - The Latest Announcement
Explore BigQuery's native querying of Delta Lake tables, enhancing data strategy with improved performance and cross-cloud capabilities. Learn about GCP's open platform integrations and interoperability features.
Impala Discovers Iceberg Metadata Tables
Discover how Impala integrates with Apache Iceberg metadata tables to enhance data lake querying capabilities and improve performance in modern data architectures.
Analytics and Real-time Database Workloads: Combining OLTP and OLAP Systems
Explore strategies for optimizing concurrent OLAP and OLTP workloads, focusing on ScyllaDB's workload prioritization features to achieve harmonious performance in distributed systems.
Data as Code - Project Nessie and Git-like Experience for Apache Iceberg Tables
Discover how Project Nessie enables multi-table transactions and Git-like workflows for Apache Iceberg tables, revolutionizing data lakehouse management and engineering practices.
Open Formats: The Happy Accident Disrupting the Data Industry
Discover how open table formats like Apache Iceberg are revolutionizing data accessibility, breaking vendor lock-in, and enabling shared analytics across multiple query engines.
CICD Pipelines for dbt - Choosing Between DIY and Cloud Solutions
Explore the trade-offs between building custom CICD pipelines for dbt projects versus using dbt Cloud's built-in solutions, focusing on Slim CI and documentation deployment strategies.
Data Mesh: From Experimentation to Industrialization - A Financial Services Case Study
Discover how a financial organization transformed their data architecture using Data Mesh on GCP, reducing lead times from months to days while enabling self-service analytics and cross-domain collaboration.
Rise, Fall and Re-Rise of the Semantic Layer - Evolution and Future of Data Management
Explore the evolution of semantic layers in data management, from traditional systems to modern metric stores, while understanding key challenges and future directions in data truth management.
Columnar Storage: Redefining Data Management for the Modern Era
Discover how columnar storage optimizes data warehousing through Apache Arrow, Parquet, and Pandas, improving query performance and reducing costs while enhancing analytics workflows.
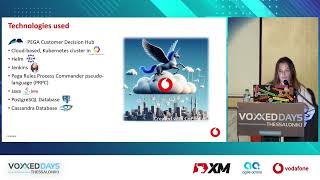
From AI Conversations to Data-Driven Decisions - Unlocking the Future of Customer Engagement
Explore how AI assistant Tobi leverages machine learning, data engineering, and analytics to predict customer needs and deliver personalized offers through integrated backend systems.
Simplifying Iceberg Table Lifecycle Management - A Comprehensive Approach
Discover efficient strategies for managing Iceberg tables through lifecycle optimization techniques, focusing on Apache Hive and Flink integration for enhanced data warehouse operations.
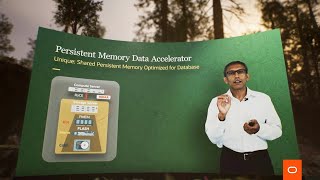
Database Consolidation With Persistent Memory
Discover how Exadata leverages Intel PMEM and RoCE 100Gbs infrastructure to accelerate OLTP and OLAP workloads, optimizing database performance and consolidation.
Data Lakehouse and Data Mesh - Two Sides of the Same Coin
Explore how Data Lakehouse and Data Mesh complement each other in modern data management, combining technological advancements with organizational strategies for effective analytics.
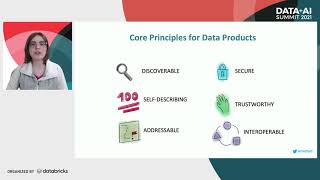
Architect's Open-Source Guide for Data Mesh Architecture
Explore Data Mesh architecture, its principles, benefits, and implementation challenges. Learn about open-source tools like Apache Spark for building effective Data Mesh systems in real-world scenarios.
Scaling Climate Data for FinTech with an Open Source Data Mesh
Explore how OS-Climate builds an open data platform for climate impact analysis using open-source tools. Learn about data mesh architecture, scalability challenges, and community-driven development.