Data Warehousing on the Lakehouse - Unifying Data, AI, and Analytics
Unify data, AI, and analytics with the lakehouse architecture. Learn success stories, use cases, and best practices for ingesting, storing, and governing data at scale for SQL and BI workloads using Databricks SQL.
Dimensional Modeling
Learn key concepts and practices of Dimensional Modeling using the Kimball Method. Explore star schemas, snowflake schemas, surrogate keys, and slowly changing dimensions for effective data warehouse design.
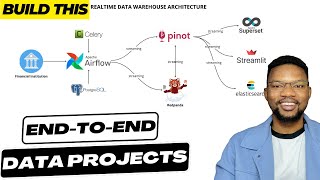
Building Realtime Data Warehouses from Scratch - End-to-End Data Engineering Project
Design and implement a real-time data warehouse with Apache Airflow, Kafka, and Pinot. Create custom hooks, ingest batch and streaming data, and visualize evolving data using Apache Superset.
Data Warehouse Automation Using Agile Methods
Explore agile data warehouse development using Data Vault design and metadata-driven automation for faster delivery, flexible architecture, and improved documentation in business intelligence projects.
Defining Entities and Attributes for Tabular Models - 20 Minute Guide
Define entities and attributes for tabular models using real-life project examples to improve design and address common issues.
Data Modelling Showdown: Unravelling the Mysteries of Different Data Modelling Approaches
Explore diverse data modelling approaches, from Dimensional to Data Vault, understanding their strengths and optimal use cases for effective data management and analytics.
Practical Kimball Data Patterns for Machine Learning Data Warehousing
Discover how dimensional modeling and Kimball patterns can streamline machine learning projects, reduce data preparation time, and improve ML model development through practical warehouse design techniques.
Gathering Requirements for Your Star Schema
Collaboratively design dimensional models with business users for effective star schema requirements gathering and data visualization.
Star Schema ALL the Things! But Why? - Practical Design Decisions in Data Modeling
Explore practical star schema design, from source to model to report. Learn best practices, test methodologies, and assess performance impacts in data modeling.