Turbocharging AI/ML Development with Snowflake Data Cloud
Discover how to accelerate AI/ML innovation using Snowflake's Data Cloud, from model development to production deployment, featuring Snowpark, Container Services, and ML-powered functions.
Data Alchemy: Transforming Raw Data to Gold with Apache Hudi and DBT
Discover how to build efficient medallion architecture using Apache Hudi's CDC feature and DBT for incremental data processing, enabling low-latency analytics and streamlined data transformation workflows.
Navigating the Landscape of a Fully Open Source Data Stack in 2023
Explore the architecture of modern data stacks, from warehousing to streaming solutions, while understanding the potential and limitations of open-source tools in today's data infrastructure.
Many Faces of Real-time Analytics: A Guide to System Classification and Implementation
Explore real-time analytics systems classification, characteristics, and technology choices for implementing different analytical solutions in production environments.
Unveiling the Power of dbt and DuckDB - Hype vs Reality
Explore the practical applications and limitations of combining dbt and DuckDB for data transformations, examining real-world use cases and performance considerations.
The Real Modern Data Stack - Building ETL Pipelines with Open Source Tools
Discover how to build powerful, cost-effective ETL data stacks using open-source tools like sling, dbt, duckdb, and dagster - transforming months of implementation into rapid deployment.
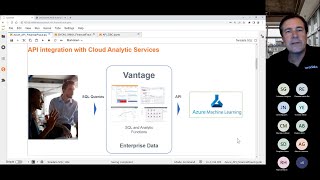
Accelerating AI and ML Insights with Azure ML and Teradata VantageCloud
Discover how Teradata VantageCloud and Azure ML integration accelerates AI and ML insights at scale, overcoming deployment challenges and unlocking data-driven value for organizations.

Building a Robust Data Pipeline with the DAG Stack - dbt, Airflow, and Great Expectations
Learn to build robust data pipelines using dbt, Airflow, and Great Expectations. Discover how these tools complement each other to ensure data quality, perform transformations, and orchestrate workflows effectively.
Building End-to-End Delta Pipelines on GCP
Explore building end-to-end Delta pipelines on GCP, covering data reliability, performance, and the Bronze-Silver-Gold architecture pattern, with practical code examples and Big Query integration.
DBT Using Databricks and Delta
Learn to leverage Data Build Tool (DBT) with Databricks and Delta for efficient data lake management, including SQL-first approach, upsert capabilities, and Azure integration for enhanced observability.
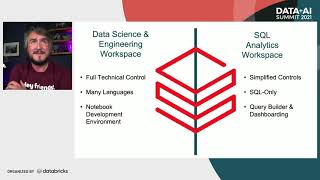
Getting Started with Databricks SQL Analytics
Explore Databricks SQL Analytics: set up SQL endpoints, query workspaces, create dashboards, and connect BI tools. Learn how this tool enhances the Lakehouse architecture for SQL-savvy data analysts.
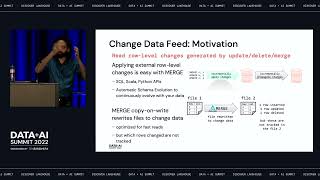
Delta Lake 2.0 Overview - New Features and Community Collaborations
Overview of Delta Lake 2.0 features, integrations, and community collaboration. Highlights include data skipping, Change Data Feed, column mapping, multi-cluster S3 writes, and support for various languages and platforms.
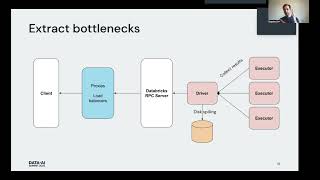
Cloud Fetch: High-Bandwidth Connectivity for BI Tools - Databricks
Explore high-bandwidth connectivity for BI tools using Cloud Fetch, a parallel data extraction mechanism that significantly speeds up query result retrieval from Databricks SQL endpoints.
Understand Slowly Changing Dimensions
Learn to handle Slowly Changing Dimensions in data warehousing, including SCD types, their implementation, and impact on star schema design. Gain expertise for interviews and practical applications.
Slowly Changing Dimensions Type 2 in Data Lakes - Tech Chat
Explore Slowly Changing Dimensions Type 2 in data lakes using Delta Lake, focusing on market segmentation for a climbing eCommerce site. Learn to track historical and current data effectively.
Orchestration Made Easy with Databricks Workflows
Discover Databricks Workflows: a managed orchestration service for streamlined data pipelines. Learn to create, run, and monitor reliable workflows, implement recovery actions, and explore new features for efficient data management.
Data Warehousing on the Lakehouse - Unifying Data, AI, and Analytics
Unify data, AI, and analytics with the lakehouse architecture. Learn success stories, use cases, and best practices for ingesting, storing, and governing data at scale for SQL and BI workloads using Databricks SQL.
Analysis Services - What Is the Difference Between Tabular and Multidimensional Models
Explore the differences between Tabular and Multidimensional models in Microsoft Analysis Services, their use cases, and how to choose the right model for your data analysis needs.
Dimensional Modeling
Learn key concepts and practices of Dimensional Modeling using the Kimball Method. Explore star schemas, snowflake schemas, surrogate keys, and slowly changing dimensions for effective data warehouse design.
Breaking Out of the Proprietary Cage - Real-time Data Warehouses in Open Source
Explore real-time data warehouses in open source, focusing on ClickHouse's architecture, performance optimization, and integration patterns for modern analytics applications.
The Pace of Innovation in Delta Lake
Explore the rapid advancements and innovative features of Delta Lake, enhancing data reliability and performance in modern data architectures.