Unlocking Scalable and Efficient Data Storage with Apache Ozone
Discover how Apache Ozone revolutionizes distributed object storage, offering scalable solutions for managing massive data volumes while ensuring reliability, cost-effectiveness, and seamless integration with Hadoop ecosystem.
Maximizing Query Speed and Minimizing Costs in Data Lakes with Open-Source Caching
Discover how to optimize data lake performance and reduce costs using open-source caching frameworks, with practical techniques for query acceleration and storage efficiency.
Where the Modern Data Stack Has Failed and Why Engineering-centric Tools Will Reshape the Data World
Explore how engineering-focused tools like DuckDb, SDF, and Dagster are reshaping data engineering, addressing limitations of the modern data stack, and enabling more scalable, programmable solutions.
CXL and NVMe Collaborating for Computation
Explore how CXL and NVMe technologies collaborate for enhanced computational storage, focusing on memory interfaces, accelerator devices, and data coherency in modern storage architectures.
Actionable Ethics for Data Scientists - Emily Miller
Explore ethical considerations in data science, covering data collection, storage, analysis, and modeling. Learn practical strategies to address ethical challenges in your work.
TimescaleDB - PostgreSQL for Time-Series Data
Explore TimescaleDB for efficient time-series data management in PostgreSQL, focusing on stock market applications and practical coding examples.
Data Engineering and Storage Concepts - With ETL, ELT, Warehouse, Lake, and Lake House
Comprehensive overview of data engineering concepts, including storage solutions, ETL/ELT processes, and modern data architectures like data mesh, with practical examples and best practices for effective data management.
Geospatial Data Analysis in Apache Spark - Challenges and Solutions
Explore geospatial data challenges in Apache Spark, comparing libraries, and learning best practices for data ingestion, storage, and retrieval using spatial indexing techniques.

The Apache Spark File Format Ecosystem - Optimizing Storage for Performance
Explore key file formats in Spark ecosystem: Parquet, ORC, Avro. Learn core concepts, optimization techniques, and how to select the right format for performant data processing and AI/ML workflows.
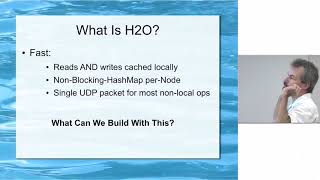
Big Data Processing on Small Computers
Explore distributed computing, MapReduce, and parallel programming techniques for handling big data on small-scale systems with expert insights.
Unleashing Innovation from Core to the Edge
Explore cutting-edge innovations in data storage and management with Western Digital's CTO. Learn about transformative technologies shaping the future of digital infrastructure.
Building Modern Data Streaming Apps with Open Source
Discover best practices for building data streaming applications using open-source frameworks. Learn to orchestrate streams, perform ETL, enhance events, and make continuous queries with tools like Apache NiFi, Pulsar, Spark, and Flink SQL.
The Pace of Innovation in Delta Lake
Explore the rapid advancements and innovative features of Delta Lake, enhancing data reliability and performance in modern data architectures.
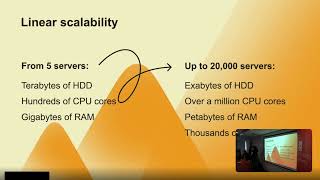
YTsaurus - The Next Generation of Open Source Big Data Platforms
Explore YTsaurus, an open-source big data platform for distributed storage and processing. Learn about its components, features, and capabilities for creating large-scale clusters up to 20,000 nodes.
Toward Efficient Genomic Compression Using Channel Codes for Joint Alignment and Reconstruction
Explore innovative genomic compression techniques using channel codes for efficient alignment and reconstruction, advancing data storage and analysis in genomics research.
Building an Open Data Lakehouse Using Apache Spark, Apache Iceberg and Dremio
Explore the evolution of big data to data lakehouses, focusing on open architecture development, security, governance, and augmentation using Dremio, Apache Spark, and Apache Iceberg.
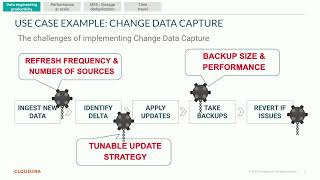
Four Technical Value Drivers of a Data Lakehouse with Iceberg
Explore four key technical value drivers of data lakehouses and how Apache Iceberg enhances these capabilities for data practitioners across various roles.

Snowflake Data Warehouse Internals - Lecture 21
Explore Snowflake's data warehouse architecture, design principles, and internal mechanisms for efficient cloud-based data management and analytics.
Snowflake Database Architecture Overview - Lecture 25
Explore Snowflake's cloud-based database architecture, including query execution, optimization, and workload management, with insights from industry experts.
Snowflake Data Warehouse Internals - Lecture 19
Explore Snowflake's data warehouse architecture, design principles, and internal workings. Gain insights into its innovative approach to cloud-based data management and analytics.

Data Engineering: A Deep Dive into Databricks
Master Databricks for efficient data processing, focusing on Apache Spark transformations, ingestion methods, storage, orchestration, and best practices to optimize data engineering workflows.