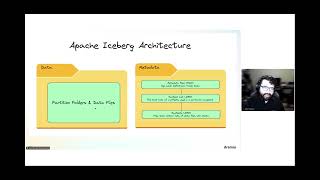
The Who, What, and Why of Data Lake Table Formats
Explore data lake table formats, their creators, purposes, and significance in modern data architecture. Gain insights into optimizing data management and analytics.
The Practice of Data Lake in Xiaomi's Data and AI Scenarios
Discover how Xiaomi implements data lake architecture to power their data and AI systems, exploring real-world applications and practical solutions for large-scale data management.
Where the Modern Data Stack Has Failed and Why Engineering-centric Tools Will Reshape the Data World
Explore how engineering-focused tools like DuckDb, SDF, and Dagster are reshaping data engineering, addressing limitations of the modern data stack, and enabling more scalable, programmable solutions.
Building Modern Data Streaming Apps with Open Source
Discover best practices for building data streaming applications using open-source frameworks. Learn to orchestrate streams, perform ETL, enhance events, and make continuous queries with tools like Apache NiFi, Pulsar, Spark, and Flink SQL.
Building an Open Data Lakehouse Using Apache Spark, Apache Iceberg and Dremio
Explore the evolution of big data to data lakehouses, focusing on open architecture development, security, governance, and augmentation using Dremio, Apache Spark, and Apache Iceberg.
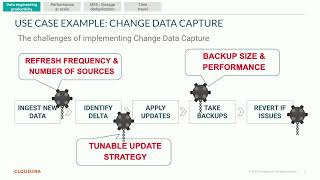
Four Technical Value Drivers of a Data Lakehouse with Iceberg
Explore four key technical value drivers of data lakehouses and how Apache Iceberg enhances these capabilities for data practitioners across various roles.
Challenges and Solutions for Building Real-time Data Warehousing with Apache Flink, Apache Hive and Apache Iceberg
Explore solutions for real-time data warehousing using Apache Flink, Hive, and Iceberg. Learn to handle challenges like late events and dirty data routing in enterprise-level ETL migration.
Hive-Iceberg Integration: Breaking the Ice - A Closer Look at Features and Developments
Explore latest developments in Hive-Iceberg integration, including statistics, branching, tagging, compactions, and concurrency. Gain insights into seamless integration and advanced features.
Cloud Agnostic Data Platform with DBT, Trino, Iceberg and MinIO
Explore a hands-on, cloud-agnostic data pipeline using TrinoDB, DBT, MinIO, and Apache Iceberg for scalable and lightweight analytics, suitable for both cloud and on-premise solutions.
Efficient, Low Latency Ingestion to Large Tables via Apache Flink and Apache Iceberg
Learn efficient, low-latency data ingestion techniques using Apache Flink and Apache Iceberg for large tables. Explore integration challenges, performance optimizations, and comparisons with alternative solutions.
Reducing Complexity and Increasing Performance with Trino
Discover how Trino's distributed SQL query engine revolutionizes data processing, featuring new capabilities like table procedures, polymorphic functions, and modern SQL features for enhanced performance.
Building a Fully-Managed OSS-Compatible Lakehouse with BigLake Managed Tables
Discover how BigLake Managed Tables enhances open lakehouse formats by combining BigQuery infrastructure with OSS compatibility for improved data management, access control, and high-throughput streaming.
Gravitino REST Catalog Service for Apache Iceberg - Why and Beyond
Explore the Gravitino REST catalog service's integration with Apache Iceberg, examining its implementation, benefits, and future potential for data lake management.
Navigating the Lakehouse - Best Practices for Implementation with Apache Iceberg
Discover essential best practices and implementation strategies for Apache Iceberg in data lakehouse architectures, focusing on optimal performance and data management techniques.
Impala Discovers Iceberg Metadata Tables
Discover how Impala integrates with Apache Iceberg metadata tables to enhance data lake querying capabilities and improve performance in modern data architectures.
Efficiently Managing and Optimizing Apache Iceberg with Apache Amoro
Discover how to optimize Apache Iceberg data lakes using Apache Amoro, exploring efficient management techniques and performance enhancements for large-scale data operations.
Data as Code - Project Nessie and Git-like Experience for Apache Iceberg Tables
Discover how Project Nessie enables multi-table transactions and Git-like workflows for Apache Iceberg tables, revolutionizing data lakehouse management and engineering practices.
Open Formats: The Happy Accident Disrupting the Data Industry
Discover how open table formats like Apache Iceberg are revolutionizing data accessibility, breaking vendor lock-in, and enabling shared analytics across multiple query engines.
Simplifying Iceberg Table Lifecycle Management - A Comprehensive Approach
Discover efficient strategies for managing Iceberg tables through lifecycle optimization techniques, focusing on Apache Hive and Flink integration for enhanced data warehouse operations.
Row-level Modifications at Petabyte-scale via Impala on Iceberg
Discover how to perform efficient row-level modifications on massive datasets using Impala with Apache Iceberg, enabling petabyte-scale data management and manipulation.
Build Open Format Data Lakehouse
Explore open format data lakehouse architecture, benefits, and implementation strategies for efficient cloud-native data management and analytics.