Transaction Log as the Heart of Delta Lake - Understanding Structure and Operations
Dive into the mechanics of Delta Lake's transaction log through hands-on PySpark exercises, exploring its structure, operations, and advantages over traditional data lakes.
Building Your First Petabyte-Scale Architecture - Part 1
Dive into petabyte-scale data architecture design, exploring technologies like Redshift, Databricks, and BigQuery while mastering cost estimation, performance optimization, and architectural considerations.
Building Your First Petabyte-Scale Architecture - Part 2
Dive into petabyte-scale data architecture design, exploring technologies like Redshift, Databricks, and BigQuery while mastering cost estimation, performance optimization, and architectural considerations.
DuckDB Internals - Advanced Database Systems - Lecture 22
Explore DuckDB's architecture, design principles, and internal workings with guest lecturer Mark Raasveldt. Gain insights into advanced database systems and their implementation.
Weaviate: An Architectural Deep Dive
Explore Weaviate's architecture, delving into its vector database design, scalability features, and innovative approaches to data storage and retrieval in this comprehensive seminar.
Data Formats and Encoding for Advanced Database Systems - Part 1
Explore advanced database concepts, focusing on data formats and encoding techniques for efficient storage and retrieval in modern systems.
Observability Data Volumes and Strategies for Managing System Growth
Explore strategies for managing growing observability data volumes, from historical growth patterns to current solutions and future possibilities in data processing and storage optimization.
Catching Waves with Time-Series Data - Best Practices for Storage and Analysis
Dive into time-series data management through a surfer's journey, exploring efficient storage, querying, aggregation, and API implementation for real-world applications in IoT and finance.
Optimizing Hard Drives and SSDs with SpinRite - A Guide to Data Life Extension
Discover how to optimize hard drives and SSDs using SpinRite, exploring techniques to extend data life and maintain drive health while learning about historical computer storage systems.
Распределённое хранение и обработка больших данных
Dive into распределённое хранение и обработку больших данных с открытым ПО Яндекса, изучая методы отображения изменяемых таблиц на неизменяемые фрагменты для эффективной обработки данных.
AIStore as a Fast Tier Storage Solution: Enhancing Petascale Deep Learning Across Cloud Backends
Explore AIStore's innovative approach to handling petascale datasets, offering high-performance storage solutions for deep learning with linear scalability and optimized cloud backend integration.
Optimizing Apache HoraeDB for High-Cardinality Metrics at AntGroup
Discover optimization techniques for handling high-cardinality metrics in Apache HoraeDB, featuring real-world implementation strategies from AntGroup's engineering experience.
Introduction to Cloud and Edge Computing - Core Concepts and Applications
Discover the fundamentals of cloud and edge computing, exploring service models, deployment strategies, and real-world applications while understanding how these technologies complement each other for optimal performance.
Gravitino - A Multi-Regional Geo-Distributed Meta Datalake
Discover how to build and manage distributed meta datalakes using Gravitino, exploring multi-regional architectures and implementation strategies for scalable data solutions.

Introduction to Web Application Architecture and System Design
Explore comprehensive web application development, from front-end design to back-end systems, databases, security, and maintenance, focusing on practical architecture decisions and implementation strategies.
Secure and Streamline Data Engineering Workloads with Azure Data Factory and Snowflake
Discover how to optimize data engineering workflows using Azure Data Factory and Microsoft Fabric with Snowflake, featuring bi-directional data access through Apache Iceberg for enhanced security and performance.
Open Standards for Open Lakehouses - Understanding Apache Iceberg, Parquet, Arrow, and Nessie
Discover how open-source standards like Apache Iceberg and Nessie power data lakehouses, enabling flexible and cost-effective data platforms while minimizing vendor lock-in and data movement challenges.
Will AI Stay Dumb for the Lack of Memory and Storage? - Impact of Storage Technologies on AI Development
Explore the critical relationship between AI advancement and data storage limitations, examining how memory constraints could impact AI's future development and potential solutions.

Advancements in pNFS and NFS v4.2 - Modern Data Center and Cloud Computing Solutions
Discover the latest NFS 4.2 enhancements for high-performance computing, including strategies for unified data orchestration across clouds, GPU clusters, and distributed environments.
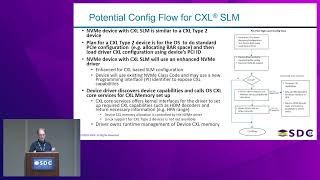
Host Addressable Subsystem Local Memory with NVMe and CXL Integration
Explore the integration of CXL and NVMe protocols, focusing on host addressable Subsystem Local Memory, computational storage benefits, and emerging developments in memory disaggregation.
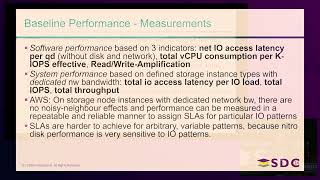
Distributed Data Placement with NVMe-oF - Design and Implementation Challenges
Explore distributed data placement algorithms for cloud storage, focusing on NVMe-oF implementation, scalability challenges, and erasure coding principles in high-performance storage systems.