Drug Repurposing Using Deep Learning on Knowledge Graphs
Explore deep learning on knowledge graphs for drug repurposing, covering graph building, latent relationship prediction, and application to existing drugs for new treatments.
Unified MLOps: Feature Stores and Model Deployment
Explore a new MLOps approach merging databases, feature stores, and ML for scalable model production. Learn about Splice Machine's hybrid database and its applications in feature engineering and model deployment.
PyTorch and COVID-19 Research: Advancements in AI and Data Analysis - Keynotes
Explore PyTorch's advancements in machine learning and learn how AI is helping manage COVID-19 research data, featuring insights on industry adoption and scientific information accessibility.
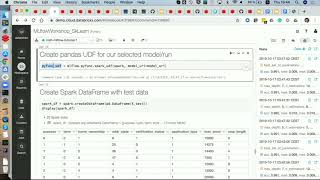
Managing the Complete Machine Learning Lifecycle with MLflow - Part 2
Explore MLflow's capabilities for managing machine learning lifecycles, from data preparation to model deployment, with practical insights on hyperparameter optimization and production workflows.
Machine Learning at Scale with MLflow and Apache Spark
Explore Société Générale's journey in scaling machine learning, focusing on MLflow and Apache Spark for production deployment, CI/CD pipelines, and overcoming challenges in large-scale ML implementation.
Scalable AI for Environmental and Social Impact
Explore Microsoft's AI contributions to Apache Spark and Machine Learning, focusing on environmental and social impact projects like art exploration and endangered species protection.
Predictive Modeling in R With Tidymodels and NFL Attendance
Learn to train predictive models using R's tidymodels framework and NFL game attendance data. Explore data splitting, model building, evaluation, and results visualization techniques.
Topic Modeling with R and Tidy Data Principles
Explore topic modeling in R using tidytext and stm packages, applied to Sherlock Holmes stories. Learn data preparation, text tidying, and model implementation techniques.
Feature Engineering & Interpretability for XGBoost with Board Game Ratings
Explore advanced modeling with board game ratings data: feature engineering, XGBoost tuning, and explainability methods for data-driven insights and predictive analysis.
Topic Modeling for Spice Girls Lyrics
Explore topic modeling using R to analyze Spice Girls lyrics, uncovering hidden themes and patterns in their music through unsupervised machine learning techniques.
Tune and Evaluate a Decision Tree Model with Scooby Doo Episodes
Learn to predict Scooby Doo monster status using decision trees. Explore model tuning, visualization, and simplification techniques with Julia Silge's practical demonstration.
Build Features for Machine Learning from Netflix Description Text
Learn to build machine learning features from Netflix description text and train a support vector machine model using tidymodels, exploring data analysis, feature engineering, and model evaluation techniques.
Subword Features in Machine Learning for Text
Explore machine learning techniques for text analysis using tidymodels to predict Hawaii post offices from their names, with practical code examples and performance evaluation.
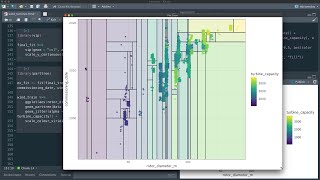
Model Canadian Wind Turbine Capacity With Decision Trees and Tidymodels
Learn to predict Canadian wind turbine capacity using decision trees and tidymodels, with hands-on data preparation, model tuning, and result interpretation techniques.
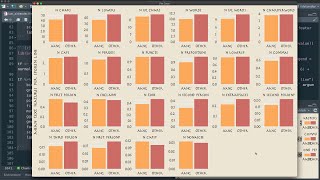
Build a Predictive Text Model for Avatar: The Last Airbender with Tidymodels
Predict Avatar: The Last Airbender speakers using text features and tidymodels in R. Learn model-agnostic variable importance and handle class imbalance in this data analysis tutorial.
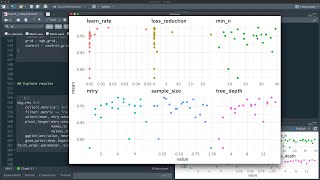
Tuning XGBoost Using Tidymodels
Optimize XGBoost models for beach volleyball match prediction using tidymodels, exploring data, tuning hyperparameters, and interpreting results.
Principal Component Analysis for Hip Hop Songs With Tidymodels
Implement PCA using recipes to analyze the best hip hop songs of all time, exploring Spotify data and visualizing results with tidymodels.
Tuning Random Forest Hyperparameters with Tidymodels
Learn to optimize random forest models using tidymodels, exploring hyperparameter tuning techniques with San Francisco tree data for improved predictive performance.
Hyperparameter Tuning Using Tidymodels
Explore hyperparameter tuning for random forest models using global food consumption data, enhancing model performance and gaining insights into international dietary patterns.
Recommender Systems - Beyond Machine Learning with Joe Konstan
Explore advanced recommender systems beyond machine learning, focusing on user behavior and experience. Learn about successes, failures, and innovative approaches to personalization and evaluation.
Demonstrating an Internet of Things Solution for Real-Time Computation and Delivery of Plant KPIs
Explore an IIoT solution for real-time monitoring of worker performance in meat processing, including project design, implementation, and trial outcomes in an Australian plant.